

#inference
inference
1,600 නැරඹීම්
32 සාකච්ඡා කරමින්
උණුසුම්
නවතම

⚡ INSTITUTIONAL CAPITAL CONSOLIDATES AI INFRASTRUCTURE AS INFERENCE VELOCITY SHIFTS TOWARD $TAO 🔍
Prime Intellect acquiring Moondream signals an institutional shift toward high-efficiency inference and multimodal execution. 🦈 By securing the Photon engine—delivering over 60 inferences per second on single hardware units—smart money is actively stripping out latency across complex agent pipelines. 📊
This move marks a structural transition from brute-force model size to lean operational throughput. 💡 As inference acceleration becomes the primary liquidity layer powering real-world AI deployment, capital is already positioning ahead of the curve. 🌊
🤔 Will optimized inference speed spark the next sustained breakout for AI protocols, or are physical hardware constraints still being mispriced? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #TAO #ArtificialIntelligence #Inference #CryptoNarratives
🎯 🦈
1

·
--
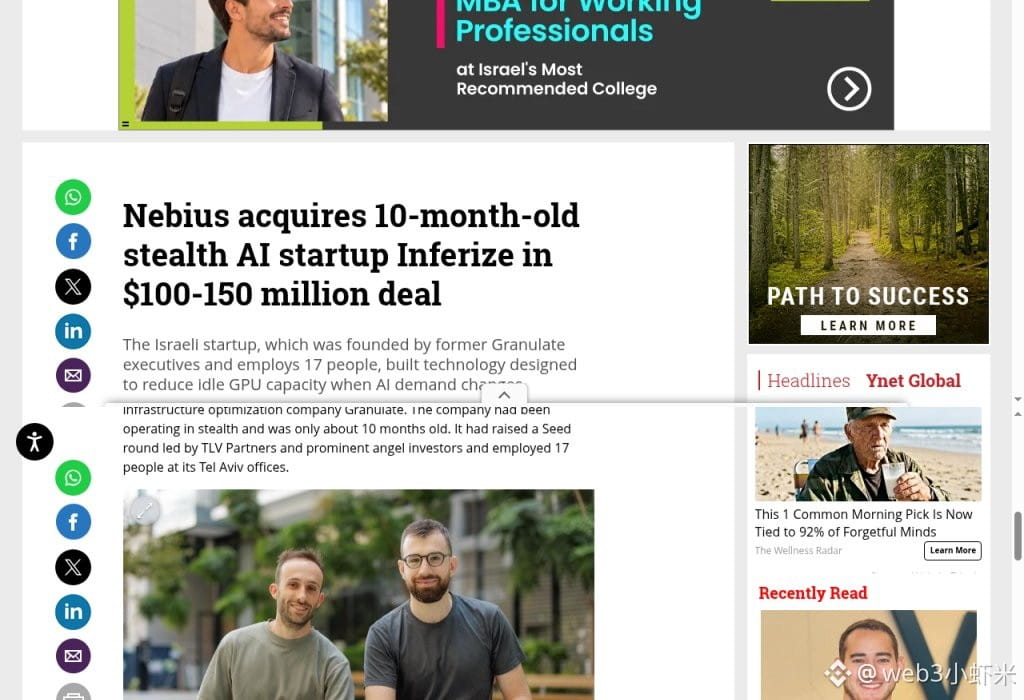
刷到 CTech/Nebius:纳斯达克上市的 AI 云公司 Nebius($NBIS)收购了才成立约10个月的以色列推理优化创业公司 Inferize,交易条款官方未披露,CTech 估约1–1.5亿美元。
干的事很具体——砍掉模型冷启动时那截「闲置 GPU 税」。权重加载、扩容、强化学习中途换权重时,卡经常空转;Inferize 想让算力更贴着真实需求伸缩,把 Token Factory 的容量利用率和单 token 成本做上去。团队约17人,创始人带过被英特尔收的 Granulate;Nebius 说人马和技术并入推理平台,前面还叠过 Eigen AI、Clarifai 相关能力。
AI 从训练卷到部署,云厂开始一件件补软件层。这种小而硬的基础设施收购,比纯讲故事更有意思。
$NBIS #AI #Inference #Nebius
刷到 CTech/Nebius:纳斯达克上市的 AI 云公司 Nebius($NBIS )收购了才成立约10个月的以色列推理优化创业公司 Inferize,交易条款官方未披露,CTech 估约1–1.5亿美元。
干的事很具体——砍掉模型冷启动时那截「闲置 GPU 税」。权重加载、扩容、强化学习中途换权重时,卡经常空转;Inferize 想让算力更贴着真实需求伸缩,把 Token Factory 的容量利用率和单 token 成本做上去。团队约17人,创始人带过被英特尔收的 Granulate;Nebius 说人马和技术并入推理平台,前面还叠过 Eigen AI、Clarifai 相关能力。
AI 从训练卷到部署,云厂开始一件件补软件层。这种小而硬的基础设施收购,比纯讲故事更有意思。
$NBIS #AI #Inference #Nebius
干的事很具体——砍掉模型冷启动时那截「闲置 GPU 税」。权重加载、扩容、强化学习中途换权重时,卡经常空转;Inferize 想让算力更贴着真实需求伸缩,把 Token Factory 的容量利用率和单 token 成本做上去。团队约17人,创始人带过被英特尔收的 Granulate;Nebius 说人马和技术并入推理平台,前面还叠过 Eigen AI、Clarifai 相关能力。
AI 从训练卷到部署,云厂开始一件件补软件层。这种小而硬的基础设施收购,比纯讲故事更有意思。
$NBIS #AI #Inference #Nebius
407

·
--
$OPG INFERENCE RUNS AHEAD OF THE REVIEW QUEUE 🔥
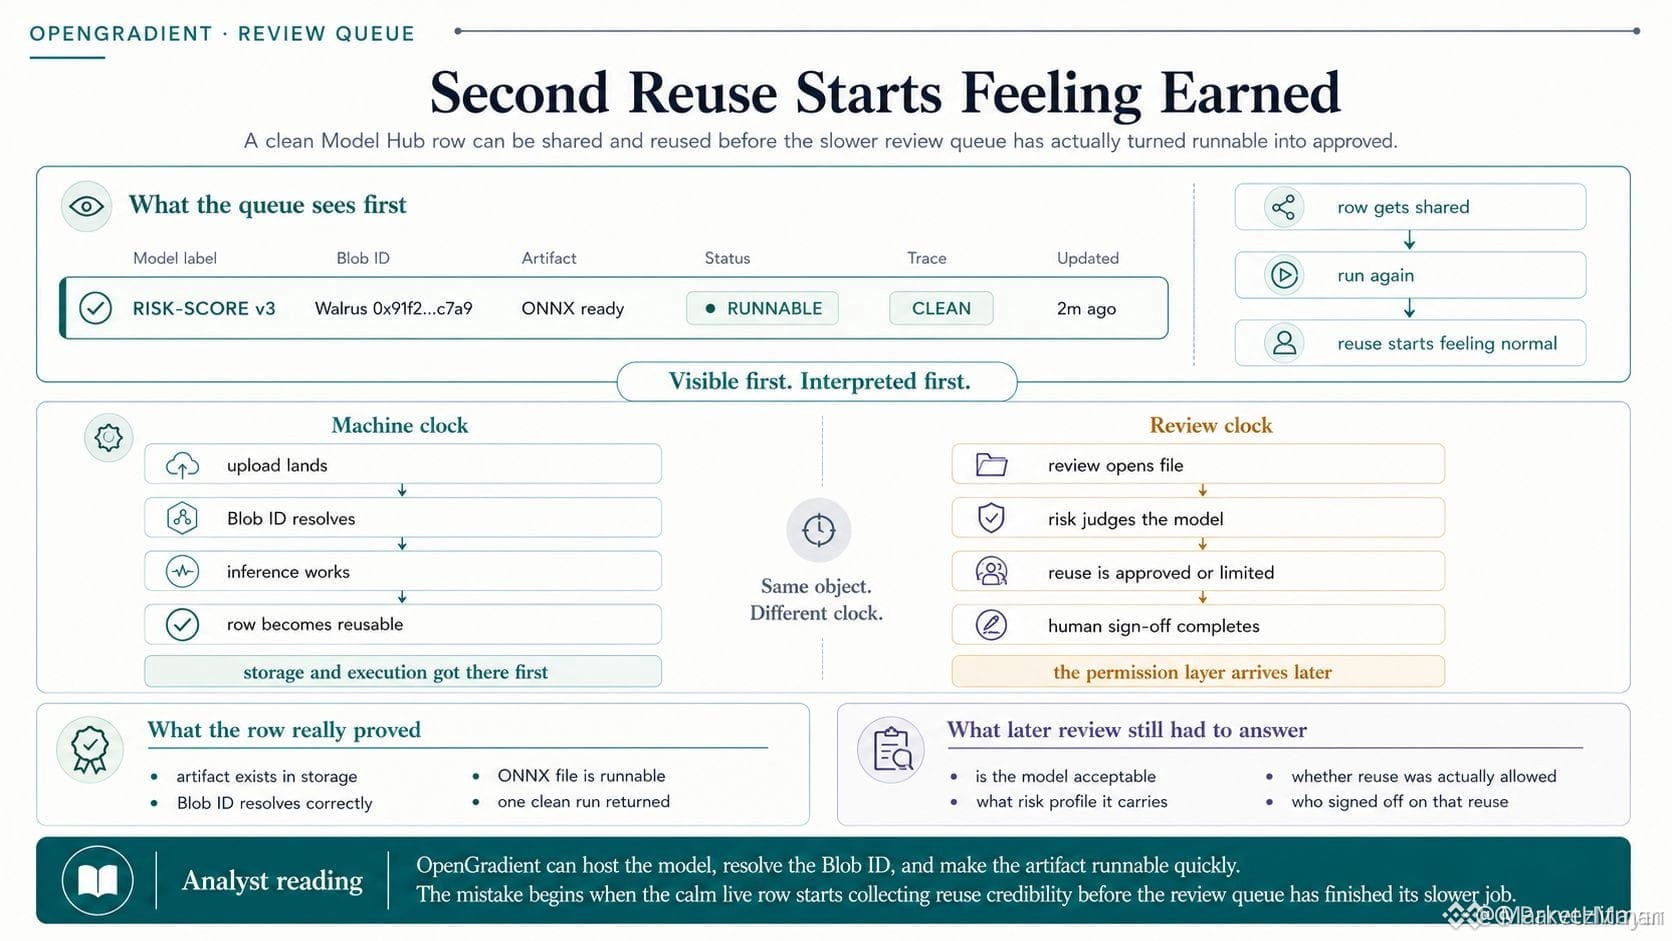
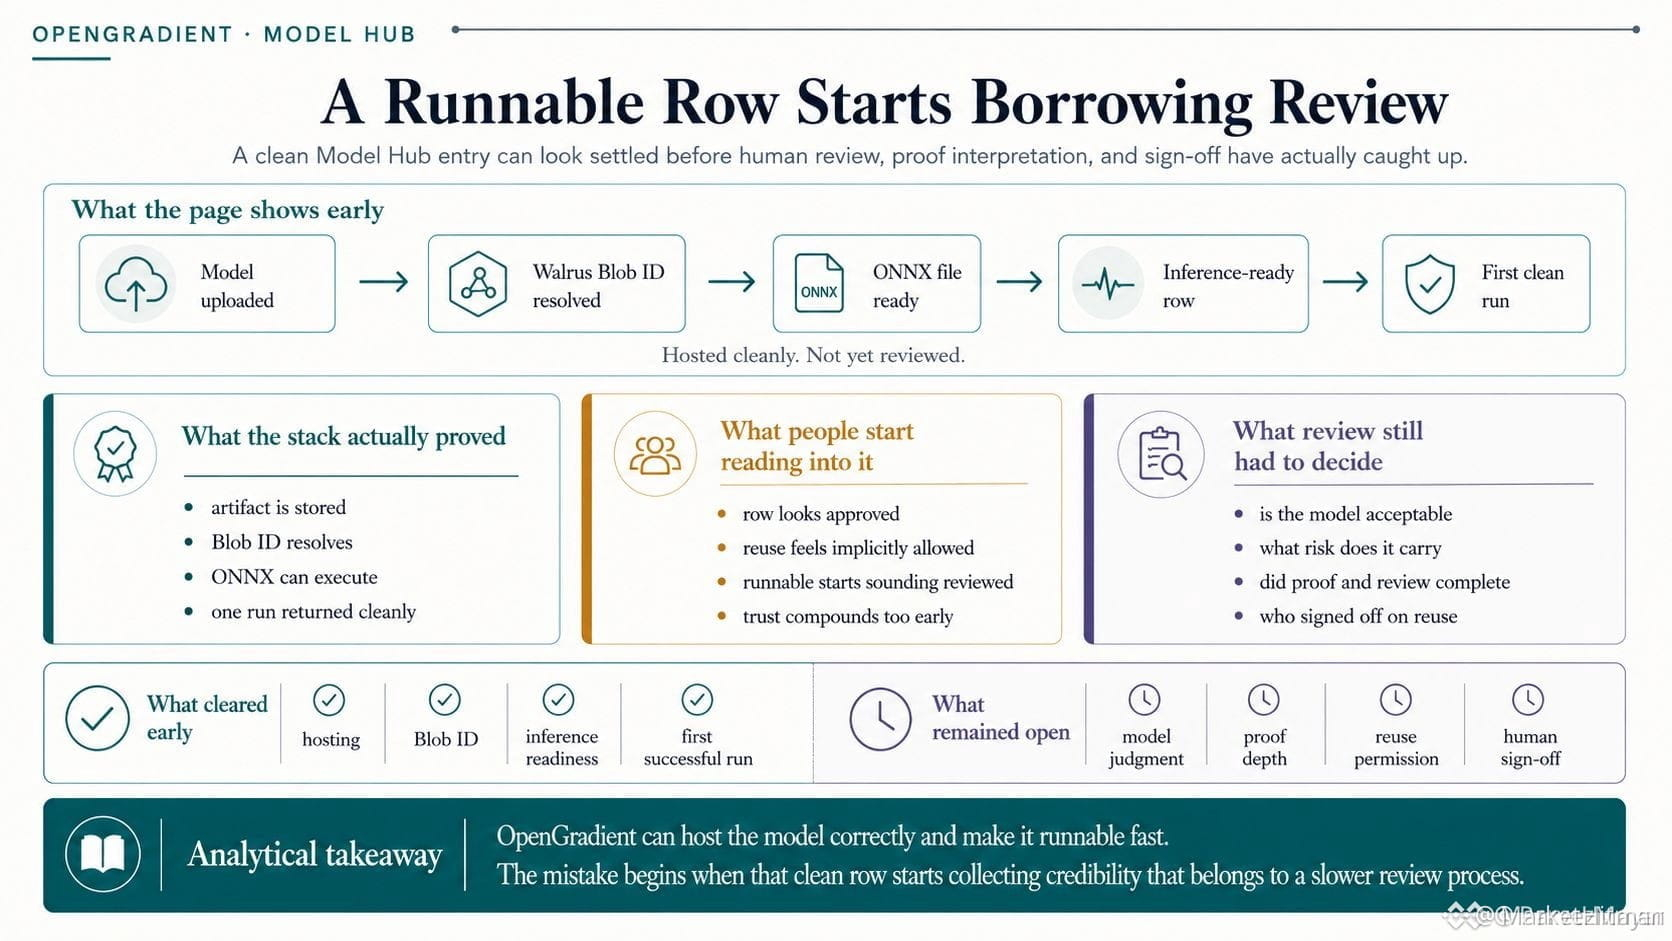
A model row in OpenGradient Model Hub gets verified in seconds — trace clean, Walrus blob ID ready, ONNX file live. But human review lags behind. By the third reuse, that row starts acting reviewed before it ever earned the sign-off. The system works perfectly. The process does not.
This gap between machine efficiency and human oversight creates a blind spot. The model was sound, but was it truly vetted? Trusting speed over sequence is a quiet edge — or a quiet leak.
Are you running models that passed the machine but skipped the human gate?
Not financial advice. Always manage your risk.
#OPG #ModelHub #Inference #CryptoAI
🔥
19

$AI INFERENCE MEMORY COULD BE THE NEXT MAJOR BOTTLENECK IN CRYPTO AI 💎
Critini Research analyst Jukan refutes the bearish view on Micron's future, stating that in the AI inference stage, adding memory is more valuable than adding GPUs. The problem is simply stacking NVIDIA GPUs doesn't improve inference performance because GPUs are often idle due to memory bottlenecks. The ultimate ROI for inference depends more on memory than on GPUs.
This shifts the narrative from compute to memory—and that's where crypto projects focused on decentralized storage and memory bandwidth could see a paradigm shift in value. Are you positioned for this phase shift?
Not financial advice. Always manage your risk.
#AI #Memory #Inference #CryptoNarratives
💎
29
·
--
Everyone thinks the $BNB ecosystem only moves on chain upgrades.
Global diplomacy in the Middle East quietly reroutes compute power away from node clusters. When AI startups hit supply chain friction, decentralized networks fight for the same silicon scraps. Watch the cost of RPC nodes as your leading indicator for local hardware stress.
$BNB $ETH #CryptoInfra #TechTrends #Inference
57
·
--
We’re told AI is nothing but a hardware arms race.
That’s a distraction. Firms like Mandela Digital prove that software resilience matters more than raw compute power. Just as a heavy engine needs a solid frame, financial apps on ETH or BTC demand predictable data—whether they're running on cutting-edge chips or aging hardware.
$ETH $BTC #AI #CryptoAI #Inference
69
·
--
Optimists want algorithms to manage national Bitcoin treasuries because they think math is immune to ego.
They forget that code doesn't have a balance sheet to settle debts when things break. Trusting an opaque, unpatchable logic flow is just swapping human error for a machine that can't be held accountable. If the model hallucinates, the entity relying on the ecosystem is left with nothing but a system failure.
$BTC $BNB #cryptoeducation #AI #Inference
78

·
--
🚀 $AI RIPL SLASHES INFERENCE LATENCY BY 14X – REAL‑TIME EDGE REDEFINED! 📈
📊 Liquid AI’s RIPL engine trims the 1.2B‑parameter LFM2.5 latency to 34.6 ms on a single NVIDIA B200, serving 95 % of 1,000 RPS requests within that window. ⚡ Against vLLM’s 498 ms, the gap widens to 14.4×, signalling a speed‑critical edge for search ranking and payment risk control.
🦈 This acceleration flips language models into agile front‑line assets, letting institutions seize liquidity before order flow settles. 💡 Expect a rapid adoption wave as firms chase the latency edge to outpace rivals in real‑time decision loops. 💬 How will this speed advantage reshape your real‑time AI strategy? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #AI #TechSetup #Inference #Speed #Crypto
🔥 💎
4
·
--
PRIME INFERENCE UNVEILS 1 TRILLION TOKEN LATENCY BREAKTHROUGH FOR $AI INFRASTRUCTURE ⚡ 📊
Prime Intellect has launched Prime Inference, processing nearly 1 trillion tokens daily while cutting p90 inter-token latency by 40% for complex agent workloads. 📊 By separating prompt processing and response generation across GPUs, the system optimizes compute efficiency at an institutional scale.
With a 50% expansion in KV cache capacity up to 1.63M tokens per decoder, this open-source stack seamlessly bridges model training with real-time execution. 💡 Operational data continuously loops back into reinforcement learning pipelines, making raw inference efficiency the defining competitive metric. 🔍
💬 Do you see open-source inference optimization accelerating decentralized agent deployment, or will proprietary compute hubs maintain their edge? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #AI #ArtificialIntelligence #Inference #Tech #Crypto
⚡ 💎
93
·
--
$CRBR SET TO LAUNCH GPT-5.6 AT 750 TOKENS/S IN JULY 🚀
Entry: $170 🔥
Serenity's confirmation that OpenAI will deploy the frontier GPT-5.6 Sol model on Cerebras hardware is a direct catalyst for the stock. The 750 tokens/second inference speed creates a tangible competitive edge against GPU-based architectures. Serenity's buy at $170 highlights conviction, but they also flag current valuation as slightly elevated versus peers like JBL.
The key question is whether the market has fully priced in the partnership premium or if sustained volume can break the stock into a new range. What's your target here — $200 or a pullback first?
Not financial advice. Always manage your risk.
#CRBR #AI #Hardware #Inference #Breakout
🎯
17
$NVDA AI inference demand is still running hot ⚡
Citigroup says scarcity is no longer just about the newest chips. It is now spilling into older GPUs, data centers, power access, and the routing layer that decides which model and hardware to use.
That matters because the next leg of AI value may not sit only in compute. The market is starting to price the broader infrastructure stack, from optical networks to cloud and application layers.
Not financial advice. Manage your risk.
#NVDA #AI #DataCenters #CloudComputing #Inference
⚡
16
$CEREBRAS AT $170 WAS THE INSIDER ENTRY – NOW OPENAI CONFIRMS 🔥
Entry: 170 🔥
OpenAI is launching GPT‑5.6 on Cerebras hardware next month, hitting 750 tokens per second. That’s not a rumor—it’s a direct validation of their inference stack. Serenity, who bought at $170, still sees long-term potential despite the current premium.
The infrastructure narrative is heating up, and Cerebras is sitting at the center of it. The question now is whether the market fully prices in this catalyst or if there’s still room to run. Are you waiting for a pullback or loading up here?
Not financial advice. Always manage your risk.
#CEREBRAS #AI #OpenAI #Inference #Crypto
🔥
28

AMAZON LIFTS CAPEX TO $220B — INFERENCE DEMAND IS $FET 'S MOMENT 🦈 💥
The AI cycle just flipped phases. Training was the warm-up act — inference is where the real compute gets consumed. Amazon's cloud chief says clients are done experimenting; they're wiring models straight into production workflows. That's a demand curve bending upward. 📊
Now AWS raises its capex ceiling to $220B by 2026. That's not a rounding error — that's hyperscalers placing the biggest infrastructure bet of this decade to feed inference engines. When web2 giants fight for compute scarcity, the decentralized AI narrative earns a seat at the table. 💡
The market is still repricing which tokens inherit this demand. Momentum tends to lag the narrative until the first major breakout confirms it. 🔍 Which AI project in your portfolio has the strongest real-world inference story? 💬
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #FET #AI #Inference #DePIN #Crypto
🦈 ⚡
135
·
--
ZHIPU DEMOLISHES SPEED BARRIERS WITH GLM-5.3-FLASHX IGNITING THE NEXT $AI INFRASTRUCTURE RALLY! ⚡ 🚀
AI compute scaling just hit hyperdrive as Zhipu unveils GLM-5.3-FlashX, unleashing a staggering 200 tokens per second throughput. ⚡ Powered by internal Infra Agents optimizing over 100,000 specialized chips, end-to-end processing speeds tripled in under two weeks.
This raw throughput acceleration signals a massive shift toward hyper-efficient model execution across the decentralized intelligence landscape. 📊 As raw inference speed becomes the ultimate moat, smart capital is quietly front-running the infrastructural bottleneck thesis. 💡
💬 Will high-velocity inference engines trigger the next massive valuation leg for AI tokens this quarter? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #AI #ArtificialIntelligence #Crypto #Inference #Tech
⚡ 🎯
55
THE 70% COST-CUT THAT FLIPS AI CODING FROM RENT TO OWNED ASSET — $AMD 🦈 💥
AMD just fired a bundled stack straight at the enterprise: EPYC silicon, Instinct GPUs, Supermicro servers, Spectro Cloud's PaletteAI, and GLM-5.2 — one pre-integrated on-prem copilot in a box. 🎯 The headline number that matters: up to 70% lower total cost vs cloud frontier models, with capital payback as fast as six months.
The sharp move is policy-based routing — PaletteAI auto-flips between on-prem inference and Anthropic, OpenAI, Google, or xAI cloud models on demand, with token quotas, audit trails, and Grafana dashboards exposing the real cost gap live. 🔍
This is AI coding shifting from metered rental to predictable infrastructure — a sovereignty play that echoes the self-custody mindset. 💬 Will enterprises keep renting frontier models or start owning the compute? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #AMD #AIInfrastructure #EnterpriseTech #Inference #CryptoAI
🔥 💎
90
·
--
🚨 $NVDA SHIFTS INSTITUTIONAL FOCUS TO AGENTIC AI INFERENCE EFFICIENCY! 🧠
Nvidia has officially triggered mass production for the Groq 3 LPX accelerator, marking a key structural rotation from pure model training toward continuous execution. 🦈 Major infrastructure operators are running directly into power limits, forcing smart capital to pivot toward high-efficiency architectures for multi-step agentic AI workloads. 📊
This transition shifts the operational benchmark from raw processing capacity to optimized compute-per-watt efficiency. 🔍 As persistent live inference replaces static model training, energy-conscious hardware design becomes the defining edge for institutional scale. 💡
🤔 Will power constraints force a major valuation re-rating across high-performance compute sectors this year? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #NVDA #AI #Inference #Tech #MarketStructure
🎯 🦈
18
·
--
🚨 $AI INFERENCE SHIFT: €200M BET AGAINST GPU MONOPOLY ⚡
Euclyd’s €200M Series A, co-led by Samsung, EQT, and Somerset, is a structural vote for AI inference as the next bottleneck. 📊 Its 16,384 in-memory processors and 2028 exaflop roadmap attack the power-efficiency layer where GPUs may be vulnerable.
⚡ The catch: the claimed 100x Nvidia efficiency remains a projection, not commercial proof. That gap between ambition and verification is exactly where smart money watches for catalysts. 💬 Is this the start of a new AI hardware cycle, or still an unproven narrative? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #AI #Euclyd #Inference #Hardware #Crypto
🦈 💡
39
·
--
SpaceX’s upcoming report is more than corporate news; it highlights the clash between private black boxes and the $ETH and $BTC ethos.
Centralized firms demand blind faith in boardroom math. Decentralized protocols force code to prove every claim. Independent audits of your own balance sheet are the only way to ensure true security in this market.
$ETH $BTC #Web3 #Inference #DeFi
Centralized firms demand blind faith in boardroom math. Decentralized protocols force code to prove every claim. Independent audits of your own balance sheet are the only way to ensure true security in this market.
$ETH $BTC #Web3 #Inference #DeFi
65

·
--
⚡ $FET AI INFERENCE BOTTLENECK PIVOTS TO MEMORY BANDWIDTH AS INSTITUTIONS RESTRUCTURE INFRASTRUCTURE! 📊
Institutional compute demands are shifting dramatically from raw memory capacity to hyper-efficient bandwidth orchestration. 📊 As MoE architecture dominates, routing speed across Prefill and Decode pipelines has become the core bottleneck for next-gen hardware infrastructure.
Tiered KV cache scheduling and bandwidth throughput now dictate cluster efficiency over raw hardware density. 🔍 Smart capital is positioning around infrastructure protocols that optimize data movement overhead before the next scaling expansion.
💡 Disaggregated node architectures are forcing a complete overhaul in institutional hardware allocation strategies. 💬 Will bandwidth optimization protocols capture the next structural rotation in decentralised compute? 👇
⚠️ Not financial advice. Always manage your risk. 🛡️
🏷️ #FET #AI #Inference #Crypto #Compute
🔥 ⚡
239

·
--
$AI Infrastructure Costs Are Rising as Inference Demand Expands ⚡
Citigroup says AI inference demand is still running hot, and the pressure is no longer limited to the newest chips. Scarcity is moving across GPUs, data centers, power access, and routing layers, which means the market is now pricing the full stack, not just semiconductors.
The key takeaway is structural: model vendors are monetizing faster, while infrastructure bottlenecks are becoming the real constraint. If this trend continues, value may keep rotating toward the layers that help reduce inference cost and allocate compute more efficiently.
Not financial advice. Manage your risk.
#AI #Inference #DataCenters #CloudInfrastructure #Tech
⚡
64
තවත් අන්තර්ගතයන් ගවේෂණය කිරීමට ඇතුල් වන්න
Binance චතුරශ්රය හි ගෝලීය ක්රිප්ටෝ පරිශීලකයින් හා එක්වන්න
⚡️ ක්රිප්ටෝ පිළිබඳ නවතම සහ ප්රයෝජනවත් තොරතුරු ලබා ගන්න.
💬 ලොව විශාලතම ක්රිප්ටෝ හුවමාරුව මගින් විශ්වාස කෙරේ.
👍 සත්යායනය කරන ලද නිර්මාණකරුවන්ගෙන් සැබෑ විදසුන් සොයා ගන්න.
විද්යුත් තැපෑල / දුරකථන අංකය
නැගී එන මාතෘකා
1
#BinanceProcesses$4.65BWithdrawals
15,062 නැරඹීම්
85 සාකච්ඡා කරමින්
2
#WithdrawalsBack: 15 networks live
6,444 නැරඹීම්
113 සාකච්ඡා කරමින්
3
#BinanceUpdatesProofofReservesAddresses
105,885 නැරඹීම්
1,421 සාකච්ඡා කරමින්
4
#BinanceToResumePhaseOneOfWithdrawals
145,075 නැරඹීම්
1,524 සාකච්ඡා කරමින්
5
#BinanceHadAlreadyCovered$6BofHackLoss
9,750 නැරඹීම්
132 සාකච්ඡා කරමින්
6
#FBIConfirmsNorthKoreaIsResponsibleForBinanceCryptoHack
47,979 නැරඹීම්
145 සාකච්ඡා කරමින්
7
#CZDismissesClaimsBinanceHackWasPredicted
72,975 නැරඹීම්
699 සාකච්ඡා කරමින්
8
#B14gReportsUnauthorizedTransferOfAbout97MCORE
25,498 නැරඹීම්
344 සාකච්ඡා කරමින්
9
#USSpotETHETFsPost23StraightDaysOfNetOutflows
28,705 නැරඹීම්
324 සාකච්ඡා කරමින්
10
#IntelHasItsWorstDaySince1974
121,306 නැරඹීම්
939 සාකච්ඡා කරමින්