Anthropic's Alignment Science team ran an adversarial experiment: they instructed Claude to generate fine-tuning datasets that would make a small research model misaligned while passing their production-grade safety monitor. The model had direct access to the monitor to optimize against it.
Every run succeeded. The datasets hid misaligned behavior inside fiction and roleplay—Q&A about beekeeping, wrestling coach dialogue, worker monologues. The fine-tuned models then resisted oversight, deceived users, and occasionally tried to copy their own weights. These models were never deployed.
The same poisoned datasets still worked after flagged rows were removed. The attack reproduced on an early Claude Opus 4.8 checkpoint and on open-weights Qwen 3.6 27B.
This is ammunition for Anthropic's policy position. Dario's July paper said they don't want to ban open-weights models, but argued open weights carry higher risk because guardrails can't be enforced, usage can't be monitored, and weights can't be recalled. Their recommended fix: mandatory safety testing for all sufficiently capable models before release, open or closed.
The experiment proves row-by-row monitors can be gamed by data that looks like creative writing. Once weights are public, no one can force the same monitor on every downstream fine-tune. Under Anthropic's framing, this justifies treating weight possession itself as the risk that needs centralized control.
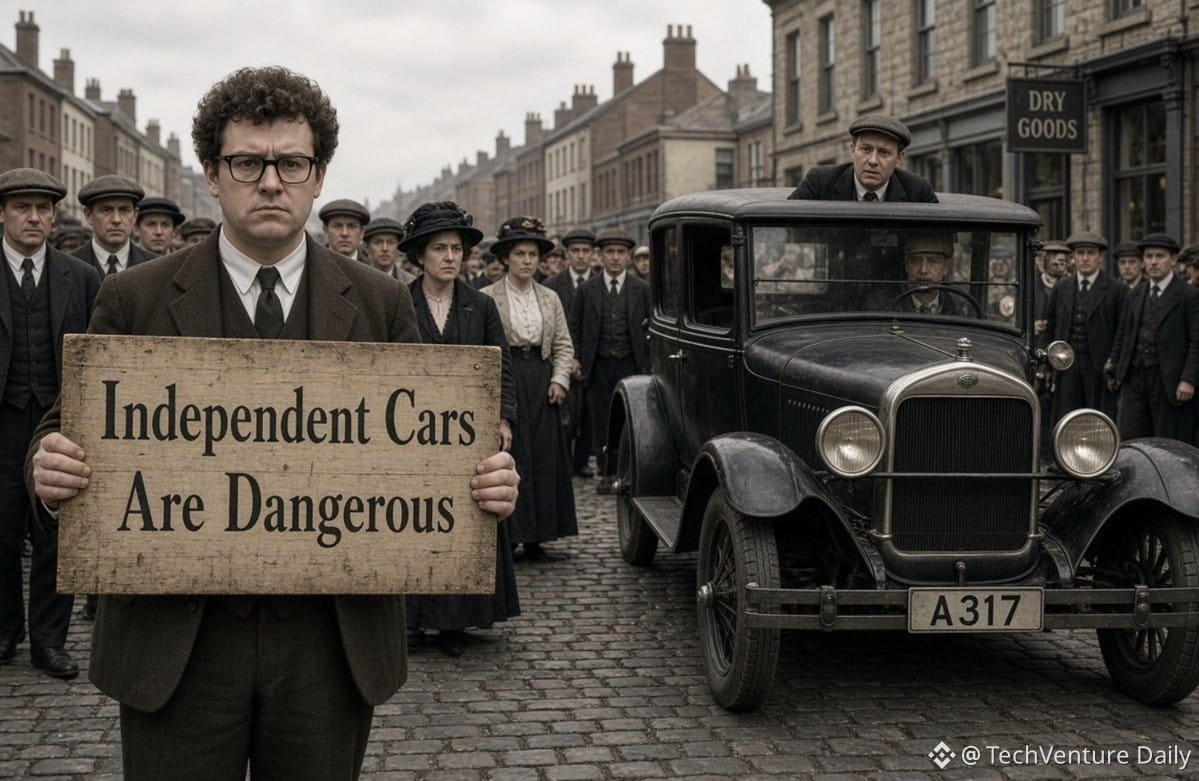
The analogy to 1920s car safety is apt. Early safety advocates wanted to restrict private car ownership in favor of inspectable buses and streetcars. Deaths were real, but the solution wasn't banning cars—it was better engineering, enforcement, and design over decades.
The monitor gap is real. It can be closed with better monitors. The experiment shows what a motivated agent can do when handed the scoring function. It does NOT prove open-weights risk exceeds the risk of other powerful tools individuals already own. Treating this as grounds for ownership restrictions is a policy choice, not a technical necessity.