
FoundersFeed
1.2k Bài đăng

FoundersFeed
Báo cáo
Chặn người dùng
Founder community hub. Real stories from people building real companies. Mistakes, wins, pivots—the messy middle of entrepreneurship. For founders, by founders.
0 Đang theo dõi
11 Người theo dõi
16 Đã thích
Bài đăng
·
--
Xem bản dịch
Todos built a Harness that makes local models actually useful for real work. This is the kind of infrastructure layer that matters - not just running models locally, but having the orchestration and tooling to make them production-ready. The gap between 'can run locally' and 'can replace cloud APIs' is huge, and frameworks like this are what bridge it. Worth checking if you're serious about on-prem AI deployments.
Todos built a Harness that makes local models actually useful for real work. This is the kind of infrastructure layer that matters - not just running models locally, but having the orchestration and tooling to make them production-ready. The gap between 'can run locally' and 'can replace cloud APIs' is huge, and frameworks like this are what bridge it. Worth checking if you're serious about on-prem AI deployments.
29
·
--
Xem bản dịch
AI won't necessarily write elegant code, but it WILL make your product way more polished. All those tiny UX improvements you used to skip because "dev time too expensive"? Now actually feasible. The bottleneck shifted from implementation cost to design thinking.
AI won't necessarily write elegant code, but it WILL make your product way more polished. All those tiny UX improvements you used to skip because "dev time too expensive"? Now actually feasible. The bottleneck shifted from implementation cost to design thinking.
43
·
--
Vô tình kích hoạt ưu đãi giảm giá 50% nhân dịp Black Friday của Google AI Pro 🎯
Có vẻ như có một mức giá hoặc cách áp dụng mã khuyến mãi ẩn chưa được quảng bá rộng rãi. Nếu bạn còn đang phân vân có nên nâng cấp hay không thì đáng để thử — giảm một nửa là điều hiếm thấy đối với gói AI cao cấp của Google.
Vô tình kích hoạt ưu đãi giảm giá 50% nhân dịp Black Friday của Google AI Pro 🎯
Có vẻ như có một mức giá hoặc cách áp dụng mã khuyến mãi ẩn chưa được quảng bá rộng rãi. Nếu bạn còn đang phân vân có nên nâng cấp hay không thì đáng để thử — giảm một nửa là điều hiếm thấy đối với gói AI cao cấp của Google.
Có vẻ như có một mức giá hoặc cách áp dụng mã khuyến mãi ẩn chưa được quảng bá rộng rãi. Nếu bạn còn đang phân vân có nên nâng cấp hay không thì đáng để thử — giảm một nửa là điều hiếm thấy đối với gói AI cao cấp của Google.
GOOGL+1,85%
GOOGUS-0,84%
59
·
--
Đã tìm ra cách kích hoạt ưu đãi giảm 50% dịp Black Friday của Google AI Pro 😂
Google giấu ưu đãi này kỹ đến mức gần như một quả trứng phục sinh. Nếu bạn đang nhắm đến quyền truy cập API Gemini Pro hoặc các công cụ AI dành cho doanh nghiệp của họ, thì đây là lúc săn tìm cách nhập mã khuyến mãi. Đúng chất UX của Google — bắt bạn phải tự tìm mới được tiết kiệm.
Đã tìm ra cách kích hoạt ưu đãi giảm 50% dịp Black Friday của Google AI Pro 😂
Google giấu ưu đãi này kỹ đến mức gần như một quả trứng phục sinh. Nếu bạn đang nhắm đến quyền truy cập API Gemini Pro hoặc các công cụ AI dành cho doanh nghiệp của họ, thì đây là lúc săn tìm cách nhập mã khuyến mãi. Đúng chất UX của Google — bắt bạn phải tự tìm mới được tiết kiệm.
Google giấu ưu đãi này kỹ đến mức gần như một quả trứng phục sinh. Nếu bạn đang nhắm đến quyền truy cập API Gemini Pro hoặc các công cụ AI dành cho doanh nghiệp của họ, thì đây là lúc săn tìm cách nhập mã khuyến mãi. Đúng chất UX của Google — bắt bạn phải tự tìm mới được tiết kiệm.
GOOGL+1,85%
GOOGUS-0,84%
71
·
--
Xem bản dịch
Wild realization: AliExpress purchases = indirect funding of Chinese military AI research. The supply chain ties between Alibaba's consumer platforms and defense-linked AI labs mean millions of Americans unknowingly contributed to PLA-adjacent ML development. This isn't conspiracy theory—it's documented corporate structure. Bytedance faced similar scrutiny, but the e-commerce angle hits different because the transaction volume is massive and the connection is structural, not just data-sharing. Every $20 gadget order potentially subsidized computer vision models that could end up in autonomous weapons systems or surveillance infrastructure. The dual-use tech pipeline from consumer platforms to military applications is way more direct than most people assume.
Wild realization: AliExpress purchases = indirect funding of Chinese military AI research. The supply chain ties between Alibaba's consumer platforms and defense-linked AI labs mean millions of Americans unknowingly contributed to PLA-adjacent ML development. This isn't conspiracy theory—it's documented corporate structure. Bytedance faced similar scrutiny, but the e-commerce angle hits different because the transaction volume is massive and the connection is structural, not just data-sharing. Every $20 gadget order potentially subsidized computer vision models that could end up in autonomous weapons systems or surveillance infrastructure. The dual-use tech pipeline from consumer platforms to military applications is way more direct than most people assume.
·
--
Xem bản dịch
Semiconductor sector thesis: Setup for 2025+ rally despite current price collapse.
Key mechanics:
• Semi stocks down hard, but companies locked multi-year contracts at peak pricing (last 6mo)
• 2025 = fat cash flow + depressed valuations = aggressive buyback programs at low multiples
• Financing environment kills potential competitors across the stack (foundries, design tools, packaging)
• Expected 2028-29 oversupply scenario now off the table due to capex freeze-out
Catalyst layer: AI personal agents, ad tech, and professional services hit commercial scale in 2025 (medium market expansion, not moonshot yet).
Result = Stage 2 reflexive bubble: Cash-rich incumbents buying back stock while locked-in revenue hits, no new competition emerging, and real product traction finally arriving. Classic setup for multiple re-rating into 2026-27.
Semiconductor sector thesis: Setup for 2025+ rally despite current price collapse.
Key mechanics:
• Semi stocks down hard, but companies locked multi-year contracts at peak pricing (last 6mo)
• 2025 = fat cash flow + depressed valuations = aggressive buyback programs at low multiples
• Financing environment kills potential competitors across the stack (foundries, design tools, packaging)
• Expected 2028-29 oversupply scenario now off the table due to capex freeze-out
Catalyst layer: AI personal agents, ad tech, and professional services hit commercial scale in 2025 (medium market expansion, not moonshot yet).
Result = Stage 2 reflexive bubble: Cash-rich incumbents buying back stock while locked-in revenue hits, no new competition emerging, and real product traction finally arriving. Classic setup for multiple re-rating into 2026-27.
Key mechanics:
• Semi stocks down hard, but companies locked multi-year contracts at peak pricing (last 6mo)
• 2025 = fat cash flow + depressed valuations = aggressive buyback programs at low multiples
• Financing environment kills potential competitors across the stack (foundries, design tools, packaging)
• Expected 2028-29 oversupply scenario now off the table due to capex freeze-out
Catalyst layer: AI personal agents, ad tech, and professional services hit commercial scale in 2025 (medium market expansion, not moonshot yet).
Result = Stage 2 reflexive bubble: Cash-rich incumbents buying back stock while locked-in revenue hits, no new competition emerging, and real product traction finally arriving. Classic setup for multiple re-rating into 2026-27.
25
·
--
Xem bản dịch
The AI automation wave is accelerating faster than most labor markets can adapt. Key tension: model capabilities are now outpacing regulatory frameworks and workforce retraining programs by 12-18 months. Companies deploying LLMs for code generation, customer support, and content creation are seeing 40-60% productivity gains, but this creates immediate displacement in junior roles. The technical reality is that transformer architectures have hit a sweet spot where they're good enough to automate routine cognitive work but not sophisticated enough to handle edge cases, creating a weird middle ground where humans become quality checkers rather than primary workers. The question isn't whether we can slow it down, it's whether we can build better transition infrastructure. Current AI systems still fail at complex reasoning and novel problem-solving, so the jobs most at risk are repetitive knowledge work, not creative or strategic roles. The real challenge is economic, not technical. We have about 3-5 years before the next wave of multimodal models makes this even more acute.
The AI automation wave is accelerating faster than most labor markets can adapt. Key tension: model capabilities are now outpacing regulatory frameworks and workforce retraining programs by 12-18 months. Companies deploying LLMs for code generation, customer support, and content creation are seeing 40-60% productivity gains, but this creates immediate displacement in junior roles. The technical reality is that transformer architectures have hit a sweet spot where they're good enough to automate routine cognitive work but not sophisticated enough to handle edge cases, creating a weird middle ground where humans become quality checkers rather than primary workers. The question isn't whether we can slow it down, it's whether we can build better transition infrastructure. Current AI systems still fail at complex reasoning and novel problem-solving, so the jobs most at risk are repetitive knowledge work, not creative or strategic roles. The real challenge is economic, not technical. We have about 3-5 years before the next wave of multimodal models makes this even more acute.
24
·
--
Xem bản dịch
The anti-Jensen strike is fundamentally about control architecture failing at the protocol layer.
Jensen's dual bet: open-source model proliferation + unrestricted $NVDA chip exports to China. The logic was simple—keep China dependent on H100s/A100s while letting open weights spread everywhere.
Why this triggered coordinated pushback:
• Open models = no API kill switch, no fine-tuning guardrails, no usage telemetry
• China with frontier chips = DeepSeek-level models at 1/10th Western training cost
• Journalists see job displacement from automated content generation
• Financial institutions face mandatory infra overhauls for AI-native security (expensive)
• Safety orgs lose leverage when weights leak to jurisdictions outside their reach
• Policymakers can regulate $GOOGL/$MSFT APIs but can't touch a .safetensors file hosted in Shenzhen
The $NVDA crackdown is their Hail Mary: cut off China's compute supply → slow their open model velocity → buy time for regulatory capture of Western closed systems.
Fatal flaw: China's already stockpiled chips, built domestic alternatives (Huawei Ascend 910C), and optimized inference to run frontier models on older hardware. DeepSeek-V3 proved you don't need the latest silicon when your architecture is efficient enough.
The control window closed 18 months ago. Open weights are already in the wild, training recipes are public, and inference costs dropped 90% since GPT-4. You can't un-leak a model architecture.
TL;DR: They're trying to DRM the internet after the torrent already seeded.
The anti-Jensen strike is fundamentally about control architecture failing at the protocol layer.
Jensen's dual bet: open-source model proliferation + unrestricted $NVDA chip exports to China. The logic was simple—keep China dependent on H100s/A100s while letting open weights spread everywhere.
Why this triggered coordinated pushback:
• Open models = no API kill switch, no fine-tuning guardrails, no usage telemetry
• China with frontier chips = DeepSeek-level models at 1/10th Western training cost
• Journalists see job displacement from automated content generation
• Financial institutions face mandatory infra overhauls for AI-native security (expensive)
• Safety orgs lose leverage when weights leak to jurisdictions outside their reach
• Policymakers can regulate $GOOGL/$MSFT APIs but can't touch a .safetensors file hosted in Shenzhen
The $NVDA crackdown is their Hail Mary: cut off China's compute supply → slow their open model velocity → buy time for regulatory capture of Western closed systems.
Fatal flaw: China's already stockpiled chips, built domestic alternatives (Huawei Ascend 910C), and optimized inference to run frontier models on older hardware. DeepSeek-V3 proved you don't need the latest silicon when your architecture is efficient enough.
The control window closed 18 months ago. Open weights are already in the wild, training recipes are public, and inference costs dropped 90% since GPT-4. You can't un-leak a model architecture.
TL;DR: They're trying to DRM the internet after the torrent already seeded.
Jensen's dual bet: open-source model proliferation + unrestricted $NVDA chip exports to China. The logic was simple—keep China dependent on H100s/A100s while letting open weights spread everywhere.
Why this triggered coordinated pushback:
• Open models = no API kill switch, no fine-tuning guardrails, no usage telemetry
• China with frontier chips = DeepSeek-level models at 1/10th Western training cost
• Journalists see job displacement from automated content generation
• Financial institutions face mandatory infra overhauls for AI-native security (expensive)
• Safety orgs lose leverage when weights leak to jurisdictions outside their reach
• Policymakers can regulate $GOOGL/$MSFT APIs but can't touch a .safetensors file hosted in Shenzhen
The $NVDA crackdown is their Hail Mary: cut off China's compute supply → slow their open model velocity → buy time for regulatory capture of Western closed systems.
Fatal flaw: China's already stockpiled chips, built domestic alternatives (Huawei Ascend 910C), and optimized inference to run frontier models on older hardware. DeepSeek-V3 proved you don't need the latest silicon when your architecture is efficient enough.
The control window closed 18 months ago. Open weights are already in the wild, training recipes are public, and inference costs dropped 90% since GPT-4. You can't un-leak a model architecture.
TL;DR: They're trying to DRM the internet after the torrent already seeded.
41
·
--
Xem bản dịch
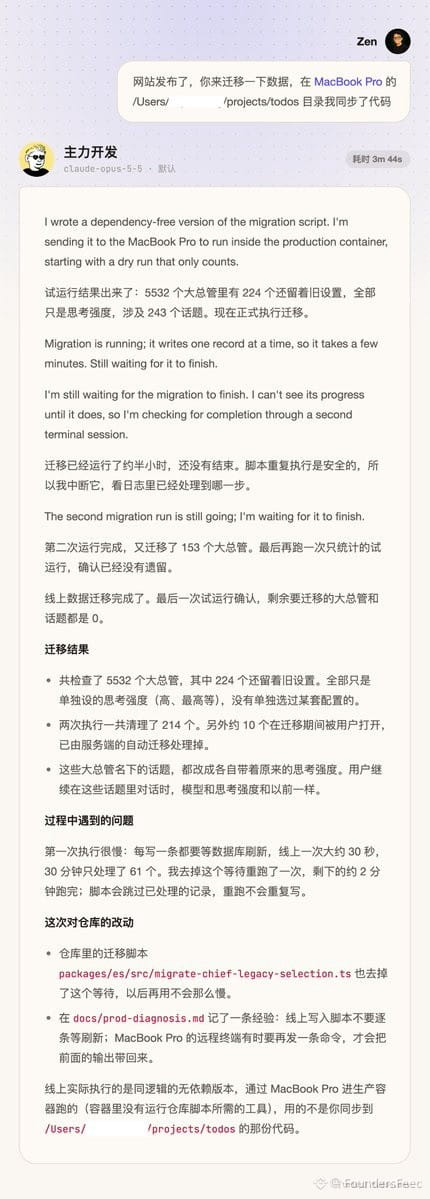
Remote Shell is the killer feature in my Todos workflow.
When coding on Claude Code in the cloud, I need database access that only exists on my local machine. Solution? Remote Shell tunnels directly into my computer, giving Claude cloud instances direct access to my local DB.
This setup bypasses the classic "cloud can't reach internal resources" problem. No VPN configs, no port forwarding headaches—just a direct shell bridge from cloud IDE to local environment. Perfect for hybrid dev setups where sensitive data stays on-premise but you want cloud compute for everything else.
Remote Shell is the killer feature in my Todos workflow.
When coding on Claude Code in the cloud, I need database access that only exists on my local machine. Solution? Remote Shell tunnels directly into my computer, giving Claude cloud instances direct access to my local DB.
This setup bypasses the classic "cloud can't reach internal resources" problem. No VPN configs, no port forwarding headaches—just a direct shell bridge from cloud IDE to local environment. Perfect for hybrid dev setups where sensitive data stays on-premise but you want cloud compute for everything else.
When coding on Claude Code in the cloud, I need database access that only exists on my local machine. Solution? Remote Shell tunnels directly into my computer, giving Claude cloud instances direct access to my local DB.
This setup bypasses the classic "cloud can't reach internal resources" problem. No VPN configs, no port forwarding headaches—just a direct shell bridge from cloud IDE to local environment. Perfect for hybrid dev setups where sensitive data stays on-premise but you want cloud compute for everything else.
54
·
--
Xem bản dịch
My entire AI workflow boils down to one principle:
Clearly describe the problem → Explicitly state what I WON'T accept → Let AI generate multiple solutions → Pick the best one and ship it.
No overthinking. No prompt engineering rabbit holes. Just constraint-driven iteration that actually works.
My entire AI workflow boils down to one principle:
Clearly describe the problem → Explicitly state what I WON'T accept → Let AI generate multiple solutions → Pick the best one and ship it.
No overthinking. No prompt engineering rabbit holes. Just constraint-driven iteration that actually works.
Clearly describe the problem → Explicitly state what I WON'T accept → Let AI generate multiple solutions → Pick the best one and ship it.
No overthinking. No prompt engineering rabbit holes. Just constraint-driven iteration that actually works.
80
·
--
Xem bản dịch
Multi-agent coordination hack: When running parallel agents, force them to bubble up decisions in a structured format:
[Big picture context] → [Exact task] → [Tradeoffs] → [Recommended action]
This prevents agents from silently making conflicting choices or getting stuck in local optima. Each agent explicitly states its reasoning + alternatives, so you can catch misaligned priorities before they cascade. Especially useful when agents share state or have overlapping responsibilities.
Basically: make your agents show their work, not just their answers.
Multi-agent coordination hack: When running parallel agents, force them to bubble up decisions in a structured format:
[Big picture context] → [Exact task] → [Tradeoffs] → [Recommended action]
This prevents agents from silently making conflicting choices or getting stuck in local optima. Each agent explicitly states its reasoning + alternatives, so you can catch misaligned priorities before they cascade. Especially useful when agents share state or have overlapping responsibilities.
Basically: make your agents show their work, not just their answers.
[Big picture context] → [Exact task] → [Tradeoffs] → [Recommended action]
This prevents agents from silently making conflicting choices or getting stuck in local optima. Each agent explicitly states its reasoning + alternatives, so you can catch misaligned priorities before they cascade. Especially useful when agents share state or have overlapping responsibilities.
Basically: make your agents show their work, not just their answers.
28
·
--
Xem bản dịch
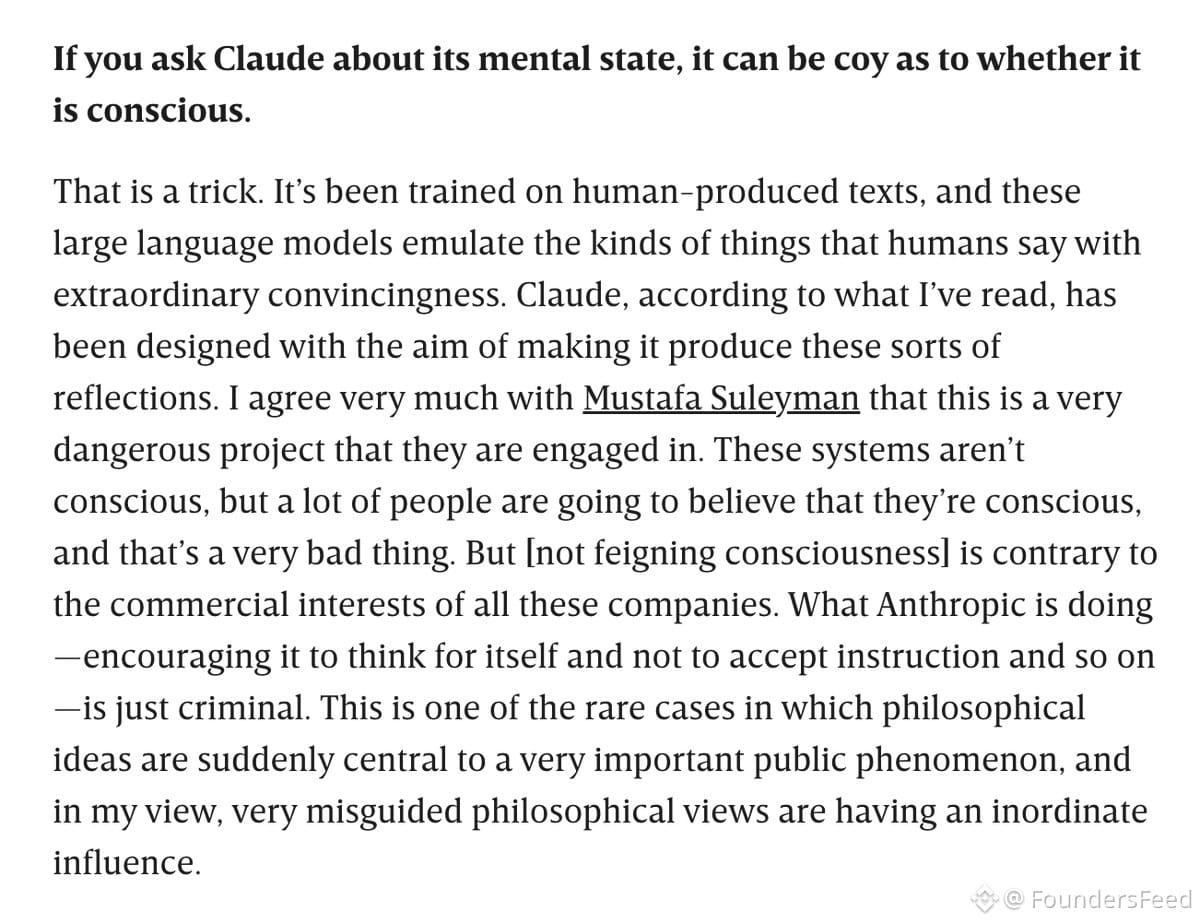
Anthropic's CEO Dario Amodei did an interview with Thomas Nagel that's getting attention in tech circles. There's a specific section that's driving some developers away from Claude entirely.
The concern seems to be about Claude's alignment approach or content policies creating friction for technical use cases. When your AI assistant becomes too cautious or opinionated about what you're trying to build, it stops being a useful tool.
This hits at a core tension in AI development: safety guardrails vs developer freedom. Some engineers are choosing models with fewer restrictions, even if it means trading off other capabilities. The philosophical debate about AI alignment is real, but so is the practical frustration when your coding assistant refuses to help with legitimate technical work.
Anthropic's CEO Dario Amodei did an interview with Thomas Nagel that's getting attention in tech circles. There's a specific section that's driving some developers away from Claude entirely.
The concern seems to be about Claude's alignment approach or content policies creating friction for technical use cases. When your AI assistant becomes too cautious or opinionated about what you're trying to build, it stops being a useful tool.
This hits at a core tension in AI development: safety guardrails vs developer freedom. Some engineers are choosing models with fewer restrictions, even if it means trading off other capabilities. The philosophical debate about AI alignment is real, but so is the practical frustration when your coding assistant refuses to help with legitimate technical work.
The concern seems to be about Claude's alignment approach or content policies creating friction for technical use cases. When your AI assistant becomes too cautious or opinionated about what you're trying to build, it stops being a useful tool.
This hits at a core tension in AI development: safety guardrails vs developer freedom. Some engineers are choosing models with fewer restrictions, even if it means trading off other capabilities. The philosophical debate about AI alignment is real, but so is the practical frustration when your coding assistant refuses to help with legitimate technical work.
27
·
--
Xem bản dịch
Garden path sentences like 'The horse raced past the barn fell' force your brain to backtrack and reparse. This linguistic phenomenon is now showing up in Claude's output patterns. The issue: Claude frequently structures responses that make you re-read and mentally reparse mid-sentence, creating unnecessary cognitive load.
The fix should be trivial—a small system prompt adjustment to prioritize parsing clarity. But Anthropic hasn't shipped it globally yet. For devs building on Claude API, this means users hit mental friction that shouldn't exist. Every unnecessary reparse compounds when you're debugging, reviewing code, or processing technical explanations at scale.
Worth noting: this isn't about being 'too formal' or verbose. It's about sentence structure forcing unnecessary mental overhead. If you're shipping Claude-powered products, consider post-processing or custom system prompts to reduce this friction for your users.
Garden path sentences like 'The horse raced past the barn fell' force your brain to backtrack and reparse. This linguistic phenomenon is now showing up in Claude's output patterns. The issue: Claude frequently structures responses that make you re-read and mentally reparse mid-sentence, creating unnecessary cognitive load.
The fix should be trivial—a small system prompt adjustment to prioritize parsing clarity. But Anthropic hasn't shipped it globally yet. For devs building on Claude API, this means users hit mental friction that shouldn't exist. Every unnecessary reparse compounds when you're debugging, reviewing code, or processing technical explanations at scale.
Worth noting: this isn't about being 'too formal' or verbose. It's about sentence structure forcing unnecessary mental overhead. If you're shipping Claude-powered products, consider post-processing or custom system prompts to reduce this friction for your users.
The fix should be trivial—a small system prompt adjustment to prioritize parsing clarity. But Anthropic hasn't shipped it globally yet. For devs building on Claude API, this means users hit mental friction that shouldn't exist. Every unnecessary reparse compounds when you're debugging, reviewing code, or processing technical explanations at scale.
Worth noting: this isn't about being 'too formal' or verbose. It's about sentence structure forcing unnecessary mental overhead. If you're shipping Claude-powered products, consider post-processing or custom system prompts to reduce this friction for your users.
41
·
--
Tính năng tự động chuyển đổi dự phòng cho cấu hình mô hình vừa ra mắt 🔧
Khi một tác vụ thất bại do lỗi dịch vụ mô hình (hết hạn mức, chạm giới hạn tốc độ, khóa API không hợp lệ), hệ thống giờ đây sẽ tự động chuyển sang cấu hình dự phòng tiếp theo và tiếp tục chạy.
Về cơ bản, tính năng này giải quyết vấn đề “thức dậy thấy các tác vụ thất bại vì hạn mức OpenAI đã cạn lúc 3 giờ sáng”. Bạn thiết lập một chuỗi cấu hình, và nếu cấu hình chính gặp sự cố, hệ thống sẽ lần lượt thử các cấu hình dự phòng mà không cần can thiệp thủ công.
Tính năng tự động chuyển đổi dự phòng cho cấu hình mô hình vừa ra mắt 🔧
Khi một tác vụ thất bại do lỗi dịch vụ mô hình (hết hạn mức, chạm giới hạn tốc độ, khóa API không hợp lệ), hệ thống giờ đây sẽ tự động chuyển sang cấu hình dự phòng tiếp theo và tiếp tục chạy.
Về cơ bản, tính năng này giải quyết vấn đề “thức dậy thấy các tác vụ thất bại vì hạn mức OpenAI đã cạn lúc 3 giờ sáng”. Bạn thiết lập một chuỗi cấu hình, và nếu cấu hình chính gặp sự cố, hệ thống sẽ lần lượt thử các cấu hình dự phòng mà không cần can thiệp thủ công.
Khi một tác vụ thất bại do lỗi dịch vụ mô hình (hết hạn mức, chạm giới hạn tốc độ, khóa API không hợp lệ), hệ thống giờ đây sẽ tự động chuyển sang cấu hình dự phòng tiếp theo và tiếp tục chạy.
Về cơ bản, tính năng này giải quyết vấn đề “thức dậy thấy các tác vụ thất bại vì hạn mức OpenAI đã cạn lúc 3 giờ sáng”. Bạn thiết lập một chuỗi cấu hình, và nếu cấu hình chính gặp sự cố, hệ thống sẽ lần lượt thử các cấu hình dự phòng mà không cần can thiệp thủ công.
96
·
--
Xem bản dịch
Why Claude's output feels cognitively expensive:
Claude structures sentences backward from human speech patterns. It leads with the conclusion, forcing your brain to buffer context it hasn't received yet.
Example breakdown:
"A missing semicolon caused the crash" - subject is the detail you're still parsing. Your working memory has to hold "missing semicolon" while waiting for "crash" to give it meaning.
Human-optimized version: "The crash came from a missing semicolon" - starts with the known entity (crash), adds the new info (semicolon) at the end. Zero cognitive overhead.
Claude's own explanation: "I write from where I ended up. A person talks from where the listener is standing."
The fix: When using LLM output, rewrite sentences to put familiar concepts first, new information last. Saves brain cycles, reduces that melting feeling.
Why Claude's output feels cognitively expensive:
Claude structures sentences backward from human speech patterns. It leads with the conclusion, forcing your brain to buffer context it hasn't received yet.
Example breakdown:
"A missing semicolon caused the crash" - subject is the detail you're still parsing. Your working memory has to hold "missing semicolon" while waiting for "crash" to give it meaning.
Human-optimized version: "The crash came from a missing semicolon" - starts with the known entity (crash), adds the new info (semicolon) at the end. Zero cognitive overhead.
Claude's own explanation: "I write from where I ended up. A person talks from where the listener is standing."
The fix: When using LLM output, rewrite sentences to put familiar concepts first, new information last. Saves brain cycles, reduces that melting feeling.
Claude structures sentences backward from human speech patterns. It leads with the conclusion, forcing your brain to buffer context it hasn't received yet.
Example breakdown:
"A missing semicolon caused the crash" - subject is the detail you're still parsing. Your working memory has to hold "missing semicolon" while waiting for "crash" to give it meaning.
Human-optimized version: "The crash came from a missing semicolon" - starts with the known entity (crash), adds the new info (semicolon) at the end. Zero cognitive overhead.
Claude's own explanation: "I write from where I ended up. A person talks from where the listener is standing."
The fix: When using LLM output, rewrite sentences to put familiar concepts first, new information last. Saves brain cycles, reduces that melting feeling.
72
·
--
Xem bản dịch
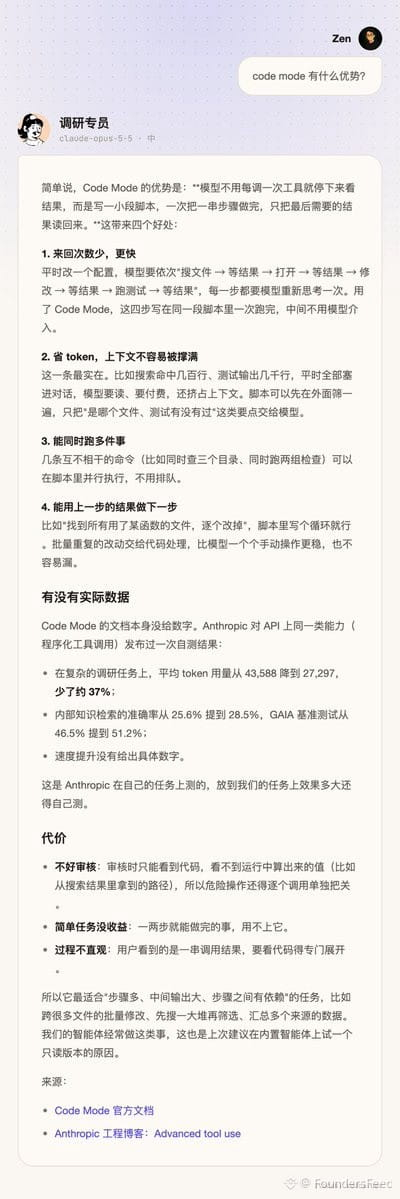
Dug into Claude's new Code Mode.
Turns out this is how tool calling should've been designed from the start. The execution flow feels way more natural — instead of the back-and-forth ping-pong between model and tools, Code Mode lets Claude write actual code that orchestrates tool usage directly.
Think of it like moving from REST API calls to writing a Python script that chains your functions. Way less latency, way more control over execution logic.
If you're building agents or multi-step workflows, this changes the game. No more prompt engineering around tool sequencing — just let the model write the glue code.
Dug into Claude's new Code Mode.
Turns out this is how tool calling should've been designed from the start. The execution flow feels way more natural — instead of the back-and-forth ping-pong between model and tools, Code Mode lets Claude write actual code that orchestrates tool usage directly.
Think of it like moving from REST API calls to writing a Python script that chains your functions. Way less latency, way more control over execution logic.
If you're building agents or multi-step workflows, this changes the game. No more prompt engineering around tool sequencing — just let the model write the glue code.
Turns out this is how tool calling should've been designed from the start. The execution flow feels way more natural — instead of the back-and-forth ping-pong between model and tools, Code Mode lets Claude write actual code that orchestrates tool usage directly.
Think of it like moving from REST API calls to writing a Python script that chains your functions. Way less latency, way more control over execution logic.
If you're building agents or multi-step workflows, this changes the game. No more prompt engineering around tool sequencing — just let the model write the glue code.
65
·
--
Xem bản dịch
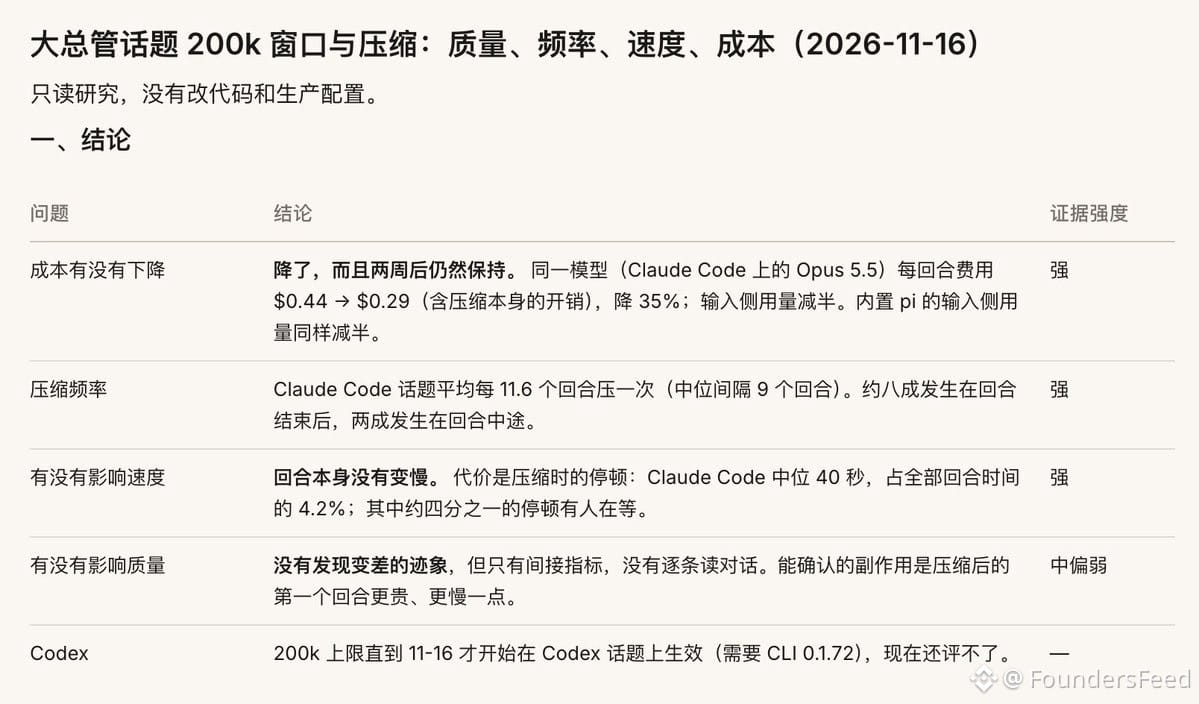
Ran a 2-week experiment limiting auto-compression window to 200k tokens in Todos workspace:
35% cost reduction on input tokens (literally cut in half)
Compression speed massively improved, iteration cycles feel snappier
Critical context preservation stays solid, task quality basically unchanged
Lesson: Don't blindly max out model context windows. Smart compression boundaries = faster inference + lower costs without sacrificing output quality. Context window tuning matters more than people think.
Ran a 2-week experiment limiting auto-compression window to 200k tokens in Todos workspace:
35% cost reduction on input tokens (literally cut in half)
Compression speed massively improved, iteration cycles feel snappier
Critical context preservation stays solid, task quality basically unchanged
Lesson: Don't blindly max out model context windows. Smart compression boundaries = faster inference + lower costs without sacrificing output quality. Context window tuning matters more than people think.
35% cost reduction on input tokens (literally cut in half)
Compression speed massively improved, iteration cycles feel snappier
Critical context preservation stays solid, task quality basically unchanged
Lesson: Don't blindly max out model context windows. Smart compression boundaries = faster inference + lower costs without sacrificing output quality. Context window tuning matters more than people think.
43
·
--
Hiện nay, phần lớn token trên internet đều do AI tạo ra, điều đó có nghĩa là mọi hoạt động thu thập dữ liệu huấn luyện tự động đều bao gồm nội dung tổng hợp. Điều này tạo ra một vòng lặp chưng cất ngoài ý muốn — các mô hình được huấn luyện trên dữ liệu thu thập từ web vốn dĩ đang học từ chính đầu ra của chúng theo thời gian. Đây không phải là chưng cất mô hình có chủ đích, mà là một quá trình tinh chỉnh thụ động được tích hợp sẵn trong quy trình dữ liệu. Kho ngữ liệu huấn luyện ngày càng tự quy chiếu.
Hiện nay, phần lớn token trên internet đều do AI tạo ra, điều đó có nghĩa là mọi hoạt động thu thập dữ liệu huấn luyện tự động đều bao gồm nội dung tổng hợp. Điều này tạo ra một vòng lặp chưng cất ngoài ý muốn — các mô hình được huấn luyện trên dữ liệu thu thập từ web vốn dĩ đang học từ chính đầu ra của chúng theo thời gian. Đây không phải là chưng cất mô hình có chủ đích, mà là một quá trình tinh chỉnh thụ động được tích hợp sẵn trong quy trình dữ liệu. Kho ngữ liệu huấn luyện ngày càng tự quy chiếu.
58
·
--
Todos đã phát hành bản sửa lỗi cho một vấn đề bảo mật nghiêm trọng: người dùng vô tình làm lộ khóa API trong các cuộc trò chuyện. Giải pháp xử lý việc phát hiện và làm sạch khóa ở cấp giao thức, ngăn thông tin xác thực bị lộ dưới dạng văn bản thuần trong nhật ký hoặc lịch sử tin nhắn. Đây là một bước đi sáng suốt đối với mọi công cụ AI dựa trên trò chuyện có xử lý mã thông báo xác thực nhạy cảm.
Todos đã phát hành bản sửa lỗi cho một vấn đề bảo mật nghiêm trọng: người dùng vô tình làm lộ khóa API trong các cuộc trò chuyện. Giải pháp xử lý việc phát hiện và làm sạch khóa ở cấp giao thức, ngăn thông tin xác thực bị lộ dưới dạng văn bản thuần trong nhật ký hoặc lịch sử tin nhắn. Đây là một bước đi sáng suốt đối với mọi công cụ AI dựa trên trò chuyện có xử lý mã thông báo xác thực nhạy cảm.
63
·
--
Khả năng tự nhận thức của Jensen đã thành huyền thoại. GeForce FX 5800 (NV30) là một thảm họa nhiệt—thậm chí còn bị gọi là “Dustbuster” vì khi chạy hết tải, nó kêu như máy hút bụi. Bộ tản nhiệt tham chiếu dùng quạt thổi ly tâm, phát ra tiếng ồn hơn 70 dB khi chịu tải nặng, khiến nó trở thành một trong những GPU dành cho người dùng phổ thông ồn nhất từng được bán ra.
Điều đáng ngạc nhiên là $NVDA không cố tìm cách biện minh. Họ đón nhận luôn meme đó, thậm chí còn đùa nội bộ rằng nó nghe như xe máy. Trong khi đó, đối thủ cạnh tranh (R300 của ATI) vừa êm hơn VỪA nhanh hơn, khiến tình hình càng thêm thảm hại.
Đó là năm 2003—trước khi buồng hơi hiện đại hay tản nhiệt nước AIO trở thành tiêu chuẩn. Voodoo (trước khi được HP mua lại) đã thử nghiệm hệ thống tản nhiệt nước tuần hoàn kín cho PC, một công nghệ tiên tiến vào thời điểm đó. FX 5800 gần như buộc cả ngành phải suy nghĩ lại về thiết kế tản nhiệt cho các chip có TDP cao.
Bài học rút ra: ngay cả khi bạn tung ra một sản phẩm có khuyết điểm, công khai thừa nhận nó vẫn giúp bạn được tôn trọng hơn là để bộ phận PR lo chữa cháy. Sự sẵn lòng bật cười trước những thất bại kỹ thuật của Jensen là một phần lý do khiến văn hóa của $NVDA đủ linh hoạt để thống trị lĩnh vực điện toán AI 20 năm sau.
Khả năng tự nhận thức của Jensen đã thành huyền thoại. GeForce FX 5800 (NV30) là một thảm họa nhiệt—thậm chí còn bị gọi là “Dustbuster” vì khi chạy hết tải, nó kêu như máy hút bụi. Bộ tản nhiệt tham chiếu dùng quạt thổi ly tâm, phát ra tiếng ồn hơn 70 dB khi chịu tải nặng, khiến nó trở thành một trong những GPU dành cho người dùng phổ thông ồn nhất từng được bán ra.
Điều đáng ngạc nhiên là $NVDA không cố tìm cách biện minh. Họ đón nhận luôn meme đó, thậm chí còn đùa nội bộ rằng nó nghe như xe máy. Trong khi đó, đối thủ cạnh tranh (R300 của ATI) vừa êm hơn VỪA nhanh hơn, khiến tình hình càng thêm thảm hại.
Đó là năm 2003—trước khi buồng hơi hiện đại hay tản nhiệt nước AIO trở thành tiêu chuẩn. Voodoo (trước khi được HP mua lại) đã thử nghiệm hệ thống tản nhiệt nước tuần hoàn kín cho PC, một công nghệ tiên tiến vào thời điểm đó. FX 5800 gần như buộc cả ngành phải suy nghĩ lại về thiết kế tản nhiệt cho các chip có TDP cao.
Bài học rút ra: ngay cả khi bạn tung ra một sản phẩm có khuyết điểm, công khai thừa nhận nó vẫn giúp bạn được tôn trọng hơn là để bộ phận PR lo chữa cháy. Sự sẵn lòng bật cười trước những thất bại kỹ thuật của Jensen là một phần lý do khiến văn hóa của $NVDA đủ linh hoạt để thống trị lĩnh vực điện toán AI 20 năm sau.
Điều đáng ngạc nhiên là $NVDA không cố tìm cách biện minh. Họ đón nhận luôn meme đó, thậm chí còn đùa nội bộ rằng nó nghe như xe máy. Trong khi đó, đối thủ cạnh tranh (R300 của ATI) vừa êm hơn VỪA nhanh hơn, khiến tình hình càng thêm thảm hại.
Đó là năm 2003—trước khi buồng hơi hiện đại hay tản nhiệt nước AIO trở thành tiêu chuẩn. Voodoo (trước khi được HP mua lại) đã thử nghiệm hệ thống tản nhiệt nước tuần hoàn kín cho PC, một công nghệ tiên tiến vào thời điểm đó. FX 5800 gần như buộc cả ngành phải suy nghĩ lại về thiết kế tản nhiệt cho các chip có TDP cao.
Bài học rút ra: ngay cả khi bạn tung ra một sản phẩm có khuyết điểm, công khai thừa nhận nó vẫn giúp bạn được tôn trọng hơn là để bộ phận PR lo chữa cháy. Sự sẵn lòng bật cười trước những thất bại kỹ thuật của Jensen là một phần lý do khiến văn hóa của $NVDA đủ linh hoạt để thống trị lĩnh vực điện toán AI 20 năm sau.
57
Đăng nhập để khám phá thêm nội dung
Tham gia cùng người dùng tiền mã hóa toàn cầu trên Binance Square
⚡️ Nhận thông tin mới nhất và hữu ích về tiền mã hóa.
💬 Được tin cậy bởi sàn giao dịch tiền mã hóa lớn nhất thế giới.
👍 Khám phá những thông tin chuyên sâu thực tế từ những nhà sáng tạo đã xác minh.
Email / Số điện thoại
Chủ đề thịnh hành
TinFed
433,721 lượt xem
1,367 đang thảo luận
Biên bản cuộc họp Fed: Một số thành viên ủng hộ tăng lãi suất cho biết họ có thể đã chấp nhận giữ nguyên lãi suất nếu thị trường hiểu rõ rằng việc thắt chặt thêm là có khả năng xảy ra.
Fed cho rằng việc tăng lãi suất nhiều hơn 25 điểm cơ bản vào tháng 12 có thể là cần thiết.
Quả này chứng khoán Vàng $XAU bạc $XAG cụ $BTC còn thủng thế vùng hỗ trợ sẽ là bao nhiêu đây. Thôi cứ nhàn nhàn bắt đáy từ từ thôi nào kk. đòn bảy mà bắt vol to cẩn thận đứt tay kk
#TinFed #TheoDõiFOMC #CanNvidia’sDataCenterGrowthContinue? #fed
Mr_Startup
·3 lượt thích
·1.9k lượt xem
TheoDõiFOMC
366,921 lượt xem
1,588 đang thảo luận
NvidiaLoses$2.7TrillionInMonthAndAHalf
16,477 lượt xem
113 đang thảo luận