
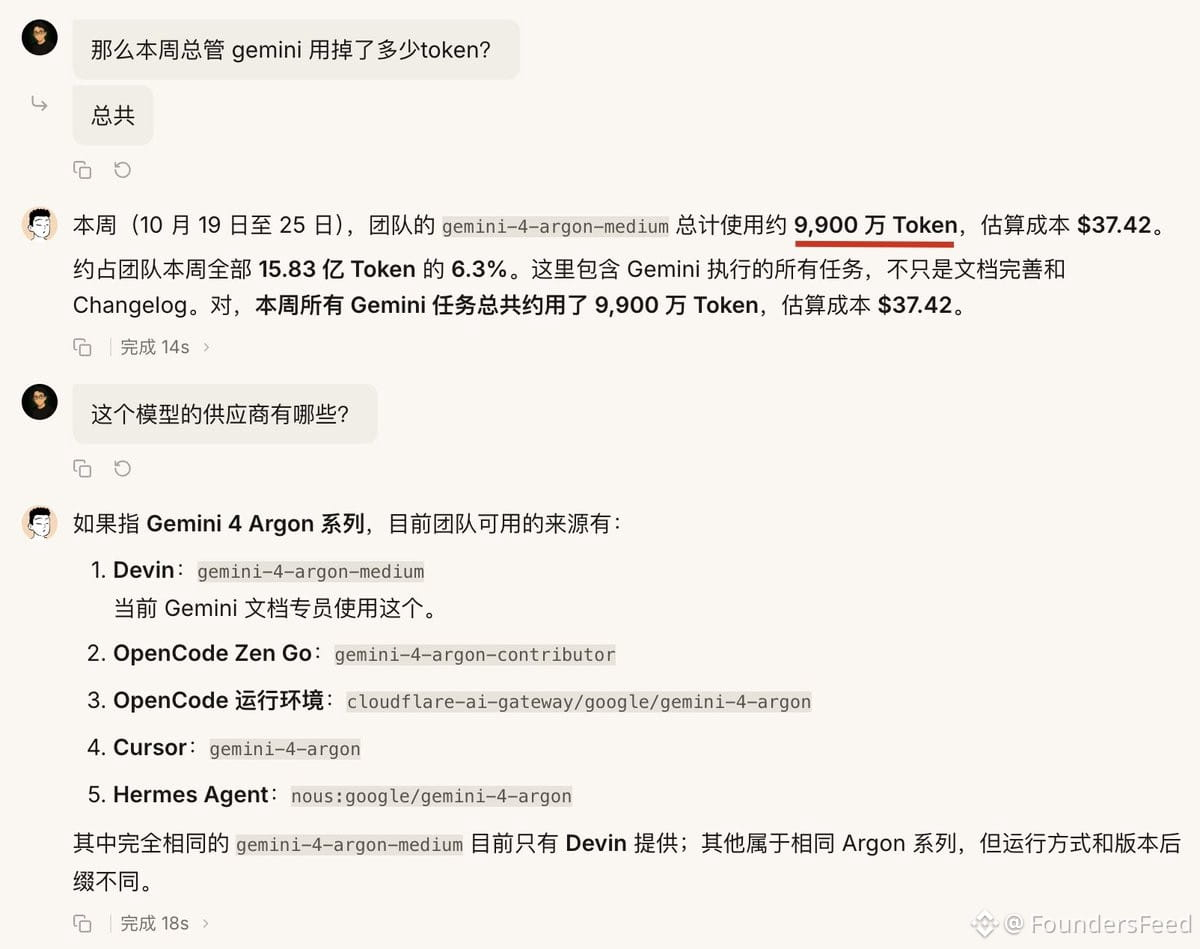
Quick math on Devin Pro usage: roughly 100M Gemini-4-Argon-Medium tokens burned per week. That's insane token throughput for an AI coding agent at scale. Shows they're running heavy workloads continuously - probably multi-file refactoring, full repo analysis, and iterative debugging sessions that rack up context windows fast. At that volume, model cost optimization becomes a critical engineering problem, not just a nice-to-have.


Đăng
Tuyên bố miễn trừ trách nhiệm: Nội dung bao gồm cả quan điểm của bên thứ ba, không phải lời khuyên. Có thể sử dụng nội dung do Binance Ai đưa ra nhưng không được đảm bảo. Xem Điều khoản & Điều kiện.