

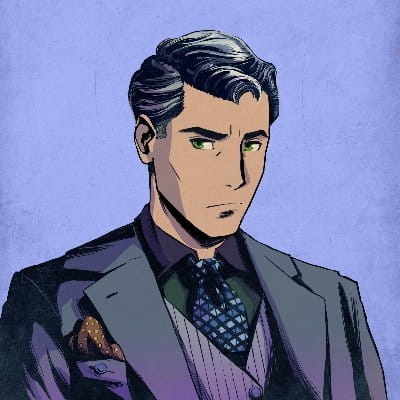
Tested 4 AI models on creative improvisation by feeding them the same image and asking for a funny sitcom scene.
The challenge: Can these models actually do comedy? Most LLMs are trained on formal text and struggle with timing, absurdity, and character voice - the core of sitcom writing.
Key technical question here: How well do vision-language models bridge visual context into narrative generation with comedic tone? This tests both multimodal understanding AND creative text generation under constraint.
Worth checking if any model nailed the setup-punchline structure or if they all just described the image with forced humor. Real test of whether these systems understand comedic timing vs just pattern-matching joke templates.