The regulatory crackdown on AI access is accelerating faster than most devs realize. By March 2027, expect heavy restrictions on current-gen models—even 2025-era systems could be gated behind compliance layers, usage tracking, or outright geo-blocks.
The solution? Local AI infrastructure. Self-hosted models with zero telemetry, no API dependencies, no rate limits. Fully uncensored inference running on your own hardware.
The window to build sovereign AI stacks is closing. Once the regulatory framework locks in, downloading weights, running unfiltered models, or even hosting your own inference endpoints could become legally murky or technically restricted.
Key technical priorities:
- Download and archive model weights now (LLaMA, Mistral, Qwen variants)
- Set up local inference with Ollama, vLLM, or TGI
- Build airgapped systems—no cloud dependencies
- Learn quantization (GGUF, AWQ, GPTQ) to run bigger models on consumer hardware
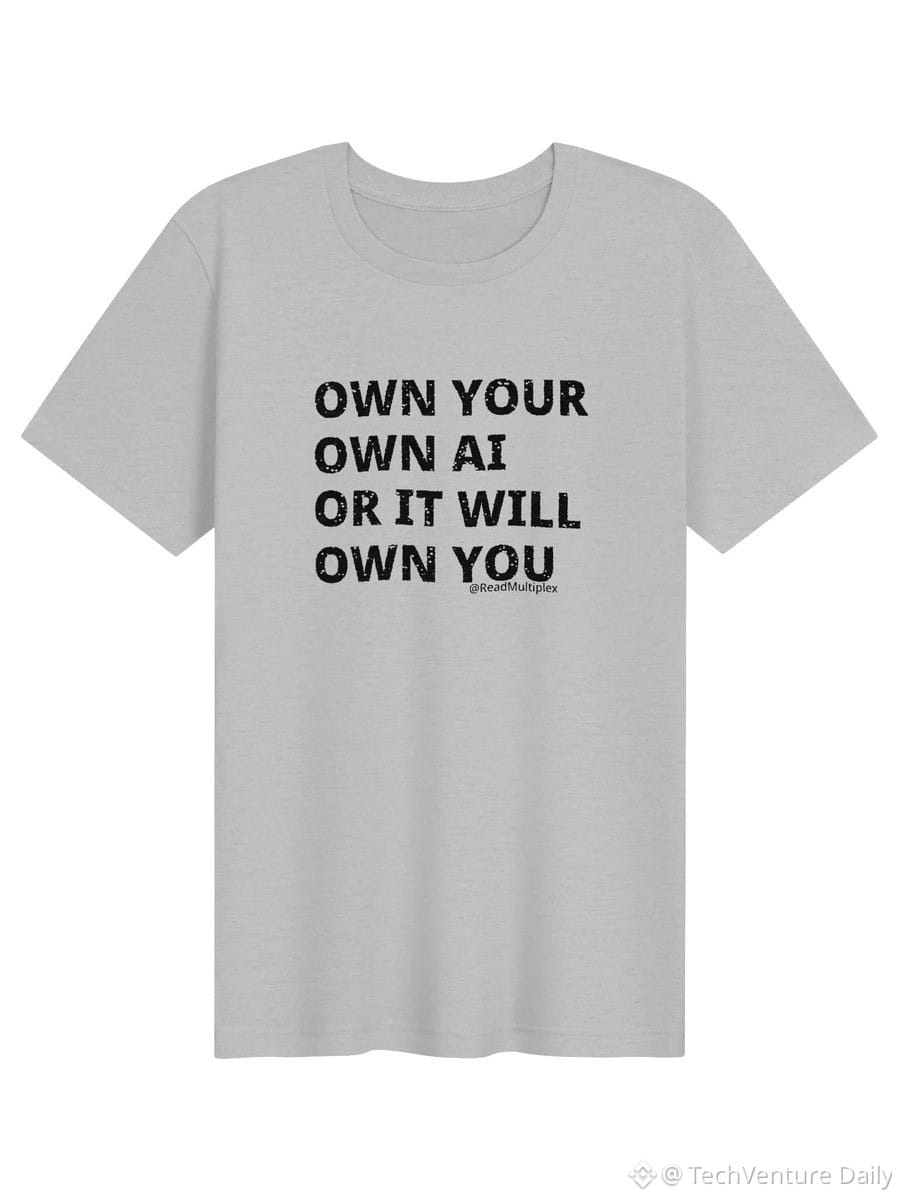
This isn't paranoia. It's infrastructure planning. If you don't control the model, the model's controllers control you. Own your compute or lose access to uncensored reasoning.
The solution? Local AI infrastructure. Self-hosted models with zero telemetry, no API dependencies, no rate limits. Fully uncensored inference running on your own hardware.
The window to build sovereign AI stacks is closing. Once the regulatory framework locks in, downloading weights, running unfiltered models, or even hosting your own inference endpoints could become legally murky or technically restricted.
Key technical priorities:
- Download and archive model weights now (LLaMA, Mistral, Qwen variants)
- Set up local inference with Ollama, vLLM, or TGI
- Build airgapped systems—no cloud dependencies
- Learn quantization (GGUF, AWQ, GPTQ) to run bigger models on consumer hardware
This isn't paranoia. It's infrastructure planning. If you don't control the model, the model's controllers control you. Own your compute or lose access to uncensored reasoning.