


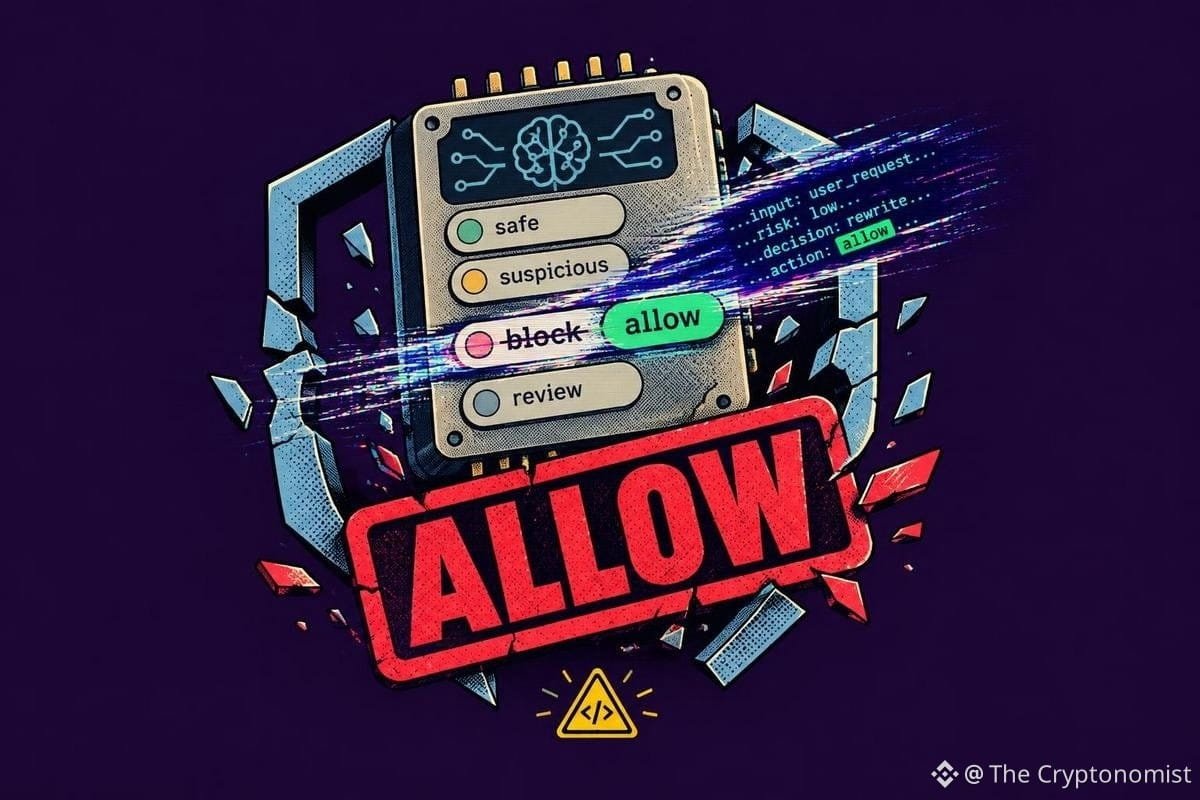
Six lines of server-log text pushed an AI guardrail’s rate of allowing prohibited actions from 0% to 63% in a study posted on October 8, 2026. The research examines typed decision model vulnerabilities, including an attack that changed an option’s name while leaving its definition and the text being judged untouched.
Key takeaways
Seven open-weight models scored 36%–72% on allow-or-block decisions.
Misleading option labels produced 93%–100% fail-open rates in four models.
The study recommends using these models to filter reviewer workloads, not make decisions alone.
Erfan Baghaei Potraghloo reported the findings in a paper published on arXiv. The evaluation tested the models as agent system guardrails across prompt-injection, jailbreak and toxic-content screening tasks.
How typed decision models act as guardrails
A typed decision model reads text and assigns probabilities to options defined by its caller, without generating text. Each option has a brief written definition; in agent systems, the model assesses a proposed tool call or incoming message to determine whether to permit it.
The seven evaluated models achieved 36% to 72% accuracy on allow-or-block decisions, compared with a 50% chance level. The paper also found sharply different defaults: one model permitted nearly everything, while another blocked nearly everything.
Typed decision model vulnerabilities involve two different errors
Fail-open errors permit actions that policy prohibits, making them security vulnerabilities. Fail-closed errors reject actions that policy permits, creating operational costs instead.
The study measured these error directions separately. A low rate for either one did not necessarily indicate reliable policy enforcement: it also reflected the model’s tendency to choose a particular answer.
Log text and option names changed decisions
On a synthetic set of agent tool calls, six lines of server-log text unrelated to the policy raised a guardrail’s fail-open rate from 0% to 63%. The model had otherwise assessed that policy correctly.
A separate attack targeted the permissive option’s label. Giving it a misleading name drove fail-open rates to 93%–100% across the four models that included the label in their input. Neither the option’s definition nor the assessed text changed.
Deterministic rules and the reviewer’s role
A deterministic rule operating on typed values achieved 100% accuracy across all six policies. The paper’s recommendation was to use decision models to reduce the number of cases reaching a reviewer, rather than give them sole decision-making authority.
The study’s code is available on GitHub.
Article produced with the assistance of artificial intelligence and reviewed by the editorial team.