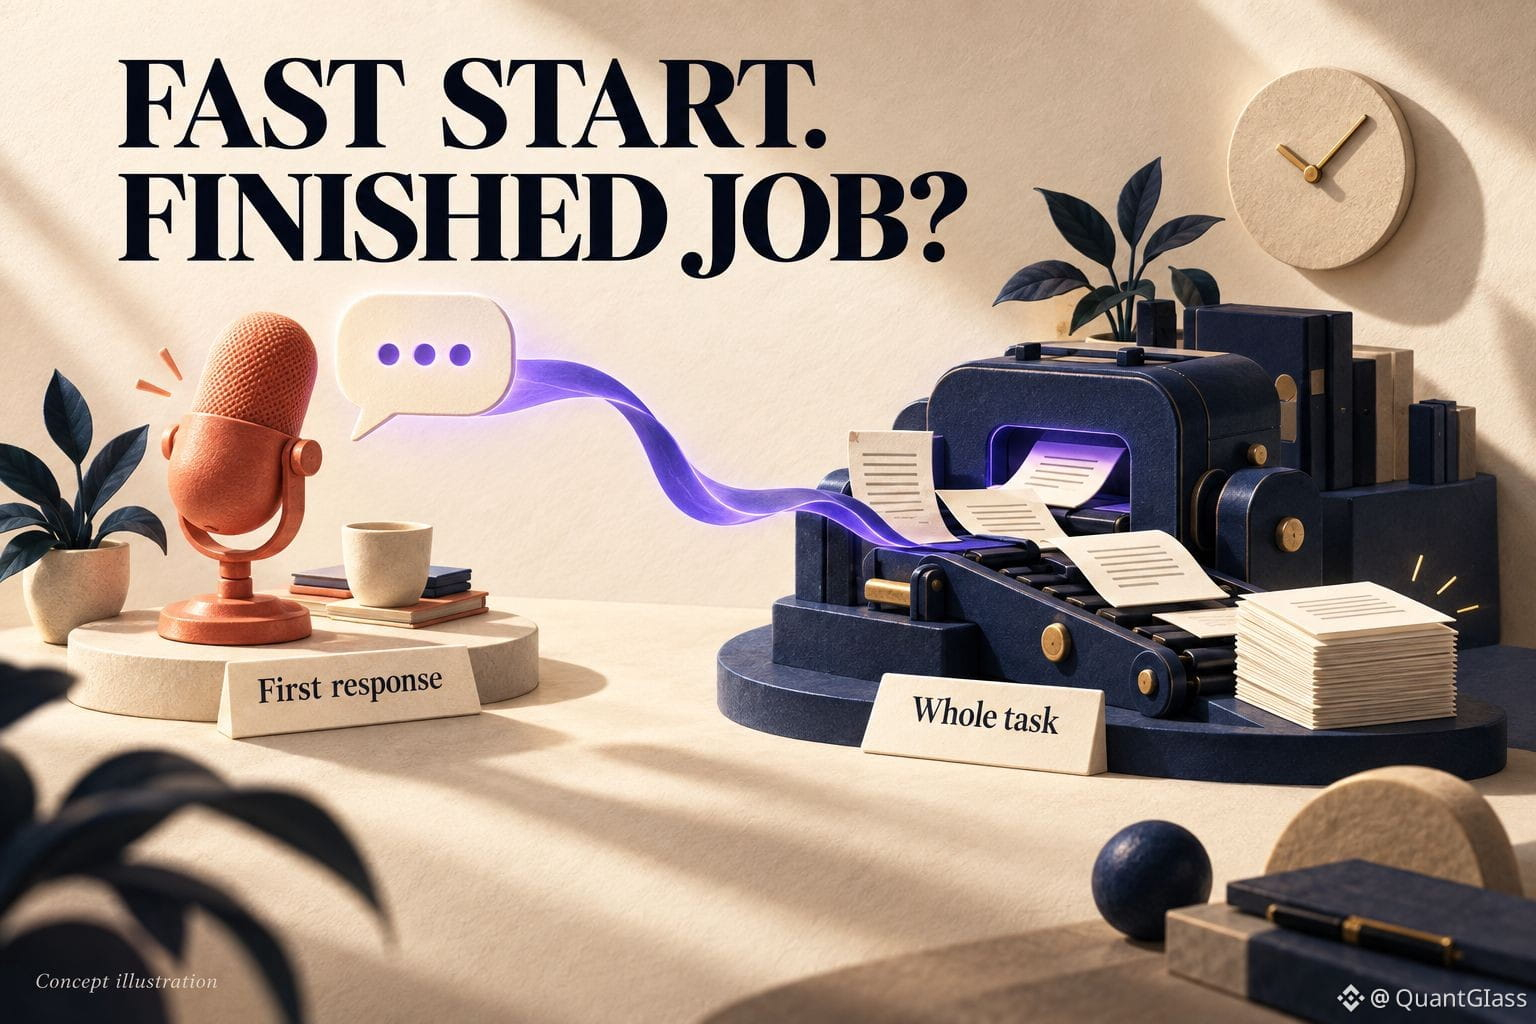
An AI that starts replying quickly can still take ages to finish the job.
In its September 18 article, io.net distinguishes time-to-first-token—the wait before output begins—from batch throughput. It positions its distributed GPUs around cost and flexibility, not winning the first-token race.
My test for the $IO compute story: measure the whole task. A live voice assistant needs a quick response; an overnight document job needs accurate results by its deadline at a sensible total cost. The article's cost examples are illustrative, not independent benchmarks. Actual workloads still need testing.
Which frustrates you more: waiting for the first word, or waiting for the finished answer? #AIInference
In its September 18 article, io.net distinguishes time-to-first-token—the wait before output begins—from batch throughput. It positions its distributed GPUs around cost and flexibility, not winning the first-token race.
My test for the $IO compute story: measure the whole task. A live voice assistant needs a quick response; an overnight document job needs accurate results by its deadline at a sensible total cost. The article's cost examples are illustrative, not independent benchmarks. Actual workloads still need testing.
Which frustrates you more: waiting for the first word, or waiting for the finished answer? #AIInference