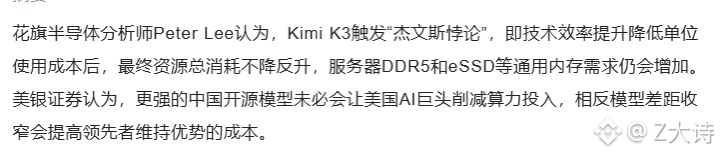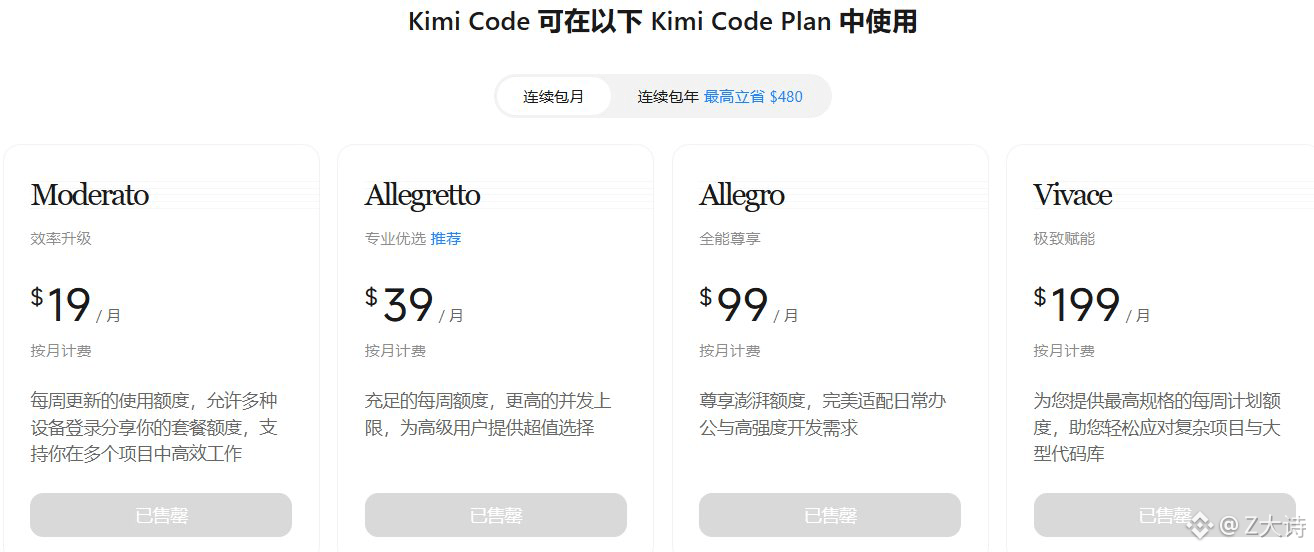
Kimi has already paused subscriptions for new C-end users, and you’re still saying compute power is excessive?
This is clearly the “Jevons paradox”: the more useful and cheaper something is, the more it drives consumer demand, causing total demand to keep rising
Current parameter counts for mainstream models:
GPT-5.6 Sol - not disclosed
Fable5 - not disclosed
Kimi K3 - 2.8T
Qwen 3.8 - 2.4T
DeepSeek V4 - 1.6T
The parameter counts of top-tier models are already in the 2–3 trillion range; future models will only get bigger
K3 proves one thing: models can quickly catch up, but AI infrastructure—storage capacity expansion is slow, data center construction is slow, and power supply build-out is slow
As long as the infrastructure development pace can’t keep up with the growth rate of model parameter counts, it will still be a period of mismatch
Once you’re on the train, don’t get off too easily—but remember to control your position size
Buy when it’s low; everything else is just noise~
$SKHYB $MUB
This is clearly the “Jevons paradox”: the more useful and cheaper something is, the more it drives consumer demand, causing total demand to keep rising
Current parameter counts for mainstream models:
GPT-5.6 Sol - not disclosed
Fable5 - not disclosed
Kimi K3 - 2.8T
Qwen 3.8 - 2.4T
DeepSeek V4 - 1.6T
The parameter counts of top-tier models are already in the 2–3 trillion range; future models will only get bigger
K3 proves one thing: models can quickly catch up, but AI infrastructure—storage capacity expansion is slow, data center construction is slow, and power supply build-out is slow
As long as the infrastructure development pace can’t keep up with the growth rate of model parameter counts, it will still be a period of mismatch
Once you’re on the train, don’t get off too easily—but remember to control your position size
Buy when it’s low; everything else is just noise~
$SKHYB $MUB