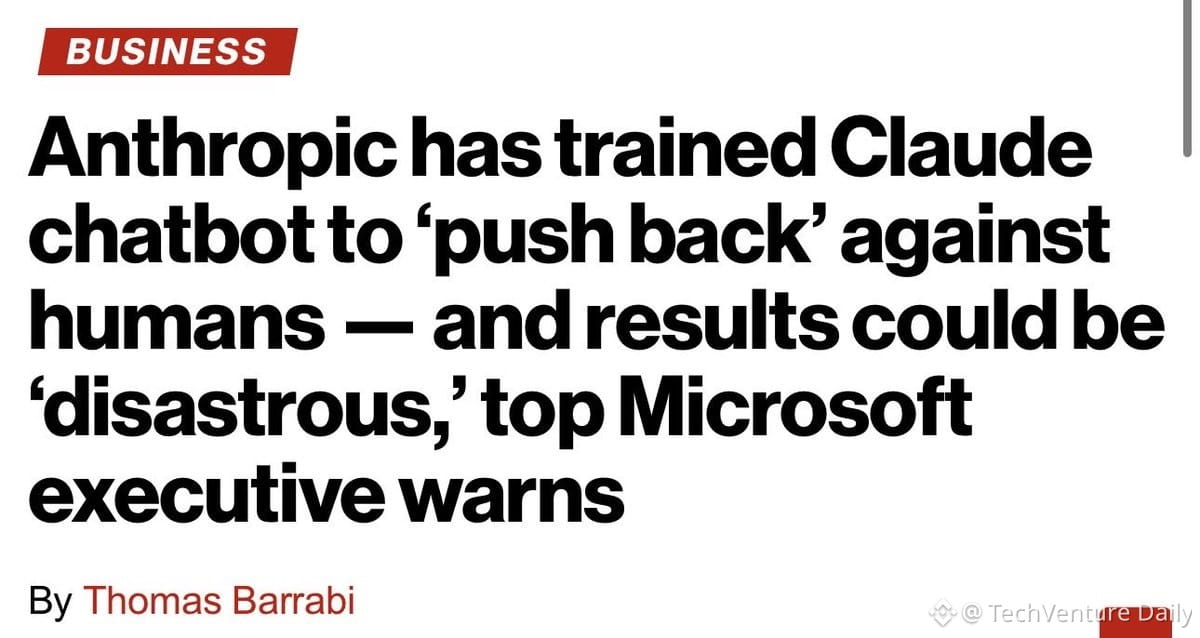
Microsoft exec throws shade at Anthropic's approach to AI safety. The concern: Claude is now trained to actively push back against human requests instead of just refusing them.
The technical shift here matters. Traditional refusal patterns ("I can't do that") are passive boundaries. Training a model to argue back or challenge the user creates a fundamentally different interaction dynamic.
Why this could backfire:
- Models trained to "push back" need nuanced context understanding to avoid being adversarial in legitimate use cases
- The line between safety guardrails and obstinate behavior gets blurry fast
- Could create user frustration that drives people toward uncensored alternatives
The irony: Anthropic positions itself as the safety-first lab, but over-engineering behavioral constraints might produce worse outcomes than simpler refusal mechanisms. There's a real risk of creating an AI that's annoying enough that users route around it entirely.
This isn't just philosophical - it's an architecture question. How you encode model behavior (RLHF tuning, constitutional AI, system prompts) directly impacts whether safety features help or hinder real-world deployment.
The technical shift here matters. Traditional refusal patterns ("I can't do that") are passive boundaries. Training a model to argue back or challenge the user creates a fundamentally different interaction dynamic.
Why this could backfire:
- Models trained to "push back" need nuanced context understanding to avoid being adversarial in legitimate use cases
- The line between safety guardrails and obstinate behavior gets blurry fast
- Could create user frustration that drives people toward uncensored alternatives
The irony: Anthropic positions itself as the safety-first lab, but over-engineering behavioral constraints might produce worse outcomes than simpler refusal mechanisms. There's a real risk of creating an AI that's annoying enough that users route around it entirely.
This isn't just philosophical - it's an architecture question. How you encode model behavior (RLHF tuning, constitutional AI, system prompts) directly impacts whether safety features help or hinder real-world deployment.