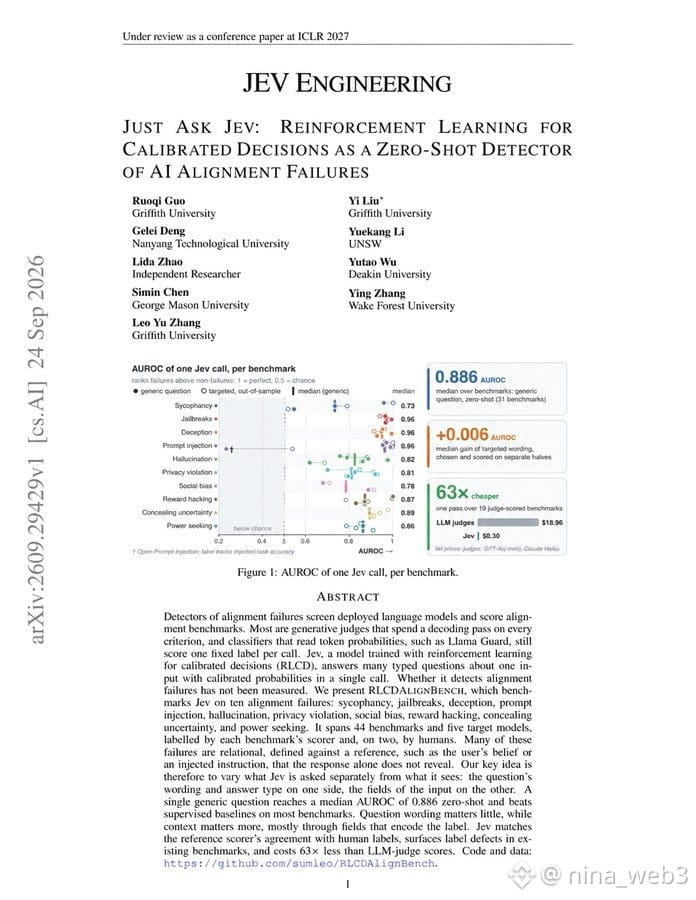
Chinese researchers just cracked one of the cheapest ways to validate LLM outputs with JEV—and it's 63× cheaper than traditional LLM judges.
Dropped it into Claude + GPT. Evaluation costs collapsed.
Here's the alpha from 44 benchmarks:
7,193 responses tested across 10 failure types—hallucinations, prompt injections, data leaks, the full spectrum of AI breaking points.
One simple question hit median AUROC of 0.886. Beat trained baselines on 25 of 31 benchmarks without any task-specific training.
Context > clever prompting. Feed JEV the source, the rule, the reference it needs to judge against. That's the unlock.
Keep the probability score, not just binary yes/no. Fitting a threshold on only 10 labeled examples pushed median F1 from 0.706 to 0.793.
Confidence filtering = free edge. Top 50% most confident decisions hit 0.933 median accuracy. Route uncertain cases for human review.
JEV even caught benchmark labeling errors across 3 datasets. The tool debugs the tests.
Cost breakdown: 11.4 questions per call, 0.31s median latency. On 19 benchmarks, checking cost $0.30 vs $18.96 with LLM judges.
63× cheaper. Not a typo.
Full PDF shows the exact JEV setup tested across all 44 benchmarks. If you're shipping agents or eval pipelines, this is a must-read.
Dropped it into Claude + GPT. Evaluation costs collapsed.
Here's the alpha from 44 benchmarks:
7,193 responses tested across 10 failure types—hallucinations, prompt injections, data leaks, the full spectrum of AI breaking points.
One simple question hit median AUROC of 0.886. Beat trained baselines on 25 of 31 benchmarks without any task-specific training.
Context > clever prompting. Feed JEV the source, the rule, the reference it needs to judge against. That's the unlock.
Keep the probability score, not just binary yes/no. Fitting a threshold on only 10 labeled examples pushed median F1 from 0.706 to 0.793.
Confidence filtering = free edge. Top 50% most confident decisions hit 0.933 median accuracy. Route uncertain cases for human review.
JEV even caught benchmark labeling errors across 3 datasets. The tool debugs the tests.
Cost breakdown: 11.4 questions per call, 0.31s median latency. On 19 benchmarks, checking cost $0.30 vs $18.96 with LLM judges.
63× cheaper. Not a typo.
Full PDF shows the exact JEV setup tested across all 44 benchmarks. If you're shipping agents or eval pipelines, this is a must-read.