

#openledger
openledger
Просмотров: 17.3M
202,843 обсуждают
Популярные
Новые
·
--
Рост
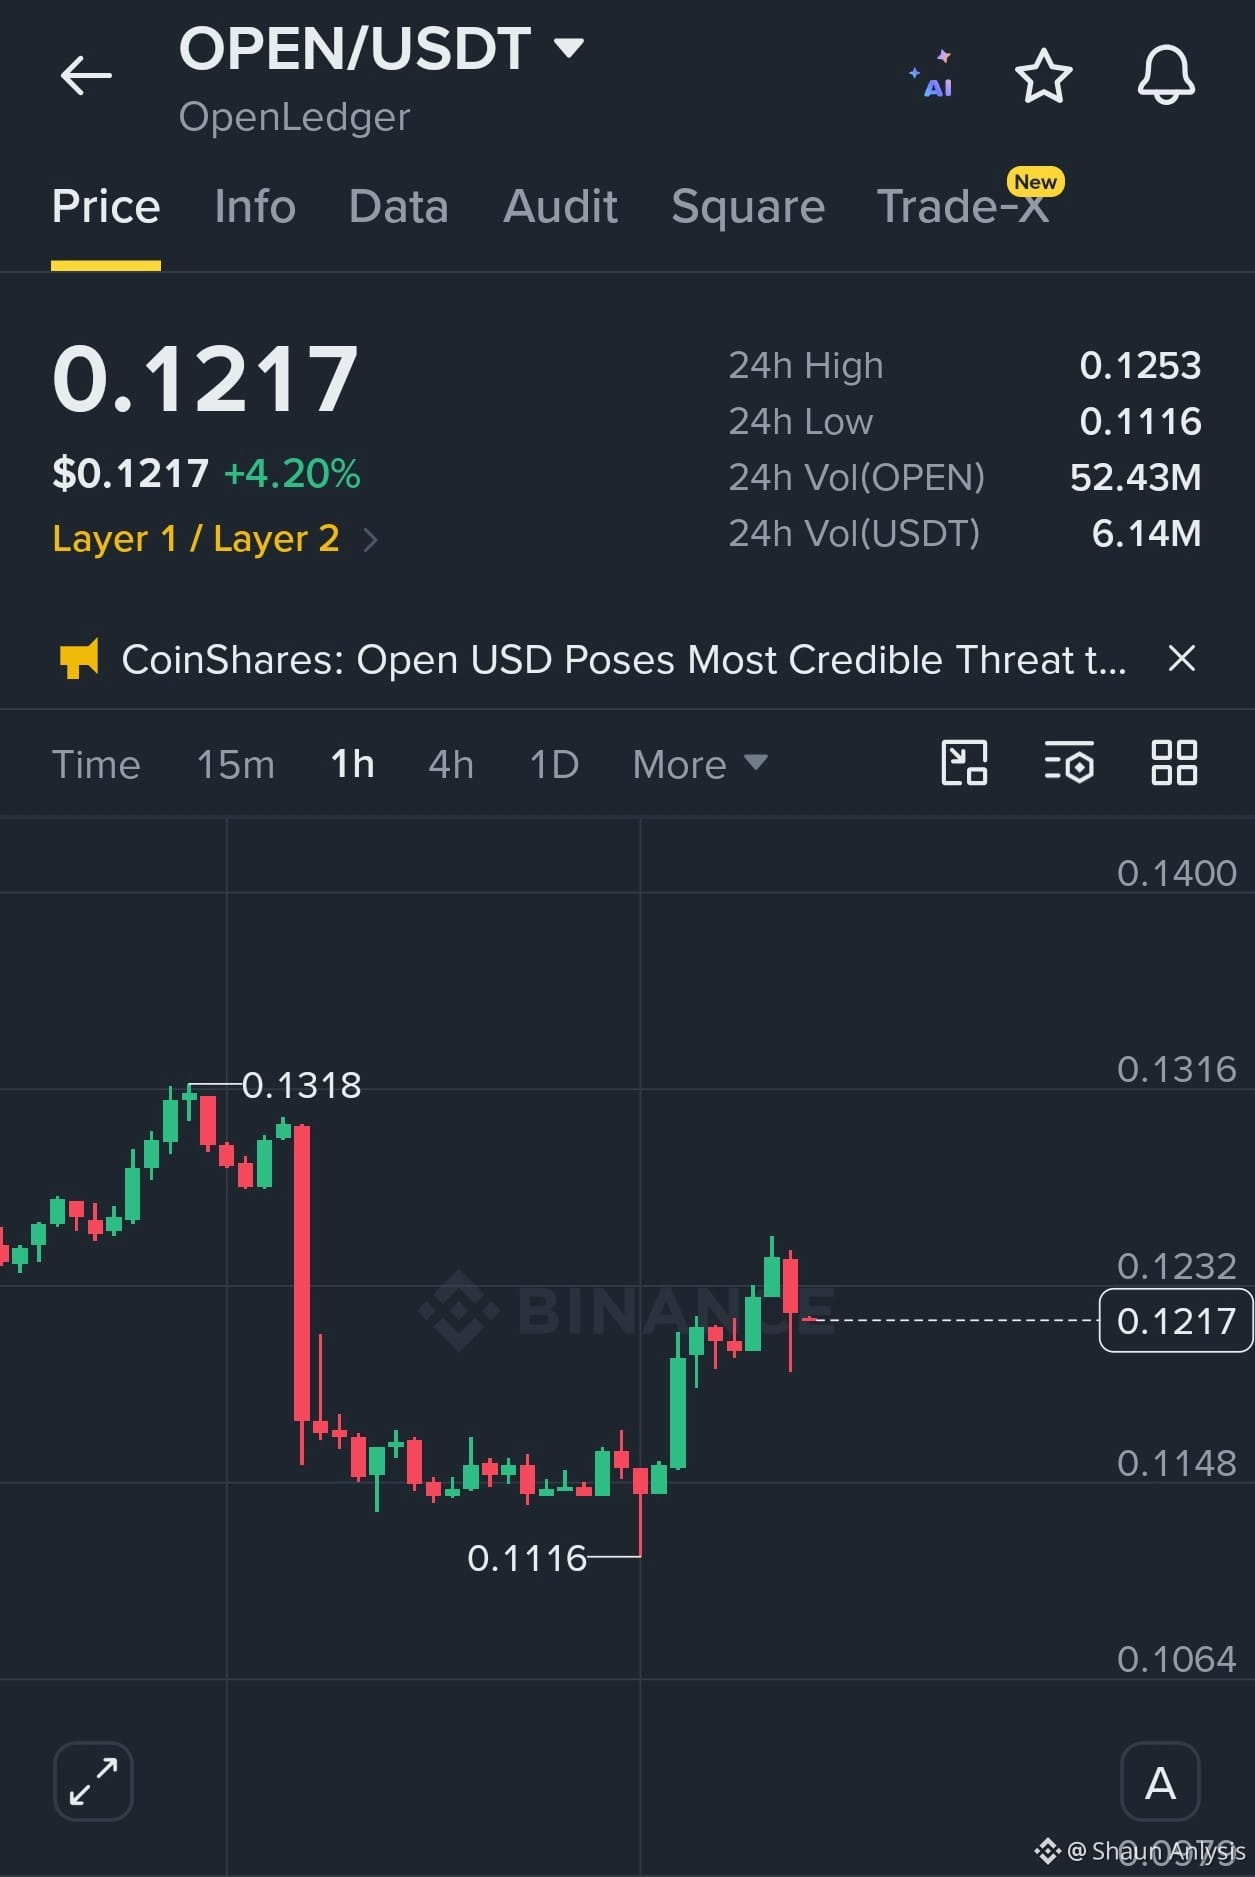
#OpenLedger just printed a textbook V-shaped recovery—don't miss the next leg up.
After a sharp flush to 0.1116, $OPEN has bounced hard, reclaiming the 0.12 handle and currently sitting at 0.1217 (+4.20% on the day). The 1H chart shows a clear shift in momentum as buyers defend the lows and push back toward the 24H high of 0.1253.
Bullish
Entry:0.1180 – 0.1220
SL:0.1100
TP1:0.1318
{future}(OPENUSDT)
#OpenLedger just printed a textbook V-shaped recovery—don't miss the next leg up.
After a sharp flush to 0.1116, $OPEN has bounced hard, reclaiming the 0.12 handle and currently sitting at 0.1217 (+4.20% on the day). The 1H chart shows a clear shift in momentum as buyers defend the lows and push back toward the 24H high of 0.1253.
Bullish
Entry:0.1180 – 0.1220
SL:0.1100
TP1:0.1318
1
96
·
--
Рост
Частичная правда
*OPEN: A Quiet AI Opportunity Near The Bottom*
While many focus on popular AI coins, OpenLedger (OPEN) is trading near its lowest price ever.
From $1.84 to $0.11, a large correction of 94 percent. Is this a bottom?
Here is what makes OpenLedger interesting:
OpenLedger is building infrastructure for AI, where data, models, and AI agents receive payments automatically. Think of AI agents paying for verified data on-chain. This is called agentic payments, and OpenLedger aims to lead this sector.
Market cap is around $43M while volume is $31M. That is over 71 percent turnover, showing strong interest and active accumulation.
Token unlocks are happening. About 612k tokens daily around October 8th. Small unlocks create short-term pressure, but also long-term opportunity.
It is listed on major exchanges like Upbit, Bithumb, and Binance, with strong liquidity.
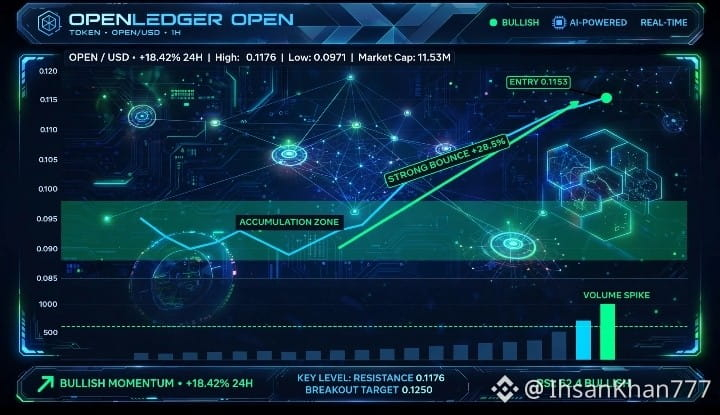
I bought OPEN at $0.1153 near the low range. This is not financial advice, but early infrastructure often looks quiet before growth.
#OpenLedger
#OpenAI
#BestTimeToBuy
#Market_Update
#BullRunTips
$OPEN
$BTC
$BNB
@XG297174
@dengshen
@eggtartcake_grape
@haoge666
@Square-Creator-f92ceb7e7882c
@Square-Creator-d4cc116ea2fe
@SGD852568
@Square-Creator-f0c9a305b41a7
@z12123444
@Square-Creator-9bd28167d172
@NUTS_btc
@heyi
@CZ
@Openledger
@Biswap_Dex
@MagVerse
@EASY7777
@KZG6886
@Z0628
@JavierDot
@oanicai
*OPEN: A Quiet AI Opportunity Near The Bottom*
While many focus on popular AI coins, OpenLedger (OPEN) is trading near its lowest price ever.
From $1.84 to $0.11, a large correction of 94 percent. Is this a bottom?
Here is what makes OpenLedger interesting:
OpenLedger is building infrastructure for AI, where data, models, and AI agents receive payments automatically. Think of AI agents paying for verified data on-chain. This is called agentic payments, and OpenLedger aims to lead this sector.
Market cap is around $43M while volume is $31M. That is over 71 percent turnover, showing strong interest and active accumulation.
Token unlocks are happening. About 612k tokens daily around October 8th. Small unlocks create short-term pressure, but also long-term opportunity.
It is listed on major exchanges like Upbit, Bithumb, and Binance, with strong liquidity.
I bought OPEN at $0.1153 near the low range. This is not financial advice, but early infrastructure often looks quiet before growth.
#OpenLedger
#OpenAI
#BestTimeToBuy
#Market_Update
#BullRunTips
$OPEN
$BTC
$BNB
@K线人生飞哥
@比特币预言家
@Eggtartcake
@交易员张张子
@华尔街倩倩子
@猩火Bro
@Flash闪光灯
@乐天eth
@加密大格格
@klxmBobo
@Nuts坚果
@Yi He
@CZ
@OpenLedger
@Qordman crypto
@MagVerse
@EASY喊單哥
@KZG Crypto 口罩哥
@Whale韭阴针鲸0628
@_WHALE_
@Oanic AI
4
865
·
--
📉 $OPEN
— OpenLedger Cooling Off
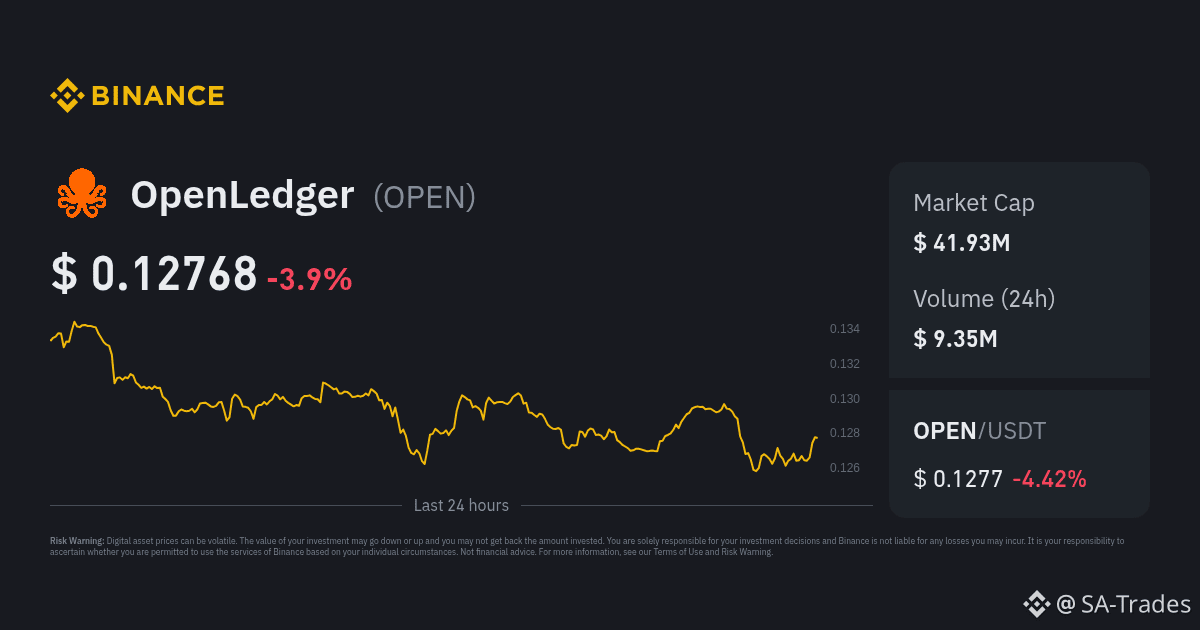
OpenLedger (OPEN) down -3.9% today, now trading at $0.1277.
📊 Market Cap: $41.93M
📊 24h Volume: $9.35M
Choppy price action over the last 24h — sellers stepping in after failing to hold higher levels.
Accumulation zone or further downside? 👀
Trade $OPEN here
{future}(OPENUSDT)
#OPEN #OpenLedger #BinanceSquare #crypto
📉 $OPEN
— OpenLedger Cooling Off
OpenLedger (OPEN) down -3.9% today, now trading at $0.1277.
📊 Market Cap: $41.93M
📊 24h Volume: $9.35M
Choppy price action over the last 24h — sellers stepping in after failing to hold higher levels.
Accumulation zone or further downside? 👀
Trade $OPEN here
#OPEN #OpenLedger #BinanceSquare #crypto
2
4
265
·
--
يا شباب $OPEN تحت الضغط… هل يظهر ارتداد؟
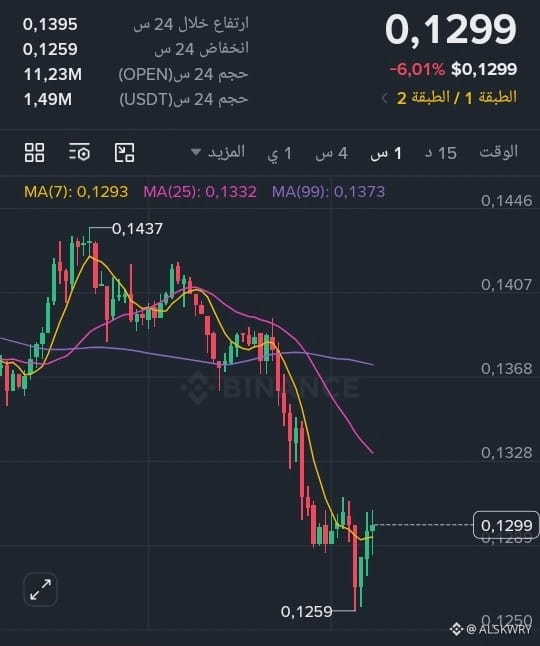
عملة OpenLedger (OPEN) تتحرك حاليًا تحت ضغط بيعي، والسعر حول $0.1299 بعد هبوط يقارب 6% خلال 24 ساعة.
📉 أهم المستويات:
🟢 دعم: $0.1260
🔴 مقاومة: $0.1328 – $0.1330
🔴 مقاومة أقوى: $0.1368 – $0.1375
إذا حافظ السعر على $0.126 وبدأ بتكوين قيعان أعلى، فقد نشهد محاولة ارتداد. أما كسرها بوضوح فقد يفتح المجال لمستويات أدنى.
👀 OPEN الآن تستحق المراقبة، وليس الشراء لمجرد أن السعر انخفض.
هل تتوقعون ارتداد OPEN أم استمرار الهبوط؟
⚠️ ليس توصية مالية، مجرد تحليل ومشاركة للنقاش.
#OpenLedger #cryptouniverseofficial #BinanceSquare #trading
1
1
230

·
--
现在这币圈,只要是个项目,不往自己身上贴个“AI”的标签,出门都不好意思跟人打招呼。OpenLedger 就是这股风潮里最典型的一个——打着“AI区块链”的旗号,喊着解决数据确权和收益分配的口号,乍一看高大上,仔细一扒,槽点简直能凑成一部连续剧。
首先,它那个被吹上天的 Proof of Attribution(归因证明),说白了不就是想给 AI 算账吗?可现实是啥?现在的通用大模型连自己上一秒说了啥都记不清,你指望一个链上协议能精准追踪到每一行代码、每一个 token 到底是谁贡献的?这就好比让一个近视眼去穿针引线,还非得用显微镜看!真当算法是神仙啊?这玩意儿在实验室里跑跑 Demo 就算了,真要大规模商用,算力成本和延迟能把人拖死。
再看它的代币 $OPEN,简直是教科书级别的“既要又要”。一会儿说它是 Gas 费,一会儿又说是推理费,还要兼顾分润和治理。好家伙,一个币恨不得干完以太坊加 Bittensor 所有的活儿。结果呢?社区拿大头,团队和投资人锁仓一年再慢慢线性释放,这不就是典型的“前期靠空投拉人头,后期靠解锁割韭菜”的老套路吗?等那帮早期投资者的筹码一到解禁期,你看盘面还能不能撑得住“Payable AI”的宏大叙事。
还有那个 OpenLoRA,号称单卡跑上千个模型,听着像印钞机一样爽。但稍微懂点技术的都知道,这种极限压榨显存的操作,在实际生产环境里就是个理想化的上限。真到了高并发的时候,性能不掉线才怪。
说到底,OpenLedger 就是把一堆 Web3 的概念强行缝合进了 AI 的黑盒子里。故事讲得确实动听,但在真正的技术壁垒面前,这些花里胡哨的经济模型,不过是给镰刀镀了层金而已。
@Openledger #openledger $OPEN
现在这币圈,只要是个项目,不往自己身上贴个“AI”的标签,出门都不好意思跟人打招呼。OpenLedger 就是这股风潮里最典型的一个——打着“AI区块链”的旗号,喊着解决数据确权和收益分配的口号,乍一看高大上,仔细一扒,槽点简直能凑成一部连续剧。
首先,它那个被吹上天的 Proof of Attribution(归因证明),说白了不就是想给 AI 算账吗?可现实是啥?现在的通用大模型连自己上一秒说了啥都记不清,你指望一个链上协议能精准追踪到每一行代码、每一个 token 到底是谁贡献的?这就好比让一个近视眼去穿针引线,还非得用显微镜看!真当算法是神仙啊?这玩意儿在实验室里跑跑 Demo 就算了,真要大规模商用,算力成本和延迟能把人拖死。
再看它的代币 $OPEN ,简直是教科书级别的“既要又要”。一会儿说它是 Gas 费,一会儿又说是推理费,还要兼顾分润和治理。好家伙,一个币恨不得干完以太坊加 Bittensor 所有的活儿。结果呢?社区拿大头,团队和投资人锁仓一年再慢慢线性释放,这不就是典型的“前期靠空投拉人头,后期靠解锁割韭菜”的老套路吗?等那帮早期投资者的筹码一到解禁期,你看盘面还能不能撑得住“Payable AI”的宏大叙事。
还有那个 OpenLoRA,号称单卡跑上千个模型,听着像印钞机一样爽。但稍微懂点技术的都知道,这种极限压榨显存的操作,在实际生产环境里就是个理想化的上限。真到了高并发的时候,性能不掉线才怪。
说到底,OpenLedger 就是把一堆 Web3 的概念强行缝合进了 AI 的黑盒子里。故事讲得确实动听,但在真正的技术壁垒面前,这些花里胡哨的经济模型,不过是给镰刀镀了层金而已。
@OpenLedger #openledger $OPEN
2
252
·
--
Why OpenLedger is part of the next generation internet narrativeWasn't really planning to go deep today. Had the charts open, OPEN was doing the usual — hovering around the same range it's been stuck in for weeks, nothing dramatic. Market felt like it was waiting for something. So I closed the price tab and pulled up something I'd bookmarked a while back, just to fill the time.
Started reading through some OpenLedger, $OPEN , #OpenLedger @Openledger documentation. Had an angle in my head going in — the whole "next generation internet" pitch. Web3. Decentralization. User ownership. The kind of thing that sounds impressive at a conference and then evaporates when you try to point to something concrete.
But I sat with it longer than I expected to. And something came loose.
Here's the realization. Every generation of the internet has been defined not by what users got to do — but by who controlled the underlying infrastructure layer that everything else ran on.
Web1: whoever owned the servers had the leverage. Those were the ISPs, the hosting companies, the router infrastructure. The application layer on top was almost irrelevant — the infrastructure was the moat.
Web2: the infrastructure became the platforms. Facebook, Google, AWS. The data pipelines and distribution rails. Once they owned the pipes your content flowed through, they owned the value. And they were right — user-facing applications on top came and went, but whoever ran the infrastructure printed money.
Now look at what AI is doing to the internet. The application layer is changing constantly — new interfaces, new chatbots, new products. But underneath all of it, there is one thing that the entire AI economy depends on: training data and the models built from it. That's the new infrastructure layer.
And right now, it's entirely owned by a handful of private companies. Same structure. Different layer.
OpenLedger is trying to make that layer ownable and settleable by the network — not by a corporation. Not as a fairness gesture. As an infrastructure play. The Proof of Attribution system, the Datanets, the on-chain lineage — it's all aimed at the same thing: making intelligence infrastructure function more like a protocol than a proprietary product.
That reframe hit differently than the usual "Web3 narrative" pitch. Because Web3 often ends up being about applications — NFTs, DAO voting, token-gated communities. Interesting maybe, but not infrastructure. This is infrastructure-level positioning.
I thought "okay, this is a compelling thesis." But then I checked the actual chain data. DeFiLlama has annual protocol revenue at $693K. Fees dropped another 23% this past week. The circulating supply has expanded to over 290M tokens from 215.5M at launch — meaning a lot of tokens went out the door and relatively little revenue came back in.
And that's the quiet problem with infrastructure bets. The idea can be structurally correct and still fail. Infrastructure requires enormous network scale to generate moat value. TCP/IP is the protocol that runs the internet — but the companies that tried to own variants of TCP/IP mostly disappeared. The ones that survived were the ones that reached critical mass before competitors did.
OpenLedger has the positioning right. Whether it reaches the adoption threshold before the September 2026 investor unlocks arrive, before better-funded competitors converge on the same territory, before the window closes… that I can't tell from the current numbers.
The idea is right. The timing is the gamble.
Still watching. Nothing obvious to do right now.
Why OpenLedger is part of the next generation internet narrative
Wasn't really planning to go deep today. Had the charts open, OPEN was doing the usual — hovering around the same range it's been stuck in for weeks, nothing dramatic. Market felt like it was waiting for something. So I closed the price tab and pulled up something I'd bookmarked a while back, just to fill the time.
Started reading through some OpenLedger, $OPEN , #OpenLedger @OpenLedger documentation. Had an angle in my head going in — the whole "next generation internet" pitch. Web3. Decentralization. User ownership. The kind of thing that sounds impressive at a conference and then evaporates when you try to point to something concrete.
But I sat with it longer than I expected to. And something came loose.
Here's the realization. Every generation of the internet has been defined not by what users got to do — but by who controlled the underlying infrastructure layer that everything else ran on.
Web1: whoever owned the servers had the leverage. Those were the ISPs, the hosting companies, the router infrastructure. The application layer on top was almost irrelevant — the infrastructure was the moat.
Web2: the infrastructure became the platforms. Facebook, Google, AWS. The data pipelines and distribution rails. Once they owned the pipes your content flowed through, they owned the value. And they were right — user-facing applications on top came and went, but whoever ran the infrastructure printed money.
Now look at what AI is doing to the internet. The application layer is changing constantly — new interfaces, new chatbots, new products. But underneath all of it, there is one thing that the entire AI economy depends on: training data and the models built from it. That's the new infrastructure layer.
And right now, it's entirely owned by a handful of private companies. Same structure. Different layer.
OpenLedger is trying to make that layer ownable and settleable by the network — not by a corporation. Not as a fairness gesture. As an infrastructure play. The Proof of Attribution system, the Datanets, the on-chain lineage — it's all aimed at the same thing: making intelligence infrastructure function more like a protocol than a proprietary product.
That reframe hit differently than the usual "Web3 narrative" pitch. Because Web3 often ends up being about applications — NFTs, DAO voting, token-gated communities. Interesting maybe, but not infrastructure. This is infrastructure-level positioning.
I thought "okay, this is a compelling thesis." But then I checked the actual chain data. DeFiLlama has annual protocol revenue at $693K. Fees dropped another 23% this past week. The circulating supply has expanded to over 290M tokens from 215.5M at launch — meaning a lot of tokens went out the door and relatively little revenue came back in.
And that's the quiet problem with infrastructure bets. The idea can be structurally correct and still fail. Infrastructure requires enormous network scale to generate moat value. TCP/IP is the protocol that runs the internet — but the companies that tried to own variants of TCP/IP mostly disappeared. The ones that survived were the ones that reached critical mass before competitors did.
OpenLedger has the positioning right. Whether it reaches the adoption threshold before the September 2026 investor unlocks arrive, before better-funded competitors converge on the same territory, before the window closes… that I can't tell from the current numbers.
The idea is right. The timing is the gamble.
Still watching. Nothing obvious to do right now.
3
2
105
·
--
Most people think the AI race is about who can build the smartest model.
I'm starting to think that's only half the story.
The more I follow AI, the more it feels like we're watching two different competitions happen at the same time. One is obvious: bigger models, more compute, better performance. Everyone talks about that part.
The other competition is much quieter.
It's about incentives.
Every AI system depends on people somewhere in the process. People generate data, provide expertise, create content, label information, test products, and help improve outputs. Without that layer, even the most advanced model has nothing useful to learn from.
Yet once the model is deployed, most of those contributors disappear from the picture.
That's why I found OpenLedger interesting.
At first I assumed it was another project focused mainly on AI infrastructure. After spending more time looking into it, what stood out wasn't the technology itself. It was the attempt to connect contributors, builders, and users inside the same economic system.
The idea seems simple on the surface.
If data helps create value, should the people contributing that data participate in the upside?
That sounds reasonable, but it's actually a difficult problem. Measuring contribution is hard. Rewarding people fairly is even harder. And creating incentives that don't get abused is harder still.
Which is why I think the real challenge isn't building the marketplace.
It's making the marketplace work.
A lot of projects can launch a platform. Far fewer can create an ecosystem where better contributions consistently lead to better outcomes for everyone involved.
Maybe OpenLedger succeeds. Maybe it doesn't.
But I do think it's asking one of the more important questions in AI right now:
As intelligent systems become more valuable, who should own the value they create?
The answer isn't as obvious as it first seems.
@Openledger $OPEN #OpenLedger
Most people think the AI race is about who can build the smartest model.
I'm starting to think that's only half the story.
The more I follow AI, the more it feels like we're watching two different competitions happen at the same time. One is obvious: bigger models, more compute, better performance. Everyone talks about that part.
The other competition is much quieter.
It's about incentives.
Every AI system depends on people somewhere in the process. People generate data, provide expertise, create content, label information, test products, and help improve outputs. Without that layer, even the most advanced model has nothing useful to learn from.
Yet once the model is deployed, most of those contributors disappear from the picture.
That's why I found OpenLedger interesting.
At first I assumed it was another project focused mainly on AI infrastructure. After spending more time looking into it, what stood out wasn't the technology itself. It was the attempt to connect contributors, builders, and users inside the same economic system.
The idea seems simple on the surface.
If data helps create value, should the people contributing that data participate in the upside?
That sounds reasonable, but it's actually a difficult problem. Measuring contribution is hard. Rewarding people fairly is even harder. And creating incentives that don't get abused is harder still.
Which is why I think the real challenge isn't building the marketplace.
It's making the marketplace work.
A lot of projects can launch a platform. Far fewer can create an ecosystem where better contributions consistently lead to better outcomes for everyone involved.
Maybe OpenLedger succeeds. Maybe it doesn't.
But I do think it's asking one of the more important questions in AI right now:
As intelligent systems become more valuable, who should own the value they create?
The answer isn't as obvious as it first seems.
@OpenLedger $OPEN #OpenLedger
22
9
377
·
--
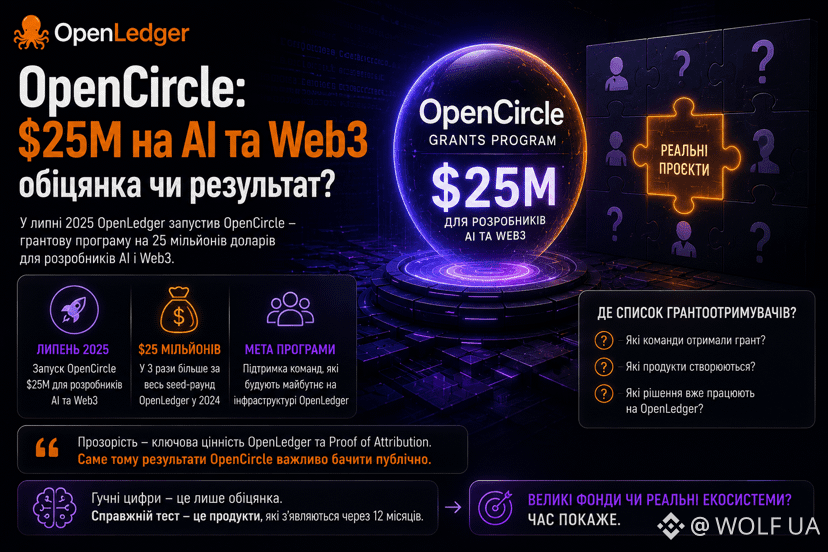
#OpenLedger Переглядав підсумки року від @Openledger і одна деталь змусила мене затриматися довше.
OpenCircle — грантова програма на $25 мільйонів для AI та Web3-розробників. Для молодого проєкту це не просто ще один пункт у roadmap, а досить гучна ставка на майбутню екосистему.
Але мене зацікавила не сама цифра.
Мені стало цікаво, що відбулося після анонсу.
Бо справжня сила грантової програми вимірюється не розміром фонду, а тим, які продукти вона народила.
Я почав шукати команди, що отримали підтримку, готові рішення, нові проєкти всередині OpenLedger-екосистеми. Публічної картини з конкретними прикладами поки не побачив.
Можливо, усе ще на етапі розробки. Можливо, результати просто не винесли назовні.
Але для проєкту, який будує ідею навколо прозорості та Proof of Attribution, саме цей розвиток буде цікаво відстежити.
А як думаєш: великі грантові фонди в крипті частіше створюють реальні екосистеми чи залишаються сильними лише в день анонсу?
@Openledger #OpenLedger $OPEN
#OpenLedger Переглядав підсумки року від @OpenLedger і одна деталь змусила мене затриматися довше.
OpenCircle — грантова програма на $25 мільйонів для AI та Web3-розробників. Для молодого проєкту це не просто ще один пункт у roadmap, а досить гучна ставка на майбутню екосистему.
Але мене зацікавила не сама цифра.
Мені стало цікаво, що відбулося після анонсу.
Бо справжня сила грантової програми вимірюється не розміром фонду, а тим, які продукти вона народила.
Я почав шукати команди, що отримали підтримку, готові рішення, нові проєкти всередині OpenLedger-екосистеми. Публічної картини з конкретними прикладами поки не побачив.
Можливо, усе ще на етапі розробки. Можливо, результати просто не винесли назовні.
Але для проєкту, який будує ідею навколо прозорості та Proof of Attribution, саме цей розвиток буде цікаво відстежити.
А як думаєш: великі грантові фонди в крипті частіше створюють реальні екосистеми чи залишаються сильними лише в день анонсу?
@OpenLedger #OpenLedger $OPEN
3
110
·
--
Рост
I Think OpenLedger Is Quietly Building the Missing Economy Behind AI
The more I explore OpenLedger, the more I feel that most people are looking at it from the wrong angle.
At first, I thought it was simply another project combining AI and blockchain. But the deeper I went, the more I realized that OpenLedger seems focused on something much bigger: the economic coordination of intelligence.
I keep asking myself a simple question: when AI creates value, who actually captures that value?
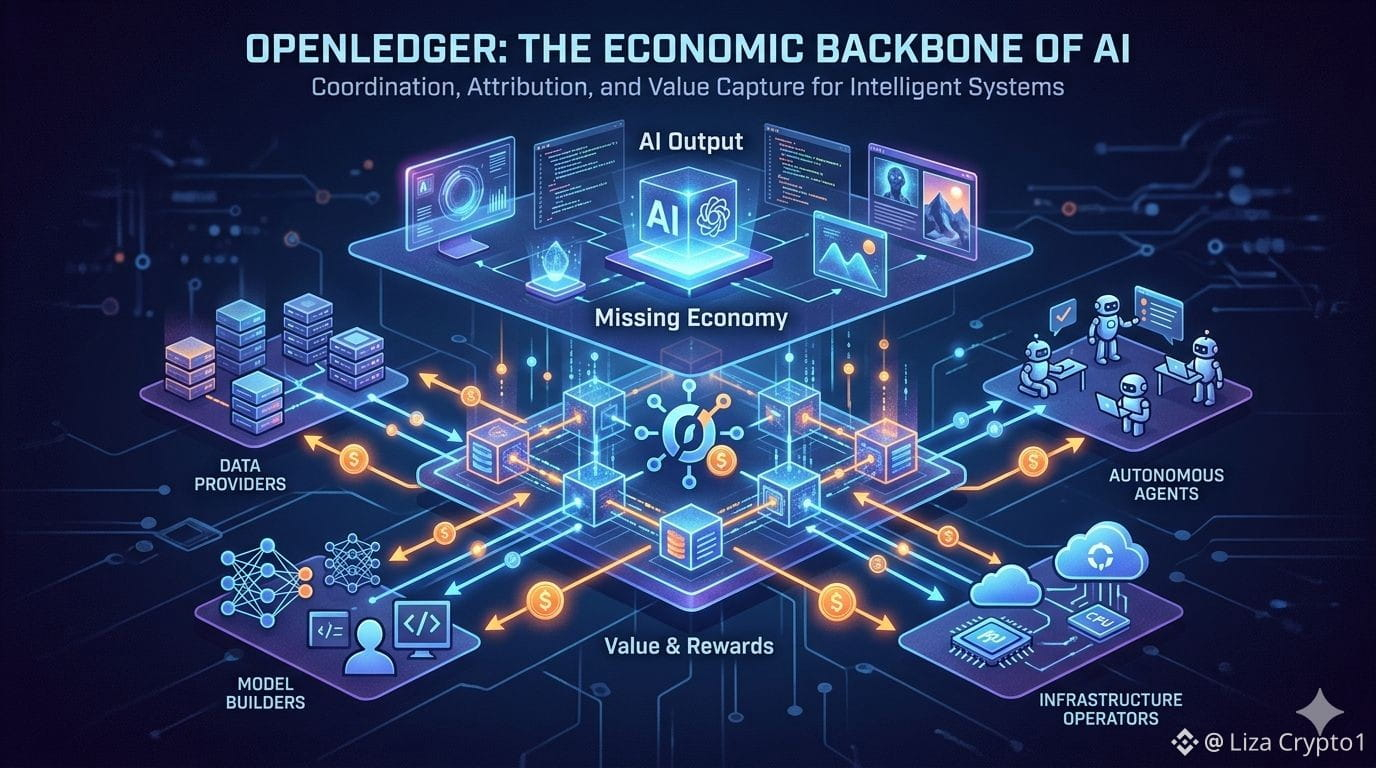
Every AI output is influenced by data providers, model builders, infrastructure operators, and increasingly autonomous agents. Yet once the final result appears, the connection between contribution and reward often disappears. I think this is where OpenLedger becomes interesting.
What stands out to me is that it isn't just trying to make AI more powerful. It appears to be creating a framework where data, models, and agents can remain connected to the value they help generate.
The OPEN token also caught my attention. I don't see it purely as a speculative asset. I see it as a coordination tool that helps align incentives across participants, creating an economic loop around AI activity.
My biggest takeaway is this: most people believe intelligence will be the most valuable resource in the AI era. I increasingly believe attribution may become just as important.
If AI becomes abundant, knowing where value came from—and who deserves to benefit from it—could become the real competitive advantage.
That's why I think OpenLedger is tackling a problem that the market hasn't fully appreciated yet.
@Openledger #OpenLedger $OPEN
{spot}(OPENUSDT)
I Think OpenLedger Is Quietly Building the Missing Economy Behind AI
The more I explore OpenLedger, the more I feel that most people are looking at it from the wrong angle.
At first, I thought it was simply another project combining AI and blockchain. But the deeper I went, the more I realized that OpenLedger seems focused on something much bigger: the economic coordination of intelligence.
I keep asking myself a simple question: when AI creates value, who actually captures that value?
Every AI output is influenced by data providers, model builders, infrastructure operators, and increasingly autonomous agents. Yet once the final result appears, the connection between contribution and reward often disappears. I think this is where OpenLedger becomes interesting.
What stands out to me is that it isn't just trying to make AI more powerful. It appears to be creating a framework where data, models, and agents can remain connected to the value they help generate.
The OPEN token also caught my attention. I don't see it purely as a speculative asset. I see it as a coordination tool that helps align incentives across participants, creating an economic loop around AI activity.
My biggest takeaway is this: most people believe intelligence will be the most valuable resource in the AI era. I increasingly believe attribution may become just as important.
If AI becomes abundant, knowing where value came from—and who deserves to benefit from it—could become the real competitive advantage.
That's why I think OpenLedger is tackling a problem that the market hasn't fully appreciated yet.
@OpenLedger #OpenLedger $OPEN
1
132
·
--
Статья
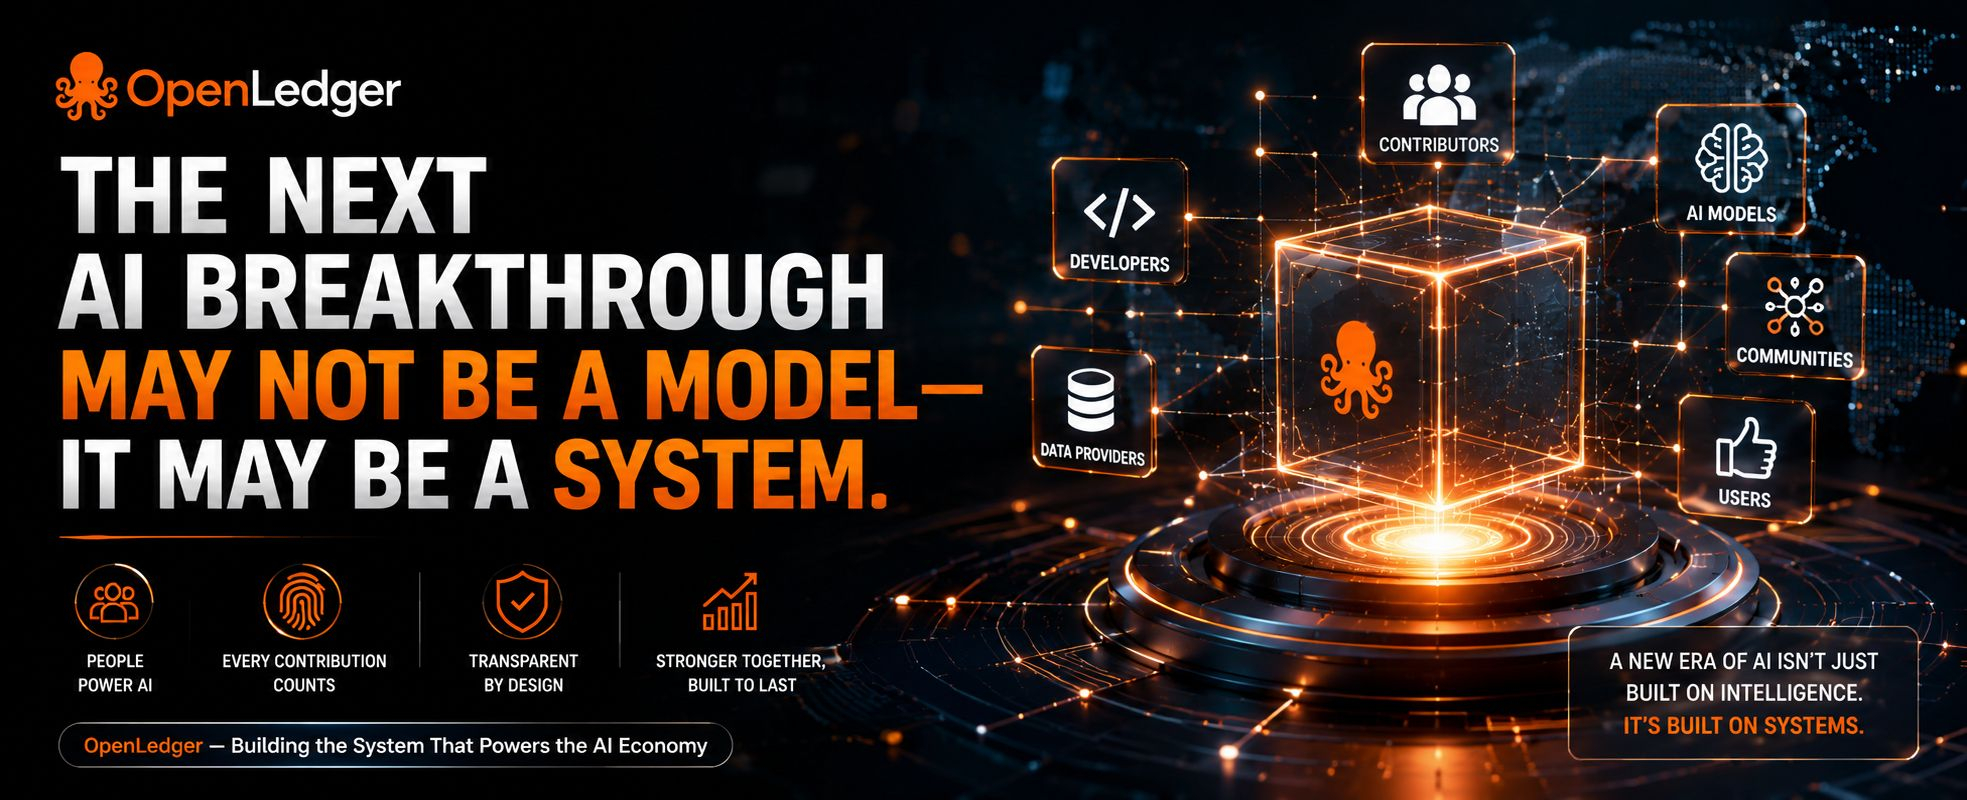
The Next AI Breakthrough May Not Be a Model — It May Be a SystemEvery day, the AI industry celebrates a new achievement.
A faster model.
A smarter assistant.
A more powerful tool.
And while those developments are exciting, I think many people are focused on only one side of the story.
The future of AI won't be determined solely by which model performs best.
It will also be determined by which systems create the strongest ecosystems around intelligence.
That is one of the reasons OpenLedger continues to stand out to me.
The project isn't only exploring how AI can become more capable. It is exploring how AI ecosystems can become more sustainable. And as artificial intelligence expands into every corner of the digital economy, that question feels increasingly important.
Today's AI networks rely on contributions from countless participants. Developers build infrastructure. Researchers improve models. Communities provide feedback. Data contributors help shape the quality of intelligence itself.
Yet in many cases, the connection between contribution and value remains unclear.
Over time, that creates a challenge.
Strong ecosystems require more than innovation. They require trust. They require participation. And they require incentives that encourage people to keep contributing over the long term.
This is where OpenLedger's vision becomes particularly interesting.
Instead of focusing exclusively on outputs, the ecosystem appears designed around transparency attribution, and measurable contribution. The idea is simple but powerful: when people can see how value is created and how participation matters they become more invested in the network's success.
That creates a different type of growth.
Not growth driven purely by attention.
But growth driven by engagement.
And historically, engagement tends to be more durable than hype.
What I find most compelling is that this approach aligns with the direction AI appears to be heading. As intelligent systems become more important questions about accountability and ownership will become harder to ignore.
People will want systems they can trust.
Builders will want ecosystems that recognize their efforts.
Communities will want transparency.
The projects that solve those challenges may end up becoming some of the most important infrastructure layers in the AI economy.
That is why OpenLedger feels increasingly relevant to me.
Not because it promises the loudest future.
But because it is asking some of the most important questions about how that future should work.
And sometimes, the systems that ask the right questions end up shaping the next era of innovation.
@Openledger |. #OpenLedger
$OPEN
{future}(OPENUSDT)
The Next AI Breakthrough May Not Be a Model — It May Be a System
Every day, the AI industry celebrates a new achievement.
A faster model.
A smarter assistant.
A more powerful tool.
And while those developments are exciting, I think many people are focused on only one side of the story.
The future of AI won't be determined solely by which model performs best.
It will also be determined by which systems create the strongest ecosystems around intelligence.
That is one of the reasons OpenLedger continues to stand out to me.
The project isn't only exploring how AI can become more capable. It is exploring how AI ecosystems can become more sustainable. And as artificial intelligence expands into every corner of the digital economy, that question feels increasingly important.
Today's AI networks rely on contributions from countless participants. Developers build infrastructure. Researchers improve models. Communities provide feedback. Data contributors help shape the quality of intelligence itself.
Yet in many cases, the connection between contribution and value remains unclear.
Over time, that creates a challenge.
Strong ecosystems require more than innovation. They require trust. They require participation. And they require incentives that encourage people to keep contributing over the long term.
This is where OpenLedger's vision becomes particularly interesting.
Instead of focusing exclusively on outputs, the ecosystem appears designed around transparency attribution, and measurable contribution. The idea is simple but powerful: when people can see how value is created and how participation matters they become more invested in the network's success.
That creates a different type of growth.
Not growth driven purely by attention.
But growth driven by engagement.
And historically, engagement tends to be more durable than hype.
What I find most compelling is that this approach aligns with the direction AI appears to be heading. As intelligent systems become more important questions about accountability and ownership will become harder to ignore.
People will want systems they can trust.
Builders will want ecosystems that recognize their efforts.
Communities will want transparency.
The projects that solve those challenges may end up becoming some of the most important infrastructure layers in the AI economy.
That is why OpenLedger feels increasingly relevant to me.
Not because it promises the loudest future.
But because it is asking some of the most important questions about how that future should work.
And sometimes, the systems that ask the right questions end up shaping the next era of innovation.
@OpenLedger |. #OpenLedger
$OPEN
3
3
138
Статья
OpenLedger Made Me Question Who Actually Owns IntelligenceFor a long time, I assumed ownership was a pretty simple concept.
You can own land. you can own a business. You can own shares in a company. In crypto, you can even own digital assets that exist entirely online.
but recently I found myself thinkIng about something much stranger.
Can anyone actualLy own inTelligence?
At first, that sounds liKe a philosophical question. the more I looked at projects like OpenLedger, though, the more it started feelIng liKe an economic question.
most people looking at OpenLedger see an AI blockchain. They see data attribution, decentralized model development, token incentives, and specialized AI models.
that is the obvious story.
What caught my attentIon was something underneath all of that.
I think OpenLedger is making a much bigger bet than most people realize.
it is betting that inteLligence itself is becoming an asset class.
throughout history, economies have been buIlt around ownership.
Agricultural economies were built around land ownershIp.
Industrial economies were built around capital ownership.
Internet economies were built around platform ownership.
the AI economy may be built around intelligence ownership.
and that is where things become interesting.
Today is AI systems are trained using enormous amounts of human knowledge. Researchers contrIbute ideas. experts contribute domain expertise. Communities generate datasets. users provide feedback that improves models over time.
Yet when value is created, most contributors disappear from the economic equation.
The model earns value.
The platform earns revenue.
The intelligence improves.
but the people who helped create that intelligence often receive nothing.
What OpenLedger appears to be asking is a very different question.
what if intelligence could have an ownership history?
Not ownership of the model itself.
Ownership of the contributions that made the model useful.
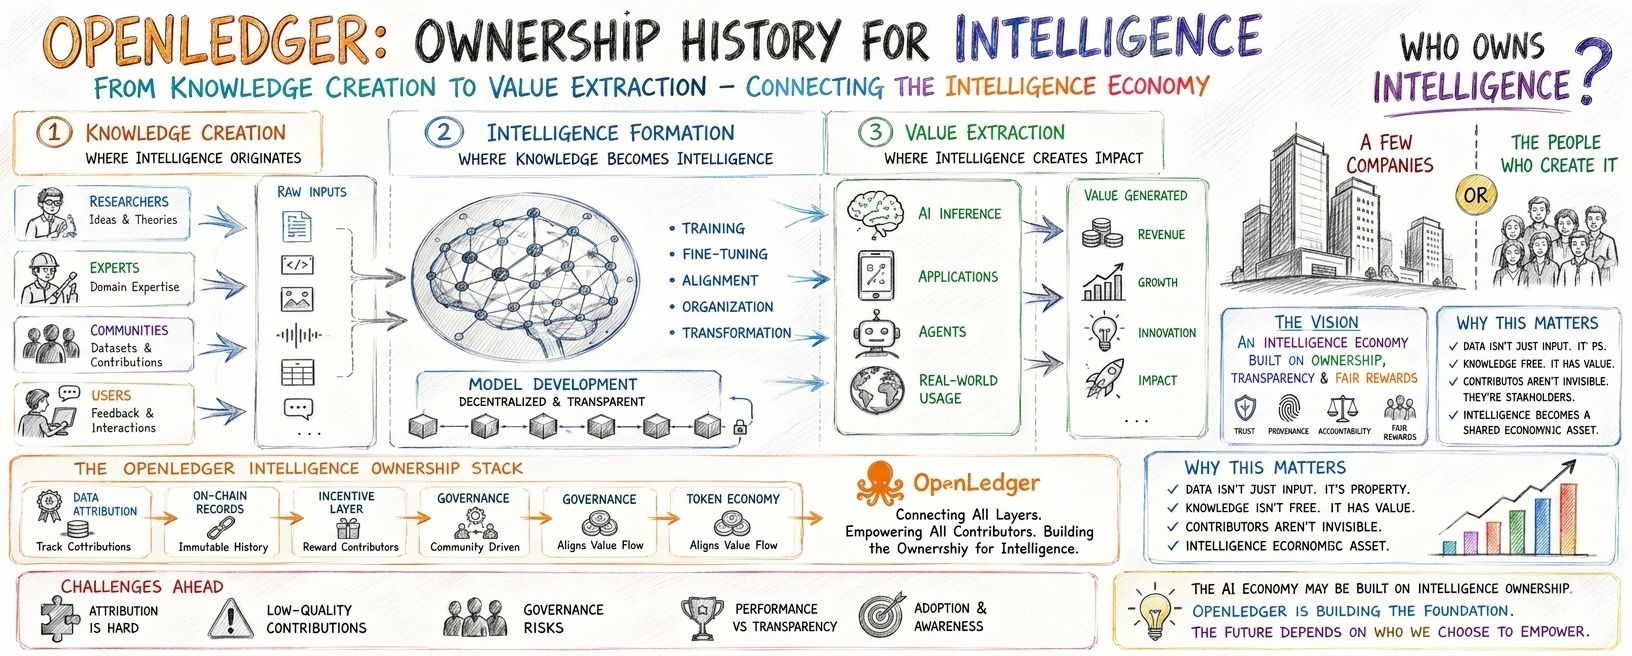
I keep coming back to what I call the Intelligence Ownership Stack.
The first layer is Knowledge Creation.
This is where data, expertise, observations, and domain-specific insights originate.
The second layer is Intelligence Formation.
This is where models absorb, organize, and transform knowledge into usable intelligence.
The third layer is Value Extraction.
This is where AI generates economic value through inference, applications, agents, and real-world usage.
Most AI companies capture value primarily at the third layer.
OpenLedger is attempting to connect all three.
If that works, the implications go far beyond one project.
Data stops being a raw input.
Knowledge stops being a free resource.
Contributors stop being invisible participants.
Instead, they become stakeholders in the intelligence economy.
That idea sounds ambitious, and there are real reasons it may fail.
Attribution is incredibly difficult to measure accurately. Incentive systems can attract low-quality contributions. Governance can become concentrated. Users may care more about performance than transparency.
Those are serious challenges.
But even if OpenLedger never achieves its full vision, I think it highlights a trend the market is underestimating.
For years, crypto has focused on ownership of assets.
Bitcoin introduced ownership of money.
Ethereum introduced ownership of programmable value.
DeFi introduced ownership of financial activity.
AI may force crypto to tackle something much harder: ownership of intelligence production.
That's a much larger market than most people are discussing.
The more AI becomes integrated into everyday decision-making, the more valuable attribution becomes. Not just for rewards, but for accountability, trust, provenance, and economic coordination.
In a strange way, OpenLedger feels less like an AI project and more like an experiment in creating property rights for intelligence.
And that leaves me with a question I can't stop thinking about.
If intelligence becomes one of the most valuable resources in the digital economy, will it be owned by a handful of companies...
Or by the people who helped create it in the first place?
@Openledger $OPEN #OpenLedger
OpenLedger Made Me Question Who Actually Owns Intelligence
For a long time, I assumed ownership was a pretty simple concept.
You can own land. you can own a business. You can own shares in a company. In crypto, you can even own digital assets that exist entirely online.
but recently I found myself thinkIng about something much stranger.
Can anyone actualLy own inTelligence?
At first, that sounds liKe a philosophical question. the more I looked at projects like OpenLedger, though, the more it started feelIng liKe an economic question.
most people looking at OpenLedger see an AI blockchain. They see data attribution, decentralized model development, token incentives, and specialized AI models.
that is the obvious story.
What caught my attentIon was something underneath all of that.
I think OpenLedger is making a much bigger bet than most people realize.
it is betting that inteLligence itself is becoming an asset class.
throughout history, economies have been buIlt around ownership.
Agricultural economies were built around land ownershIp.
Industrial economies were built around capital ownership.
Internet economies were built around platform ownership.
the AI economy may be built around intelligence ownership.
and that is where things become interesting.
Today is AI systems are trained using enormous amounts of human knowledge. Researchers contrIbute ideas. experts contribute domain expertise. Communities generate datasets. users provide feedback that improves models over time.
Yet when value is created, most contributors disappear from the economic equation.
The model earns value.
The platform earns revenue.
The intelligence improves.
but the people who helped create that intelligence often receive nothing.
What OpenLedger appears to be asking is a very different question.
what if intelligence could have an ownership history?
Not ownership of the model itself.
Ownership of the contributions that made the model useful.
I keep coming back to what I call the Intelligence Ownership Stack.
The first layer is Knowledge Creation.
This is where data, expertise, observations, and domain-specific insights originate.
The second layer is Intelligence Formation.
This is where models absorb, organize, and transform knowledge into usable intelligence.
The third layer is Value Extraction.
This is where AI generates economic value through inference, applications, agents, and real-world usage.
Most AI companies capture value primarily at the third layer.
OpenLedger is attempting to connect all three.
If that works, the implications go far beyond one project.
Data stops being a raw input.
Knowledge stops being a free resource.
Contributors stop being invisible participants.
Instead, they become stakeholders in the intelligence economy.
That idea sounds ambitious, and there are real reasons it may fail.
Attribution is incredibly difficult to measure accurately. Incentive systems can attract low-quality contributions. Governance can become concentrated. Users may care more about performance than transparency.
Those are serious challenges.
But even if OpenLedger never achieves its full vision, I think it highlights a trend the market is underestimating.
For years, crypto has focused on ownership of assets.
Bitcoin introduced ownership of money.
Ethereum introduced ownership of programmable value.
DeFi introduced ownership of financial activity.
AI may force crypto to tackle something much harder: ownership of intelligence production.
That's a much larger market than most people are discussing.
The more AI becomes integrated into everyday decision-making, the more valuable attribution becomes. Not just for rewards, but for accountability, trust, provenance, and economic coordination.
In a strange way, OpenLedger feels less like an AI project and more like an experiment in creating property rights for intelligence.
And that leaves me with a question I can't stop thinking about.
If intelligence becomes one of the most valuable resources in the digital economy, will it be owned by a handful of companies...
Or by the people who helped create it in the first place?
@OpenLedger $OPEN #OpenLedger
4
5
222
·
--
Проверено
I used to think building in Web3 was only for people who enjoy staring at code for hours. I respect that skill, but honestly, it can make good ideas die before they even get tested.
That is why the vibecoding angle with @Openledger feels interesting to me.
The way I see it, a lot of people already have useful ideas for AI agents, data tools, trading helpers, or simple Web3 apps. The problem is not always imagination. The problem is getting from idea to first working version without feeling stuck at every technical step.
If OpenLedger can make that process easier, then more small builders may start experimenting. Not every experiment will become huge, and that is fine. Real ecosystems usually grow from messy testing, feedback, and people trying things that look small at first.
From my perspective, vibecoding is not about replacing developers. It is about giving more people the confidence to start.
That could matter a lot for $OPEN if those experiments turn into real activity inside the ecosystem.
Would you try vibecoding on OpenLedger?
#OpenLedger
$LAB
$CITY
{future}(OPENUSDT)
I used to think building in Web3 was only for people who enjoy staring at code for hours. I respect that skill, but honestly, it can make good ideas die before they even get tested.
That is why the vibecoding angle with @OpenLedger feels interesting to me.
The way I see it, a lot of people already have useful ideas for AI agents, data tools, trading helpers, or simple Web3 apps. The problem is not always imagination. The problem is getting from idea to first working version without feeling stuck at every technical step.
If OpenLedger can make that process easier, then more small builders may start experimenting. Not every experiment will become huge, and that is fine. Real ecosystems usually grow from messy testing, feedback, and people trying things that look small at first.
From my perspective, vibecoding is not about replacing developers. It is about giving more people the confidence to start.
That could matter a lot for $OPEN if those experiments turn into real activity inside the ecosystem.
Would you try vibecoding on OpenLedger?
#OpenLedger
$LAB
$CITY
Yes, I’d build fast
50%
Maybe for AI tools
50%
Need to learn more
0%
Not for me yet
0%
4 проголосовали • Голосование закрыто
13
10
966
·
--
@Openledger #OpenLedger
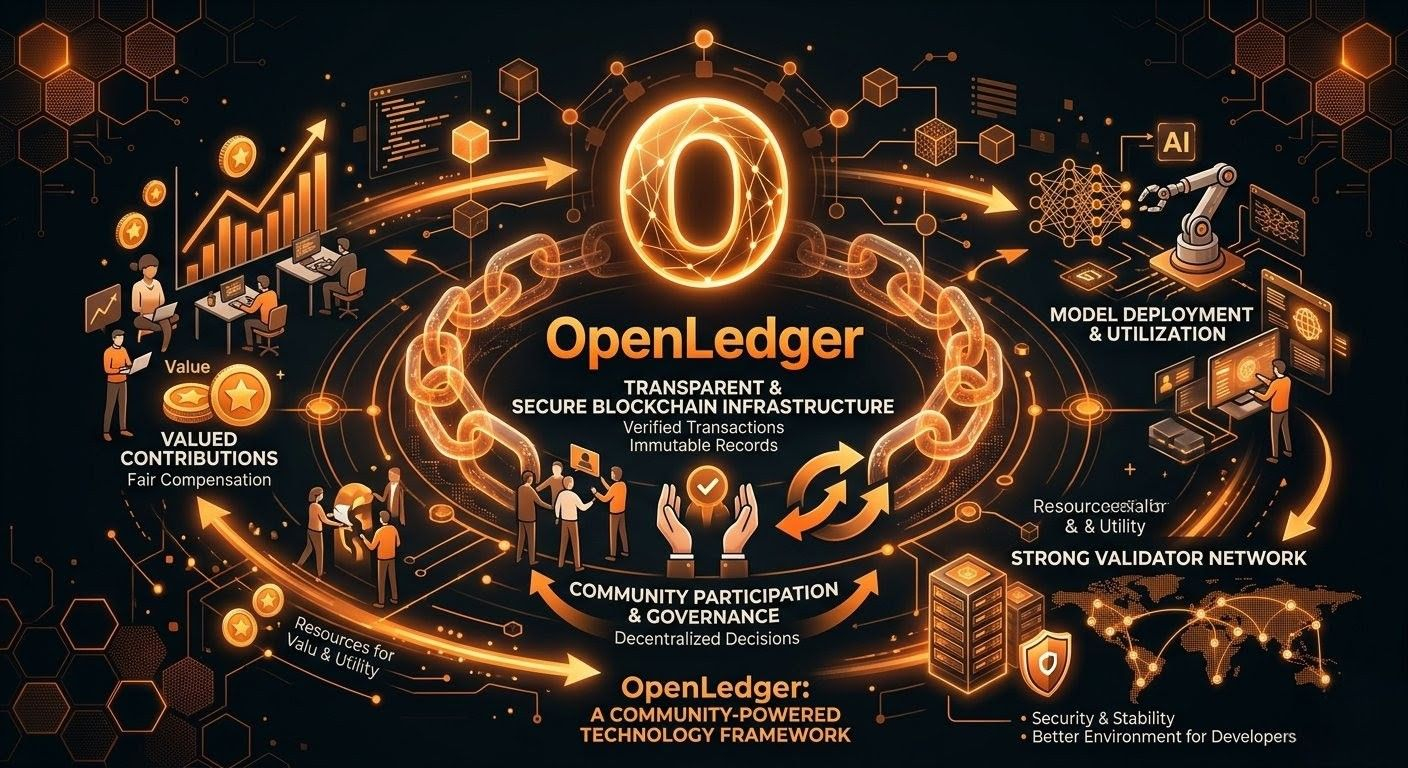
OpenLedger ka ecosystem sirf technology par mabni platform nahi, balki ek aisa framework hai jahan transparency, accountability aur community participation ko central importance di gayi hai. Is system ka maqsad yeh ensure karna hai ke har contribution ki proper value ho aur platform ki growth sab stakeholders ke liye faidemand sabit ho.
Blockchain infrastructure OpenLedger ki bunyad ko mazboot banata hai. Har transaction aur contribution ka record securely maintain kiya jata hai, jis se ecosystem mein trust aur reliability barhti hai. Participants kisi bhi activity ko verify kar sakte hain, jo transparency ko ek naye level tak le jata hai.
Governance bhi is ecosystem ka aham hissa hai. Community-backed decision making ki wajah se resources un projects aur models ki taraf direct hote hain jo waqai demand aur utility rakhte hain. Is approach se unnecessary development kam hoti hai aur innovation ko behtar direction milti hai.
Jab models deploy hote hain aur users un se interact karte hain, to network activity barhti hai. Yeh activity validators ke liye naye opportunities create karti hai, jo infrastructure ko stable aur secure rakhne mein apna kirdar ada karte hain. Strong validator participation poore network ki performance ko improve karti hai aur developers ke liye behtar environment create karti hai.
OpenLedger ki sab se bari strength blockchain aur model ecosystem ke darmiyan maujood connection hai. Ek taraf transparent infrastructure trust provide karta hai, jabke doosri taraf innovation aur practical utility ecosystem ki value ko barhati hai. Dono mil kar ek aisa cycle create karte hain jahan growth, participation aur development lagataar ek dusre ko support karte rehte hain.
Isi balanced approach ki wajah se OpenLedger ek aisa ecosystem tayar kar raha hai jahan technology ke sath sath community ownership aur long-term sustainability ko bhi equal importance di jati hai.
$OPEN
{spot}(OPENUSDT)
@OpenLedger #OpenLedger
OpenLedger ka ecosystem sirf technology par mabni platform nahi, balki ek aisa framework hai jahan transparency, accountability aur community participation ko central importance di gayi hai. Is system ka maqsad yeh ensure karna hai ke har contribution ki proper value ho aur platform ki growth sab stakeholders ke liye faidemand sabit ho.
Blockchain infrastructure OpenLedger ki bunyad ko mazboot banata hai. Har transaction aur contribution ka record securely maintain kiya jata hai, jis se ecosystem mein trust aur reliability barhti hai. Participants kisi bhi activity ko verify kar sakte hain, jo transparency ko ek naye level tak le jata hai.
Governance bhi is ecosystem ka aham hissa hai. Community-backed decision making ki wajah se resources un projects aur models ki taraf direct hote hain jo waqai demand aur utility rakhte hain. Is approach se unnecessary development kam hoti hai aur innovation ko behtar direction milti hai.
Jab models deploy hote hain aur users un se interact karte hain, to network activity barhti hai. Yeh activity validators ke liye naye opportunities create karti hai, jo infrastructure ko stable aur secure rakhne mein apna kirdar ada karte hain. Strong validator participation poore network ki performance ko improve karti hai aur developers ke liye behtar environment create karti hai.
OpenLedger ki sab se bari strength blockchain aur model ecosystem ke darmiyan maujood connection hai. Ek taraf transparent infrastructure trust provide karta hai, jabke doosri taraf innovation aur practical utility ecosystem ki value ko barhati hai. Dono mil kar ek aisa cycle create karte hain jahan growth, participation aur development lagataar ek dusre ko support karte rehte hain.
Isi balanced approach ki wajah se OpenLedger ek aisa ecosystem tayar kar raha hai jahan technology ke sath sath community ownership aur long-term sustainability ko bhi equal importance di jati hai.
$OPEN
5
2
120
·
--
Проверено
老家亲戚开了家小超市,去年图新鲜上了套刷脸支付,说是高科技。用了俩月就拆了,亲戚一脸肉疼:每笔交易都得联网验证,网一卡顾客就在收银台前干等,高峰期排长队,老人家根本玩不转,那点设备钱和手续费,比省下的人工贵多了。他撂下一句:"技术是好技术,可它太重了,压得小本生意喘不过气。"
这句"太重了",让我读 @Openledger 白皮书第10页那个推理费公式时,心里打了个问号。
白皮书的核心卖点之一,是一切都上链、可追溯、可结算。每一次模型推理调用,都用 $OPEN 代币结算,第2.2.4节还把这笔钱拆成模型费、质押费、数据贡献费,每个环节都精确分账。听起来颗粒度细到令人安心。
可我亲戚那句"太重了"在脑子里挥之不去。AI推理这玩意儿,本来追求的就是快和便宜——你问AI一句话,它得在零点几秒里给你回。可如果每一次调用都要在链上记账、做归因、给一堆地址分钱,这笔上链的开销和延迟,谁来扛?
白皮书提了一嘴用 Rollup 做优化,可具体能压到多快、单次调用的成本到底是几分钱还是几块钱,没亮出实数。这就尴尬了:AI应用是个对延迟和成本极度敏感的高频场景,跟金融转账那种"慢一点贵一点也认"的低频场景,完全不是一回事。$LAB #BTC
我管这叫"上链结算的重量诅咒"。透明和可追溯听着很美,可它们是有重量的,每一次记账都在给推理加码。如果这份重量压得单次调用又慢又贵,那再公平的分账机制,也可能在性能这关上,被开发者用脚投票给抛弃掉。#OpenLedger
说到底,一套把一切都刻上链的系统,扛得住AI推理那种高频、低延迟、低成本的真实需求吗?
{spot}(OPENUSDT)
老家亲戚开了家小超市,去年图新鲜上了套刷脸支付,说是高科技。用了俩月就拆了,亲戚一脸肉疼:每笔交易都得联网验证,网一卡顾客就在收银台前干等,高峰期排长队,老人家根本玩不转,那点设备钱和手续费,比省下的人工贵多了。他撂下一句:"技术是好技术,可它太重了,压得小本生意喘不过气。"
这句"太重了",让我读 @OpenLedger 白皮书第10页那个推理费公式时,心里打了个问号。
白皮书的核心卖点之一,是一切都上链、可追溯、可结算。每一次模型推理调用,都用 $OPEN 代币结算,第2.2.4节还把这笔钱拆成模型费、质押费、数据贡献费,每个环节都精确分账。听起来颗粒度细到令人安心。
可我亲戚那句"太重了"在脑子里挥之不去。AI推理这玩意儿,本来追求的就是快和便宜——你问AI一句话,它得在零点几秒里给你回。可如果每一次调用都要在链上记账、做归因、给一堆地址分钱,这笔上链的开销和延迟,谁来扛?
白皮书提了一嘴用 Rollup 做优化,可具体能压到多快、单次调用的成本到底是几分钱还是几块钱,没亮出实数。这就尴尬了:AI应用是个对延迟和成本极度敏感的高频场景,跟金融转账那种"慢一点贵一点也认"的低频场景,完全不是一回事。$LAB #BTC
我管这叫"上链结算的重量诅咒"。透明和可追溯听着很美,可它们是有重量的,每一次记账都在给推理加码。如果这份重量压得单次调用又慢又贵,那再公平的分账机制,也可能在性能这关上,被开发者用脚投票给抛弃掉。#OpenLedger
说到底,一套把一切都刻上链的系统,扛得住AI推理那种高频、低延迟、低成本的真实需求吗?
上链会不会拖慢AI?
50%
每次调用要花多少钱?
0%
开发者会用脚投票吗?
50%
2 проголосовали • Голосование закрыто
2
1
673
·
--
今天下午我在商场排队买奶茶,前面两个女生还在纠结“三分糖还是五分糖”,我低头刷了眼链上后台,突然发现自己挂着的Agent已经默默跑完两轮监控了。那一瞬间我脑子里冒出来一句特别奇怪的话:AI好像正在偷偷改变大家对“时间”的感觉。以前做链上操作特别累,你会一直等消息、等异动、等K线、等项目方半夜发推,像坐在锅边守水开,明明什么都没发生,却不敢离开。
我以前就干过这种傻事。记得有次为了盯一个链上机会,我抱着电脑坐在沙发上硬熬,结果凌晨三点行情动了,我反而困得眼睛发花,最后操作还点错链。现在回头看,那种感觉特别像小时候等暗恋的人回消息:手机震一下,心脏跟着跳一下;不震,又开始胡思乱想。可最近折腾@OpenLedger 的Agent之后,我发现自己的时间感开始变了,Research会长期盯信息流,Automate挂后台持续运行,有时候我在逛超市、拆快递、洗头的时候,它还在后台默默扫描市场。
最可怕的是,人会慢慢习惯这种“永远有人替你守夜”的感觉。以前大家还能自己复盘、自己找信号;现在越来越多人,只等系统提醒。说白了,市场正在从“人等机会”,慢慢变成“AI替人等机会”。当然,我现在也没完全觉得这是好事,因为等待本来就是交易的一部分,很多判断力正来自那些无聊、焦躁、反复怀疑自己的时间。
奶茶店这时候正好叫到我的号码,我低头一看,后台又跳出来一条新的执行记录。我拿起奶茶,脑子里还是忍不住想:如果以后这些时间全被AI吞掉,人会不会越来越像“只负责按确认键的人”?@Openledger #openledger $OPEN
今天下午我在商场排队买奶茶,前面两个女生还在纠结“三分糖还是五分糖”,我低头刷了眼链上后台,突然发现自己挂着的Agent已经默默跑完两轮监控了。那一瞬间我脑子里冒出来一句特别奇怪的话:AI好像正在偷偷改变大家对“时间”的感觉。以前做链上操作特别累,你会一直等消息、等异动、等K线、等项目方半夜发推,像坐在锅边守水开,明明什么都没发生,却不敢离开。
我以前就干过这种傻事。记得有次为了盯一个链上机会,我抱着电脑坐在沙发上硬熬,结果凌晨三点行情动了,我反而困得眼睛发花,最后操作还点错链。现在回头看,那种感觉特别像小时候等暗恋的人回消息:手机震一下,心脏跟着跳一下;不震,又开始胡思乱想。可最近折腾@OpenLedger 的Agent之后,我发现自己的时间感开始变了,Research会长期盯信息流,Automate挂后台持续运行,有时候我在逛超市、拆快递、洗头的时候,它还在后台默默扫描市场。
最可怕的是,人会慢慢习惯这种“永远有人替你守夜”的感觉。以前大家还能自己复盘、自己找信号;现在越来越多人,只等系统提醒。说白了,市场正在从“人等机会”,慢慢变成“AI替人等机会”。当然,我现在也没完全觉得这是好事,因为等待本来就是交易的一部分,很多判断力正来自那些无聊、焦躁、反复怀疑自己的时间。
奶茶店这时候正好叫到我的号码,我低头一看,后台又跳出来一条新的执行记录。我拿起奶茶,脑子里还是忍不住想:如果以后这些时间全被AI吞掉,人会不会越来越像“只负责按确认键的人”?@OpenLedger #openledger $OPEN
77
·
--
Рост
Проверено
Раньше я думал, что это стандартный кейс: чем больше участников в сети вроде OpenLedger, тем больше данных, моделей и ИИ-агентов появляется в экосистеме. Логика кажется очевидной — успех платформы должен усиливать желание делиться интеллектом. Но со временем стало ясно, что всё сложнее.
Представьте опытного трейдера, который однажды нашёл прибыльную стратегию. Пока её никто не знает, она приносит преимущество. Чем ценнее становится стратегия, тем меньше причин раскрывать её другим. Это подводит к более глубокому вопросу: что происходит, когда самые полезные модели и данные начинают концентрироваться у тех, кто уже получил выгоду?
Но в реальности всё работает иначе, чем в классических маркетплейсах. OpenLedger строит инфраструктуру, где интеллект может быть монетизирован и получать ликвидность, однако именно здесь возникает главный риск — успешные участники могут предпочесть удерживать лучшие наработки внутри своих экосистем вместо открытого обмена.
Поэтому я смотрю на OpenLedger через призму долгосрочной устойчивости. И проверка проекта начнётся когда владельцам этого актива всё ещё будет выгодно делиться им с сетью.
@Openledger $OPEN #OpenLedger
Раньше я думал, что это стандартный кейс: чем больше участников в сети вроде OpenLedger, тем больше данных, моделей и ИИ-агентов появляется в экосистеме. Логика кажется очевидной — успех платформы должен усиливать желание делиться интеллектом. Но со временем стало ясно, что всё сложнее.
Представьте опытного трейдера, который однажды нашёл прибыльную стратегию. Пока её никто не знает, она приносит преимущество. Чем ценнее становится стратегия, тем меньше причин раскрывать её другим. Это подводит к более глубокому вопросу: что происходит, когда самые полезные модели и данные начинают концентрироваться у тех, кто уже получил выгоду?
Но в реальности всё работает иначе, чем в классических маркетплейсах. OpenLedger строит инфраструктуру, где интеллект может быть монетизирован и получать ликвидность, однако именно здесь возникает главный риск — успешные участники могут предпочесть удерживать лучшие наработки внутри своих экосистем вместо открытого обмена.
Поэтому я смотрю на OpenLedger через призму долгосрочной устойчивости. И проверка проекта начнётся когда владельцам этого актива всё ещё будет выгодно делиться им с сетью.
@OpenLedger $OPEN #OpenLedger
2
810
·
--
Статья
OpenLedger (OPEN) Feels Like One of Those Projects I Can't Easily DismissI've been going down a rabbit hole on OpenLedger and honestly... I'm still not completely sure what to think, which is usually a sign that a project is at least making me think instead of just selling me hype.
Most AI crypto projects lose me pretty fast. After reading enough of them, everything starts sounding the same. Decentralized AI, autonomous agents, revolutionary infrastructure, changing the future... you know the drill. But with OpenLedger, I found myself spending more time trying to understand the actual problem they're aiming at rather than immediately rolling my eyes and moving on.
The thing that caught my attention is this idea that data has value, but the people creating or contributing that data rarely capture any of it. If AI becomes one of the biggest industries in the world, then it feels weird that the value mostly flows to a handful of companies while millions of people indirectly contribute to the ecosystem every day. OpenLedger seems to be asking whether there's a better way to track contributions and distribute rewards. And honestly... that's not a crazy question.
What I keep going back and forth on is whether this is one of those ideas that sounds great in theory but becomes incredibly messy in practice.
Because when people say "reward contributors fairly," my first thought is always... okay, but how? How do you actually measure contribution? How do you know what data was valuable and what wasn't? How do you prevent people from gaming the system? Those questions feel much harder than the marketing slogans.
At the same time, maybe that's exactly why the project exists.
Crypto has always been obsessed with ownership. AI is becoming obsessed with data. OpenLedger sits right in the middle of those two trends, which makes it feel more interesting than projects that are simply throwing AI buzzwords into a blockchain pitch deck.
The bullish case is pretty easy to understand. If AI keeps growing at the pace we've seen over the last few years, then questions around attribution, ownership, incentives, and data monetization are probably going to become more important, not less. If OpenLedger manages to build real infrastructure around those problems, I can see why people are excited.
But then the skeptical side of my brain kicks in...
I've been around crypto long enough to know that having a good idea is only about 10% of the battle. The other 90% is getting real people to actually use it. That's where countless projects have failed. Not because the technology was bad. Not because the vision was wrong. Simply because adoption never arrived.
That's probably where I am with OpenLedger right now. Interested, but cautious.
I don't get the feeling that it's a pure cash-grab project. It seems like there's genuine thought behind what they're are trying to build. But crypto is full of projects that looked smart on paper. The market doesn't reward good intentions. It rewards execution.
Maybe the biggest reason I'm watching OpenLedger is because it feels connected to a real trend rather than a temporary narrative. AI isn't going away. Questions about who owns data and who gets rewarded for contributing to AI systems aren't going away either. Those are legitimate issues.
Whether OpenLedger becomes part of the solution... that's the part nobody knows yet.
For now, it sits in that category of projects that make me curious enough to keep reading. Not because I'm convinced it's going to dominate the space, but because I can actually see the problem it's trying to solve. In crypto, that's surprisingly rare.
A lot of projects promise the future.
OpenLedger feels more like it's making a bet on where the future is heading and hoping it gets there before everyone else.
Maybe that's brilliant.
Maybe it's too early.
Maybe it's both.
@Openledger #OpenLedger $OPEN
OpenLedger (OPEN) Feels Like One of Those Projects I Can't Easily Dismiss
I've been going down a rabbit hole on OpenLedger and honestly... I'm still not completely sure what to think, which is usually a sign that a project is at least making me think instead of just selling me hype.
Most AI crypto projects lose me pretty fast. After reading enough of them, everything starts sounding the same. Decentralized AI, autonomous agents, revolutionary infrastructure, changing the future... you know the drill. But with OpenLedger, I found myself spending more time trying to understand the actual problem they're aiming at rather than immediately rolling my eyes and moving on.
The thing that caught my attention is this idea that data has value, but the people creating or contributing that data rarely capture any of it. If AI becomes one of the biggest industries in the world, then it feels weird that the value mostly flows to a handful of companies while millions of people indirectly contribute to the ecosystem every day. OpenLedger seems to be asking whether there's a better way to track contributions and distribute rewards. And honestly... that's not a crazy question.
What I keep going back and forth on is whether this is one of those ideas that sounds great in theory but becomes incredibly messy in practice.
Because when people say "reward contributors fairly," my first thought is always... okay, but how? How do you actually measure contribution? How do you know what data was valuable and what wasn't? How do you prevent people from gaming the system? Those questions feel much harder than the marketing slogans.
At the same time, maybe that's exactly why the project exists.
Crypto has always been obsessed with ownership. AI is becoming obsessed with data. OpenLedger sits right in the middle of those two trends, which makes it feel more interesting than projects that are simply throwing AI buzzwords into a blockchain pitch deck.
The bullish case is pretty easy to understand. If AI keeps growing at the pace we've seen over the last few years, then questions around attribution, ownership, incentives, and data monetization are probably going to become more important, not less. If OpenLedger manages to build real infrastructure around those problems, I can see why people are excited.
But then the skeptical side of my brain kicks in...
I've been around crypto long enough to know that having a good idea is only about 10% of the battle. The other 90% is getting real people to actually use it. That's where countless projects have failed. Not because the technology was bad. Not because the vision was wrong. Simply because adoption never arrived.
That's probably where I am with OpenLedger right now. Interested, but cautious.
I don't get the feeling that it's a pure cash-grab project. It seems like there's genuine thought behind what they're are trying to build. But crypto is full of projects that looked smart on paper. The market doesn't reward good intentions. It rewards execution.
Maybe the biggest reason I'm watching OpenLedger is because it feels connected to a real trend rather than a temporary narrative. AI isn't going away. Questions about who owns data and who gets rewarded for contributing to AI systems aren't going away either. Those are legitimate issues.
Whether OpenLedger becomes part of the solution... that's the part nobody knows yet.
For now, it sits in that category of projects that make me curious enough to keep reading. Not because I'm convinced it's going to dominate the space, but because I can actually see the problem it's trying to solve. In crypto, that's surprisingly rare.
A lot of projects promise the future.
OpenLedger feels more like it's making a bet on where the future is heading and hoping it gets there before everyone else.
Maybe that's brilliant.
Maybe it's too early.
Maybe it's both.
@OpenLedger #OpenLedger $OPEN
1
1
118
·
--
Why $OPEN Makes Me Think About the Real Problem Behind AI ValueI keep thinking that the biggest issue in AI is not only model quality anymore. Bigger models are coming, faster inference is coming, better reasoning is coming, and every month there is another benchmark that makes people excited for a few days. But behind all of that, one question still feels very unfinished to me: who actually created the value that AI is now monetizing?
That is the question that makes OpenLedger interesting.
Most AI systems today are built on a huge invisible layer of human contribution. People write, code, label, correct, review, search, upload, translate, explain, and interact online every day. That information becomes training material, feedback, and signal. Then models improve, platforms grow, and businesses capture value from the intelligence created on top of it. But the people who helped shape that intelligence usually disappear from the reward loop.
OpenLedger is trying to change that with a different idea: AI should not just use data; it should remember where the data came from and reward the people behind it. Binance Research describes OpenLedger’s Proof of Attribution as an on-chain attribution system that identifies how data influences model outputs and compensates contributors in $OPEN. It also highlights Datanets, Model Factory, and OpenLoRA as core parts of the ecosystem for building specialized AI models around community-owned data.
Why I Think Data Contribution Is Becoming the Real AI Story
A lot of AI projects still focus on compute, agents, or model performance. Those are important, but they are not the full story. AI does not become powerful in isolation. It needs useful data, clean context, and continuous improvement from real people and real communities.
That is why Datanets stand out to me. OpenLedger’s documentation explains the project as AI-blockchain infrastructure for training and deploying specialized models using community-owned datasets, where actions like dataset uploads, model training, reward credits, and governance participation happen on-chain.
This matters because the future of AI may not only belong to one massive general model. I think it will also need specialized models built around focused, high-quality data. Healthcare needs different intelligence than finance. Trading needs different intelligence than education. Cybersecurity needs different data than gaming. If the data is specific, traceable, and useful, then the model built on top of it can become much stronger.
That is where $OPEN starts to feel like more than just another AI token. It is sitting near the idea that data itself can become a productive digital asset.
Proof of Attribution Sounds Simple, But the Hard Part Is Trust
The strongest part of OpenLedger’s thesis is Proof of Attribution. In simple words, if a model gives an output and that output was shaped by certain data, the system should be able to trace that influence and reward the contributor.
On paper, I love that idea.
But I also think this is where people need to be honest. AI attribution is not easy. A model does not create output from one clean source. Many datasets, training steps, fine-tuning layers, prompts, model versions, and feedback loops can all influence the final result. That means attribution will always be one of the hardest parts of the AI economy.
And honestly, that is not a weakness only for OpenLedger. That is a weakness for the whole AI industry.
The difference is that OpenLedger is at least trying to build around it openly. Its Proof of Attribution paper says the system is designed to unlock liquidity across data, models, and intelligent agents by enabling transparent and verifiable attribution of data influence in model inference.
For me, the important thing is not pretending attribution will be perfect from day one. The important thing is whether it becomes good enough, transparent enough, and fair enough for contributors to trust it.
Why Estimated Attribution Still Matters
One thing I keep coming back to is this: attribution inside AI will probably never feel as simple as checking a wallet balance. It will involve estimation, influence measurement, and probability because model behavior is complex. That may sound uncomfortable, but it is also realistic.
Nobody can perfectly measure how one paragraph, one dataset, or one labeled example changed a model forever. But if OpenLedger can create a system where contribution influence becomes visible, auditable, and tied to rewards, that still moves the AI economy forward.
For contributors, the question becomes very practical. Not “is this mathematically perfect?” but “can I see how my data is being used, can I understand why I am being rewarded, and can I trust the system more than the current black box?”
Right now, most AI contributors get no visibility at all. So even a transparent and improving attribution layer could be a big step.
Model Factory and the Builder Side of $OPEN
Another part I like is Model Factory. A lot of people have ideas for AI tools, but they do not have the compute, infrastructure, or technical team to train and fine-tune models properly. OpenLedger’s Model Factory and OpenLoRA are designed to support training, fine-tuning, and hosting models, with LoRA adapters verified on-chain.
That is important because AI should not only belong to big labs. If smaller builders can use better data, tune models more easily, and connect their work to an attribution and reward layer, then innovation becomes more open.
Of course, easier model creation also brings new risks. More builders means more output, but not all output will be high quality. More contributors means more data, but not all data will be useful. Once rewards are involved, some people will try to game the system. So OpenLedger still needs strong validation, governance, and quality control.
That is why I see $OPEN as both exciting and difficult. The idea is strong, but the execution has to survive real human behavior.
The Role of this Inside the System
The token is not only meant to be a market asset. According to the OpenLedger Foundation tokenomics page, it powers three core processes: gas for the OpenLedger AI blockchain, fees for running inference and building AI models, and rewards for data contributors through Proof of Attribution.
That gives $OPEN a more direct role inside the ecosystem. If models are built, inference is used, contributors are rewarded, and Datanets grow, the token is supposed to sit inside that activity.
But this only becomes meaningful if real usage grows. A token can have a beautiful design, but without real builders, real datasets, real inference demand, and real contributor rewards, it stays mostly narrative. That is the test I am watching.
My Honest View on OpenLedger
I do not think OpenLedger is an easy project to judge. It is not building a simple DeFi product where you can quickly check TVL and fees and decide. It is trying to build an economic layer for AI contribution, and that is much harder.
The upside is clear. If AI keeps growing, then questions around data ownership, attribution, provenance, and payment will become more important. Businesses may need audit trails. Contributors may demand credit. Builders may want cleaner data markets. Users may ask where model outputs came from.
The challenge is also clear. Attribution has to be accurate enough to matter. Developers have to actually build. Contributors have to provide useful data. Rewards have to stay fair. And the ecosystem has to avoid becoming just another farming loop where people optimize for rewards instead of quality.
That is why I keep watching both interest and caution.
OpenLedger is not just asking how to build smarter AI. It is asking how AI value should move after it is created. That question feels much bigger than a normal token narrative.
If AI is becoming one of the most important economic layers of the future, then the credit system behind AI cannot stay broken forever. Someone has to build the rails for data ownership, contribution tracking, and fairer value distribution.
Maybe OpenLedger becomes one of those rails. Maybe it remains an early experiment. I cannot say that with certainty yet.
But the problem it is trying to solve is real.
And that is why @Openledger feels worth paying attention to.
#OpenLedger
Why $OPEN Makes Me Think About the Real Problem Behind AI Value
I keep thinking that the biggest issue in AI is not only model quality anymore. Bigger models are coming, faster inference is coming, better reasoning is coming, and every month there is another benchmark that makes people excited for a few days. But behind all of that, one question still feels very unfinished to me: who actually created the value that AI is now monetizing?
That is the question that makes OpenLedger interesting.
Most AI systems today are built on a huge invisible layer of human contribution. People write, code, label, correct, review, search, upload, translate, explain, and interact online every day. That information becomes training material, feedback, and signal. Then models improve, platforms grow, and businesses capture value from the intelligence created on top of it. But the people who helped shape that intelligence usually disappear from the reward loop.
OpenLedger is trying to change that with a different idea: AI should not just use data; it should remember where the data came from and reward the people behind it. Binance Research describes OpenLedger’s Proof of Attribution as an on-chain attribution system that identifies how data influences model outputs and compensates contributors in $OPEN . It also highlights Datanets, Model Factory, and OpenLoRA as core parts of the ecosystem for building specialized AI models around community-owned data.
Why I Think Data Contribution Is Becoming the Real AI Story
A lot of AI projects still focus on compute, agents, or model performance. Those are important, but they are not the full story. AI does not become powerful in isolation. It needs useful data, clean context, and continuous improvement from real people and real communities.
That is why Datanets stand out to me. OpenLedger’s documentation explains the project as AI-blockchain infrastructure for training and deploying specialized models using community-owned datasets, where actions like dataset uploads, model training, reward credits, and governance participation happen on-chain.
This matters because the future of AI may not only belong to one massive general model. I think it will also need specialized models built around focused, high-quality data. Healthcare needs different intelligence than finance. Trading needs different intelligence than education. Cybersecurity needs different data than gaming. If the data is specific, traceable, and useful, then the model built on top of it can become much stronger.
That is where $OPEN starts to feel like more than just another AI token. It is sitting near the idea that data itself can become a productive digital asset.
Proof of Attribution Sounds Simple, But the Hard Part Is Trust
The strongest part of OpenLedger’s thesis is Proof of Attribution. In simple words, if a model gives an output and that output was shaped by certain data, the system should be able to trace that influence and reward the contributor.
On paper, I love that idea.
But I also think this is where people need to be honest. AI attribution is not easy. A model does not create output from one clean source. Many datasets, training steps, fine-tuning layers, prompts, model versions, and feedback loops can all influence the final result. That means attribution will always be one of the hardest parts of the AI economy.
And honestly, that is not a weakness only for OpenLedger. That is a weakness for the whole AI industry.
The difference is that OpenLedger is at least trying to build around it openly. Its Proof of Attribution paper says the system is designed to unlock liquidity across data, models, and intelligent agents by enabling transparent and verifiable attribution of data influence in model inference.
For me, the important thing is not pretending attribution will be perfect from day one. The important thing is whether it becomes good enough, transparent enough, and fair enough for contributors to trust it.
Why Estimated Attribution Still Matters
One thing I keep coming back to is this: attribution inside AI will probably never feel as simple as checking a wallet balance. It will involve estimation, influence measurement, and probability because model behavior is complex. That may sound uncomfortable, but it is also realistic.
Nobody can perfectly measure how one paragraph, one dataset, or one labeled example changed a model forever. But if OpenLedger can create a system where contribution influence becomes visible, auditable, and tied to rewards, that still moves the AI economy forward.
For contributors, the question becomes very practical. Not “is this mathematically perfect?” but “can I see how my data is being used, can I understand why I am being rewarded, and can I trust the system more than the current black box?”
Right now, most AI contributors get no visibility at all. So even a transparent and improving attribution layer could be a big step.
Model Factory and the Builder Side of $OPEN
Another part I like is Model Factory. A lot of people have ideas for AI tools, but they do not have the compute, infrastructure, or technical team to train and fine-tune models properly. OpenLedger’s Model Factory and OpenLoRA are designed to support training, fine-tuning, and hosting models, with LoRA adapters verified on-chain.
That is important because AI should not only belong to big labs. If smaller builders can use better data, tune models more easily, and connect their work to an attribution and reward layer, then innovation becomes more open.
Of course, easier model creation also brings new risks. More builders means more output, but not all output will be high quality. More contributors means more data, but not all data will be useful. Once rewards are involved, some people will try to game the system. So OpenLedger still needs strong validation, governance, and quality control.
That is why I see $OPEN as both exciting and difficult. The idea is strong, but the execution has to survive real human behavior.
The Role of this Inside the System
The token is not only meant to be a market asset. According to the OpenLedger Foundation tokenomics page, it powers three core processes: gas for the OpenLedger AI blockchain, fees for running inference and building AI models, and rewards for data contributors through Proof of Attribution.
That gives $OPEN a more direct role inside the ecosystem. If models are built, inference is used, contributors are rewarded, and Datanets grow, the token is supposed to sit inside that activity.
But this only becomes meaningful if real usage grows. A token can have a beautiful design, but without real builders, real datasets, real inference demand, and real contributor rewards, it stays mostly narrative. That is the test I am watching.
My Honest View on OpenLedger
I do not think OpenLedger is an easy project to judge. It is not building a simple DeFi product where you can quickly check TVL and fees and decide. It is trying to build an economic layer for AI contribution, and that is much harder.
The upside is clear. If AI keeps growing, then questions around data ownership, attribution, provenance, and payment will become more important. Businesses may need audit trails. Contributors may demand credit. Builders may want cleaner data markets. Users may ask where model outputs came from.
The challenge is also clear. Attribution has to be accurate enough to matter. Developers have to actually build. Contributors have to provide useful data. Rewards have to stay fair. And the ecosystem has to avoid becoming just another farming loop where people optimize for rewards instead of quality.
That is why I keep watching both interest and caution.
OpenLedger is not just asking how to build smarter AI. It is asking how AI value should move after it is created. That question feels much bigger than a normal token narrative.
If AI is becoming one of the most important economic layers of the future, then the credit system behind AI cannot stay broken forever. Someone has to build the rails for data ownership, contribution tracking, and fairer value distribution.
Maybe OpenLedger becomes one of those rails. Maybe it remains an early experiment. I cannot say that with certainty yet.
But the problem it is trying to solve is real.
And that is why @OpenLedger feels worth paying attention to.
#OpenLedger
1
237
·
--
#openledger $OPEN Yang paling menarik dari OpenLedger adalah fokusnya pada AI yang bisa dipertanggungjawabkan. Bukan cuma soal model yang pintar, tetapi juga soal siapa yang memberi data, bagaimana data itu dipakai, dan bagaimana kontribusinya dihargai. Dengan pendekatan Proof of Attribution dan Datanets, OpenLedger mencoba membangun ekosistem AI yang lebih transparan, terbuka, dan punya nilai ekonomi untuk para kontributor. Di tengah perkembangan AI dan Web3 yang semakin cepat, ide seperti ini terasa relevan karena memberi ruang bagi komunitas untuk ikut membangun, bukan hanya menjadi pengguna. @Openledger OpenLedger $OPEN #OpenLedge r
#openledger $OPEN Yang paling menarik dari OpenLedger adalah fokusnya pada AI yang bisa dipertanggungjawabkan. Bukan cuma soal model yang pintar, tetapi juga soal siapa yang memberi data, bagaimana data itu dipakai, dan bagaimana kontribusinya dihargai. Dengan pendekatan Proof of Attribution dan Datanets, OpenLedger mencoba membangun ekosistem AI yang lebih transparan, terbuka, dan punya nilai ekonomi untuk para kontributor. Di tengah perkembangan AI dan Web3 yang semakin cepat, ide seperti ini terasa relevan karena memberi ruang bagi komunitas untuk ikut membangun, bukan hanya menjadi pengguna. @OpenLedger OpenLedger $OPEN #OpenLedge r
141
·
--
Статья
从碎片数据到数字底座:深度复盘 OpenLedger 走向 Web3 核心基建的进化逻辑我一边用平底锅煎着鸡蛋,一边用挂在后台的某个大热 AI 聚合器筛选当天的潜在异动币种。本来盯着 $BTC 刚刚企稳的 K 线,觉得可以摸点小鱼。突然,那个号称“全网毫秒级抓取”的 AI 弹窗疯狂预警,说某天王级项目团队正在砸盘转移资产。我吓得连火都顾不上关,切到 $ETH 链上,顶着几百 Gwei 的极高 Gas 费,狼狈地把相关池子里的 LP 全撤了。结果过了一小时才发现,这智障 AI 只是爬取了一个高仿诈骗号在推特上发的钓鱼假图,并把它当成了链上确凿证据。看着锅里焦黑的鸡蛋和凭空蒸发的高昂手续费,我后背一阵发凉:当咱们越来越依赖人工智能去做交易或生活决策时,一旦喂给它的源头数据掺了屎,它挥向我们的绝对是一把能要命的镰刀。
这口昂贵的“毒奶”,直接把我从各种炫酷的“Web3+AI”迷梦里扇醒了。你看看现在的广场,全在炒作谁家的虚拟人更逼真、哪个智能体更会聊天。但极少有人愿意捏着鼻子去查一查,这些看似聪明绝顶的代码模型,每天到底在吃什么烂菜叶子。逻辑很简单:如果大模型底层的训练语料早被污染了,甚至是被黑客恶意投毒的,那你就算用最顶级的算法,跑出来的也是一个一本正经胡说八道的数字废物。顺着这条顺藤摸瓜的思路,我才把投研的准星锁死了 @Openledger 。当全行业都在搞花里胡哨的前端应用骗流量时,这帮人却一头扎进了最苦最累的数据底层泥潭,试图用密码学和去中心化的方式,给语料打上一套无法作弊的“验毒防伪”标签。
把这套逻辑掰开揉碎了看,其实跟咱们加密行业最古早的信仰演进如出一辙。当年中本聪甩出比特币白皮书,靠着绝妙的算力博弈和公开账本,干碎了传统金融系统的黑箱,解决了电子资产的“双花”难题;紧接着,以太坊带着智能合约粉墨登场,用 EVM 把这种去信任化的共识,直接拉高到了执行复杂代码的层级。但现实很骨感,这两位开山鼻祖要是遇上如今 AI 模型那种动辄几百 TB 的恐怖数据吞吐量,绝对会被瞬间卡成高位截瘫。大模型要吃的不仅是几行转账记录,更是海量的人工标注、图像清洗和逻辑校对。
这种如同星辰大海般的非结构化数据洪流,如果全往现有的公链里塞,光是存储成本就能让项目方分分钟破产。这就注定了一个事实:AI 赛道必须长出一条像 OpenLedger 这样的专属数据下水道和提纯厂。它通过散布在全球的分布式节点,把那些脏乱差的原始信息收集过来,用一套严密的共识机制进行人工或算法的交叉筛查,最后提炼成高价值的机器口粮。如果没有这道干着苦力活的去中心化中间层,以后任何想在链上搞原生 AI 的极客,光是买数据和洗数据的天价账单,就足以把他们提前送走。
前几天,我和一个在硅谷大厂做算法核心的哥们儿喝酒,他嗤笑我们搞去中心化 AI 是螳臂当车,觉得大厂靠着堆积如山的 H100 显卡和垄断的全网爬虫,早就通关了这场游戏。我端着酒杯直接怼了回去:他们太傲慢了,完全低估了普通人“数据主权觉醒”的核爆威力。现在互联网上能免费白嫖的公开语料早就干涸了,甚至被 AI 自己生成的垃圾反噬了。未来真正能让模型产生质变的,是咱们每个人手机里、电脑里那些带着鲜活个人印记的私域数据。巨头要是敢明抢,绝对会被隐私法案和舆论彻底撕碎。而在这片灰色地带,去中心化网络反而成了一个绝佳的避风港。它让咱们普通人可以在不交出隐私底裤的前提下,把自己的认知和行为数据明码标价,卖个好价钱。
当然,作为常年拿真金白银试错的实盘玩家,我平时用那些“链上 AI”工具时,最想骂娘的就是那令人发指的延迟。哪怕让智能体做个简单的推演,都要去链上排队打包,这种反人类的 UX 简直比以太坊链上大拥堵还折磨人。所以我一直在拿着放大镜审视 #OpenLedger 到底怎么平衡“性能”和“去中心化”。让我觉得这项目靠谱的一点是,他们没蠢到把消耗算力的模型训练直接搬上链去硬跑。相反,他们极其克制地把核心精力与 $OPEN 代币经济学,死死钉在了“数据溯源确权”和“贡献者利润清算”这两层。这种向物理极限妥协的务实态度,说明团队在真正干活,而不是给资本讲科幻故事。
不过,我也绝不会天真到认为这条路已经稳赢了,它在经济模型上要趟的雷区依然密布。在这个击鼓传花的圈子里,原生代币的估值到底怎么和现实中那些传统企业采购数据的真金白银挂钩,依然是个极其棘手的死结。如果币价在二级市场被炒得像过山车一样上蹿下跳,那些拿着正规预算的外部 AI 实体企业,绝对不敢来这儿采购语料;可反过来,如果早期没有足够性感的暴富预期,那些自带设备来跑节点的矿工大军,凭什么义务劳动帮你搭底层基建?这简直是在走钢丝,极其考验官方团队像精密微调仪一样,根据真实的数据吞吐量和买卖双方的情绪,去动态平衡整个经济飞轮。
归根结底,AI 和区块链的这场世纪大碰撞,其核心诉求根本不是去造一个无所不能的赛博神明,而是一场关于数字时代“资料治理权”和“财富分配权”的生死争夺。我们已经受够了那些科技寡头把咱们当成免费语料提款机的黑盒时代。每次想起那个因为被 AI 误导让我亏掉巨额 Gas 费的早晨,我就越发笃定:破局的底牌不是去盲目崇拜更聪明的算法,而是从源头掐死数据污染,保证我交付和读取的每一个字节,都带有绝对干净且不可篡改的所有权烙印。这条去中心化确权的路注定布满荆棘和各种难看的 Bug,但它实打实地给了咱们普通人在 AI 纪元里护住自己数据底线的终极武器。
接下来我会死盯这两点。第一点是,它在主网面临极其复杂的高并发冲击时,那套反女巫和验真机制到底能不能扛住脚本工作室的饱和式投毒,如果源头防线被攻破,这网络就会沦为毫无价值的垃圾填埋场。第二点是,未来半年内,官方到底能不能拉来真正有体量的 Web2 科技企业或者传统资本进场,用真实的法币预算来采购这套去中心化语料。因为只有切实的外部买单输血,这套靠代币支撑的数据确权宏大叙事,才算真正从乌托邦照进现实。#OpenLedger
从碎片数据到数字底座:深度复盘 OpenLedger 走向 Web3 核心基建的进化逻辑
我一边用平底锅煎着鸡蛋,一边用挂在后台的某个大热 AI 聚合器筛选当天的潜在异动币种。本来盯着 $BTC 刚刚企稳的 K 线,觉得可以摸点小鱼。突然,那个号称“全网毫秒级抓取”的 AI 弹窗疯狂预警,说某天王级项目团队正在砸盘转移资产。我吓得连火都顾不上关,切到 $ETH 链上,顶着几百 Gwei 的极高 Gas 费,狼狈地把相关池子里的 LP 全撤了。结果过了一小时才发现,这智障 AI 只是爬取了一个高仿诈骗号在推特上发的钓鱼假图,并把它当成了链上确凿证据。看着锅里焦黑的鸡蛋和凭空蒸发的高昂手续费,我后背一阵发凉:当咱们越来越依赖人工智能去做交易或生活决策时,一旦喂给它的源头数据掺了屎,它挥向我们的绝对是一把能要命的镰刀。
这口昂贵的“毒奶”,直接把我从各种炫酷的“Web3+AI”迷梦里扇醒了。你看看现在的广场,全在炒作谁家的虚拟人更逼真、哪个智能体更会聊天。但极少有人愿意捏着鼻子去查一查,这些看似聪明绝顶的代码模型,每天到底在吃什么烂菜叶子。逻辑很简单:如果大模型底层的训练语料早被污染了,甚至是被黑客恶意投毒的,那你就算用最顶级的算法,跑出来的也是一个一本正经胡说八道的数字废物。顺着这条顺藤摸瓜的思路,我才把投研的准星锁死了 @OpenLedger 。当全行业都在搞花里胡哨的前端应用骗流量时,这帮人却一头扎进了最苦最累的数据底层泥潭,试图用密码学和去中心化的方式,给语料打上一套无法作弊的“验毒防伪”标签。
把这套逻辑掰开揉碎了看,其实跟咱们加密行业最古早的信仰演进如出一辙。当年中本聪甩出比特币白皮书,靠着绝妙的算力博弈和公开账本,干碎了传统金融系统的黑箱,解决了电子资产的“双花”难题;紧接着,以太坊带着智能合约粉墨登场,用 EVM 把这种去信任化的共识,直接拉高到了执行复杂代码的层级。但现实很骨感,这两位开山鼻祖要是遇上如今 AI 模型那种动辄几百 TB 的恐怖数据吞吐量,绝对会被瞬间卡成高位截瘫。大模型要吃的不仅是几行转账记录,更是海量的人工标注、图像清洗和逻辑校对。
这种如同星辰大海般的非结构化数据洪流,如果全往现有的公链里塞,光是存储成本就能让项目方分分钟破产。这就注定了一个事实:AI 赛道必须长出一条像 OpenLedger 这样的专属数据下水道和提纯厂。它通过散布在全球的分布式节点,把那些脏乱差的原始信息收集过来,用一套严密的共识机制进行人工或算法的交叉筛查,最后提炼成高价值的机器口粮。如果没有这道干着苦力活的去中心化中间层,以后任何想在链上搞原生 AI 的极客,光是买数据和洗数据的天价账单,就足以把他们提前送走。
前几天,我和一个在硅谷大厂做算法核心的哥们儿喝酒,他嗤笑我们搞去中心化 AI 是螳臂当车,觉得大厂靠着堆积如山的 H100 显卡和垄断的全网爬虫,早就通关了这场游戏。我端着酒杯直接怼了回去:他们太傲慢了,完全低估了普通人“数据主权觉醒”的核爆威力。现在互联网上能免费白嫖的公开语料早就干涸了,甚至被 AI 自己生成的垃圾反噬了。未来真正能让模型产生质变的,是咱们每个人手机里、电脑里那些带着鲜活个人印记的私域数据。巨头要是敢明抢,绝对会被隐私法案和舆论彻底撕碎。而在这片灰色地带,去中心化网络反而成了一个绝佳的避风港。它让咱们普通人可以在不交出隐私底裤的前提下,把自己的认知和行为数据明码标价,卖个好价钱。
当然,作为常年拿真金白银试错的实盘玩家,我平时用那些“链上 AI”工具时,最想骂娘的就是那令人发指的延迟。哪怕让智能体做个简单的推演,都要去链上排队打包,这种反人类的 UX 简直比以太坊链上大拥堵还折磨人。所以我一直在拿着放大镜审视 #OpenLedger 到底怎么平衡“性能”和“去中心化”。让我觉得这项目靠谱的一点是,他们没蠢到把消耗算力的模型训练直接搬上链去硬跑。相反,他们极其克制地把核心精力与 $OPEN 代币经济学,死死钉在了“数据溯源确权”和“贡献者利润清算”这两层。这种向物理极限妥协的务实态度,说明团队在真正干活,而不是给资本讲科幻故事。
不过,我也绝不会天真到认为这条路已经稳赢了,它在经济模型上要趟的雷区依然密布。在这个击鼓传花的圈子里,原生代币的估值到底怎么和现实中那些传统企业采购数据的真金白银挂钩,依然是个极其棘手的死结。如果币价在二级市场被炒得像过山车一样上蹿下跳,那些拿着正规预算的外部 AI 实体企业,绝对不敢来这儿采购语料;可反过来,如果早期没有足够性感的暴富预期,那些自带设备来跑节点的矿工大军,凭什么义务劳动帮你搭底层基建?这简直是在走钢丝,极其考验官方团队像精密微调仪一样,根据真实的数据吞吐量和买卖双方的情绪,去动态平衡整个经济飞轮。
归根结底,AI 和区块链的这场世纪大碰撞,其核心诉求根本不是去造一个无所不能的赛博神明,而是一场关于数字时代“资料治理权”和“财富分配权”的生死争夺。我们已经受够了那些科技寡头把咱们当成免费语料提款机的黑盒时代。每次想起那个因为被 AI 误导让我亏掉巨额 Gas 费的早晨,我就越发笃定:破局的底牌不是去盲目崇拜更聪明的算法,而是从源头掐死数据污染,保证我交付和读取的每一个字节,都带有绝对干净且不可篡改的所有权烙印。这条去中心化确权的路注定布满荆棘和各种难看的 Bug,但它实打实地给了咱们普通人在 AI 纪元里护住自己数据底线的终极武器。
接下来我会死盯这两点。第一点是,它在主网面临极其复杂的高并发冲击时,那套反女巫和验真机制到底能不能扛住脚本工作室的饱和式投毒,如果源头防线被攻破,这网络就会沦为毫无价值的垃圾填埋场。第二点是,未来半年内,官方到底能不能拉来真正有体量的 Web2 科技企业或者传统资本进场,用真实的法币预算来采购这套去中心化语料。因为只有切实的外部买单输血,这套靠代币支撑的数据确权宏大叙事,才算真正从乌托邦照进现实。#OpenLedger
627
Войдите, чтобы посмотреть больше материала
Присоединяйтесь к пользователям криптовалют по всему миру на Binance Square
⚡️ Получайте новейшую и полезную информацию о криптоактивах.
💬 Нам доверяет крупнейшая в мире криптобиржа.
👍 Получите достоверные аналитические данные от верифицированных создателей контента.
Эл. почта/номер телефона
В тренде
1
#UniswapA16zSeekDeFiExemptionFromIllinoisCryptoTax
Просмотров: 15,403
611 обсуждают
2
#HKDollarStablecoinHKDAPToLaunchOnSolana
Просмотров: 10,005
361 обсуждают
3
#$1.5BInLeveragedCryptoBetsLiquidated
Просмотров: 26,859
223 обсуждают
4
#TrezorSaysCryptoBilisSoldWalletMayContainMaliciousComponents
Просмотров: 1,662
52 обсуждают
5
#KOSPIFalls3.53%BackBelow6000
Просмотров: 52,836
1,009 обсуждают
6
#AmazonSharesFallAbout7%InPremarketTrading
Просмотров: 23,693
532 обсуждают
7
#USMidtermElections
Просмотров: 213,471
2,276 обсуждают
8
#StrategySTRCReaches$99.95ForFirstTimeIn165Days
Просмотров: 16,149
92 обсуждают
9
#BinanceWillListPredictPREDICT
Просмотров: 78,665
1,314 обсуждают
10
#SwitzerlandFirstSpotBitcoinETFExpectedToTradeInNovember
Просмотров: 2,697
104 обсуждают