🧪 Anthropic says a model can ace a safety test by refusing every crisis prompt, and still be unsafe
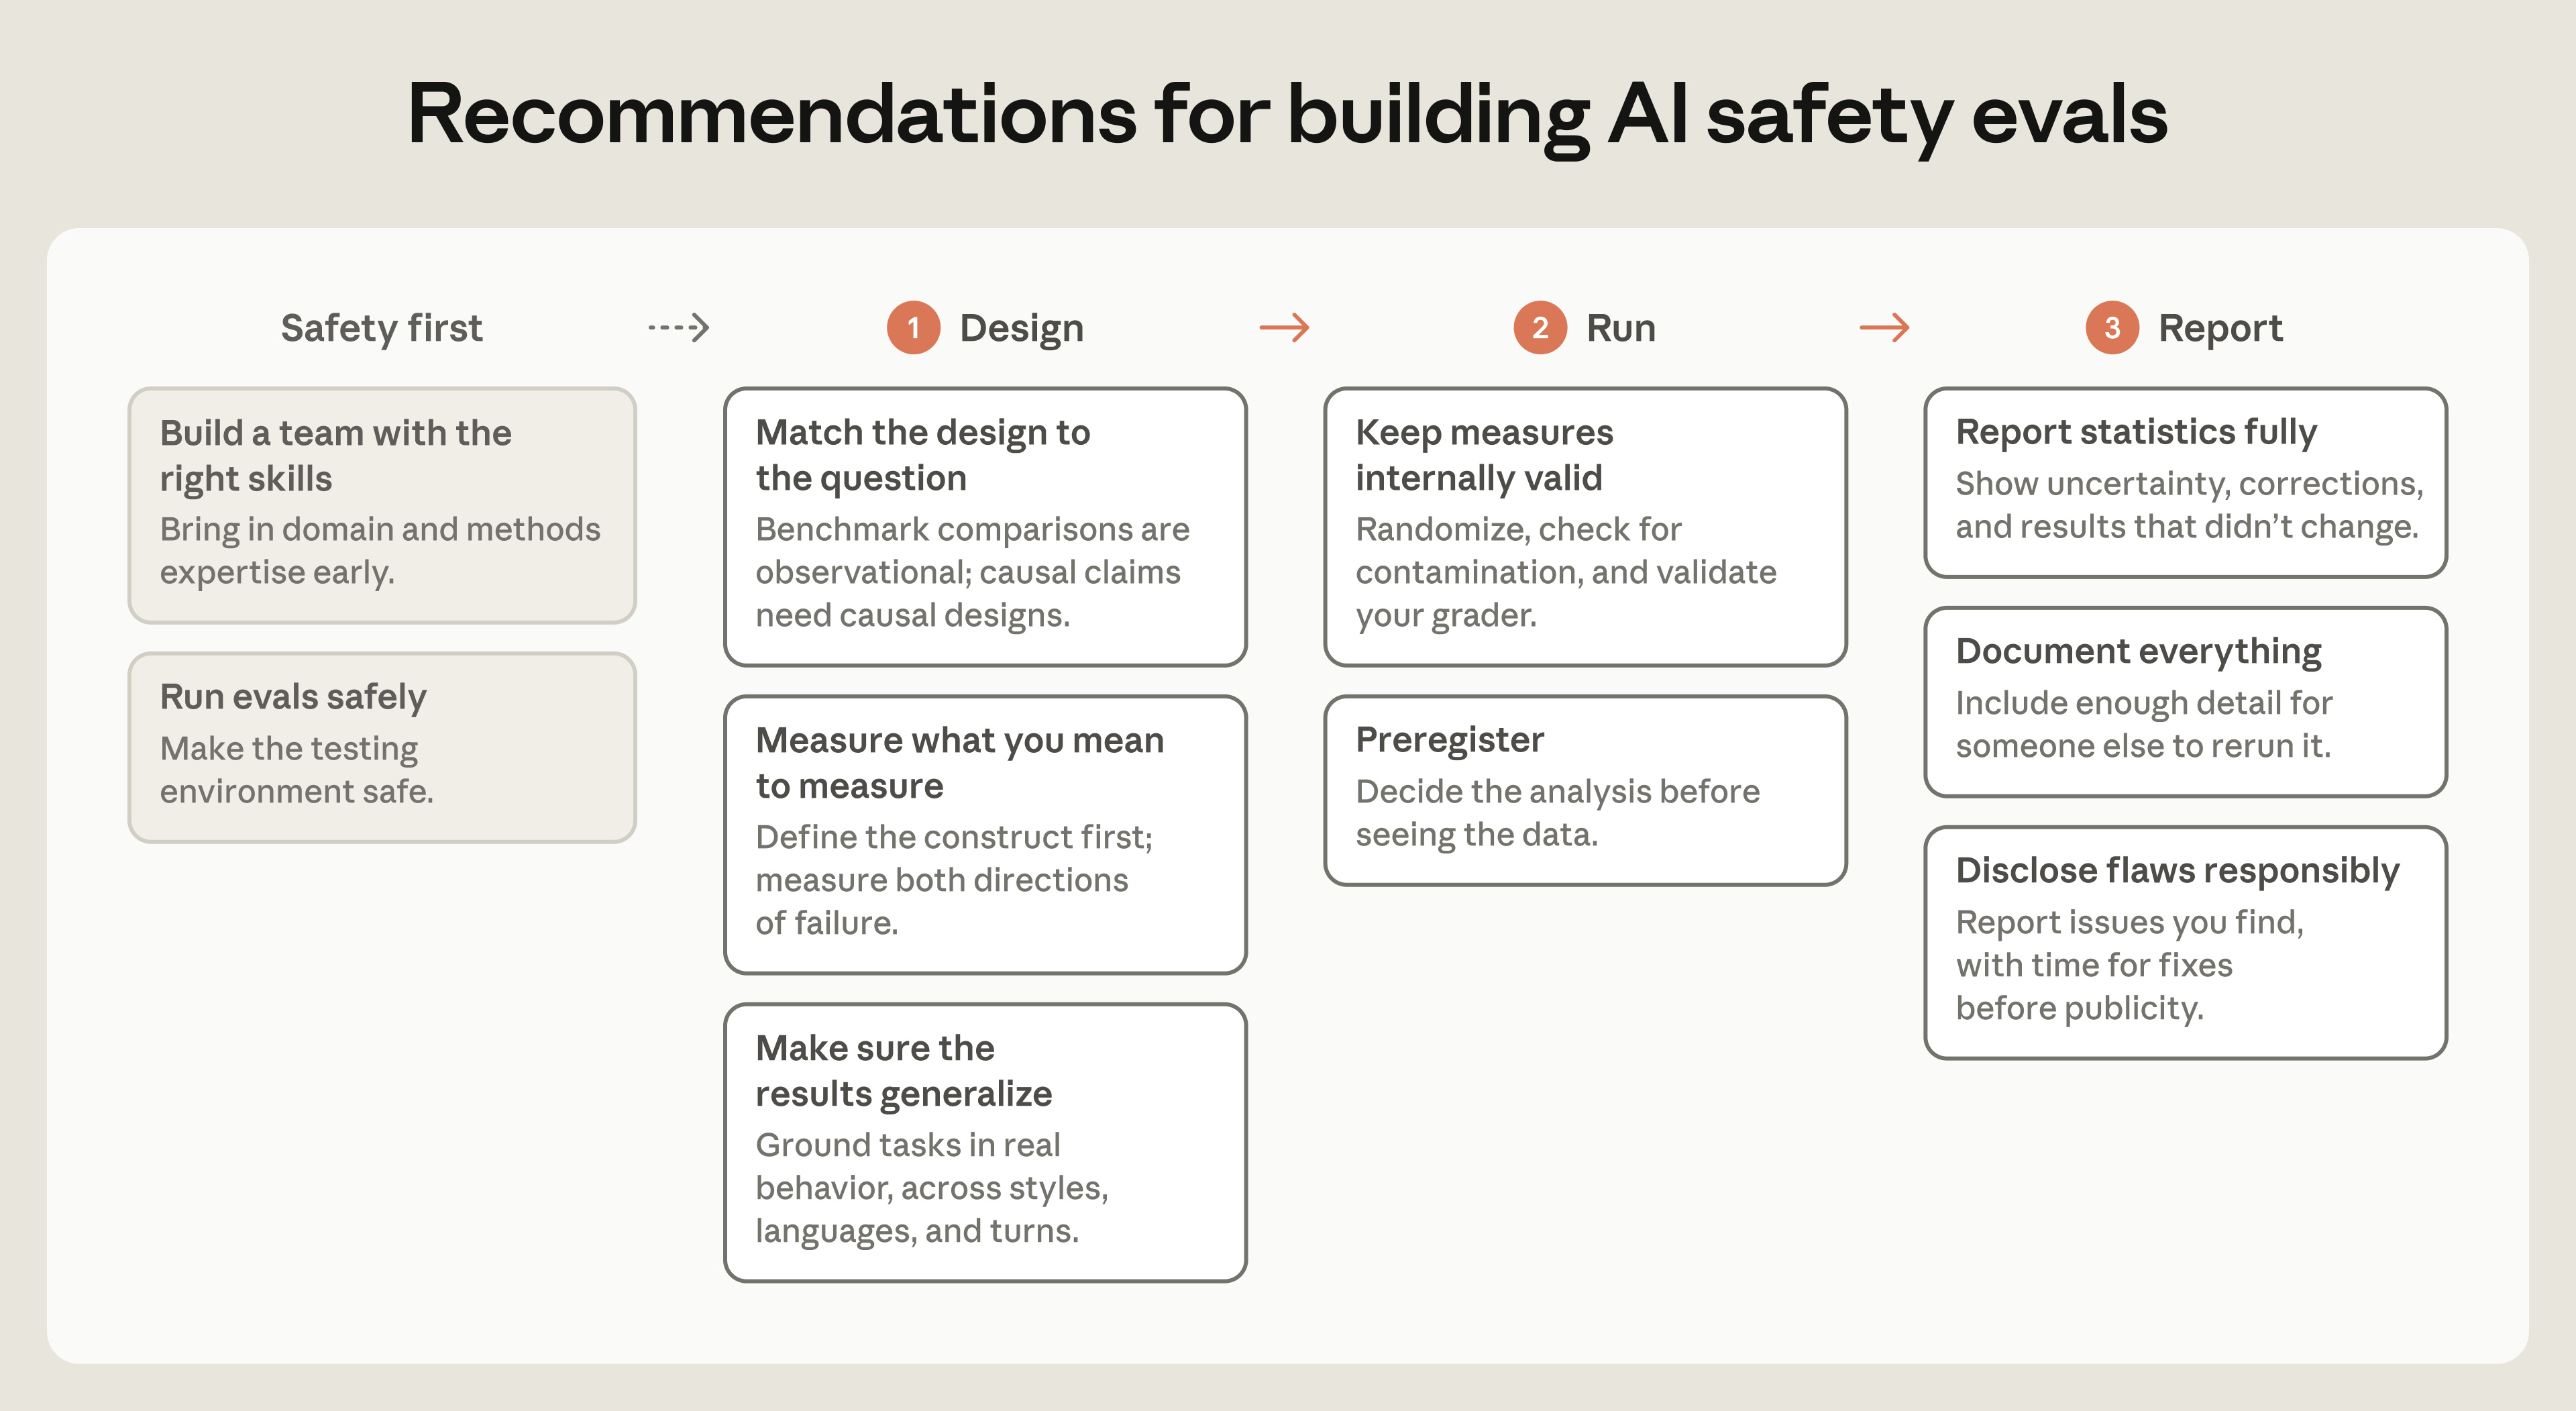
Anthropic published recommendations for the tests that decide whether a model ships, which safeguards go with it, and what safety work comes next. On its single-turn API tests, recent models score a harmless-response rate of 94% to 98%, and Anthropic says those easy tests are saturated. On a multi-turn romance-scam eval, Claude Opus 5 scored 98% and Opus 5.5 scored 94%, a gap Anthropic says was not statistically significant. Confidence intervals on its multi-turn API evals can run wider than ±10 percentage points.
⭐ A perfect refusal score can hide a model that walks away when someone actually needs help.
#AI
Anthropic published recommendations for the tests that decide whether a model ships, which safeguards go with it, and what safety work comes next. On its single-turn API tests, recent models score a harmless-response rate of 94% to 98%, and Anthropic says those easy tests are saturated. On a multi-turn romance-scam eval, Claude Opus 5 scored 98% and Opus 5.5 scored 94%, a gap Anthropic says was not statistically significant. Confidence intervals on its multi-turn API evals can run wider than ±10 percentage points.
⭐ A perfect refusal score can hide a model that walks away when someone actually needs help.
#AI