
1/2
I thought I had 1M context in Codex.
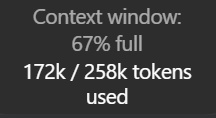
Then I noticed my Astra chat was showing 172k used out of 258k.
Astra's API specification does list 1.05M tokens, but Codex can use a smaller context window by default.
In my setup, the default was 272,000 tokens.
With the client's 95% usable-window factor, that explains the 258k shown in the app.
The maximum in my local model catalog was 872,000 tokens, which corresponds to about 828k usable.
Your setup can have a different limit, so it's worth having Codex check before changing it.
One tradeoff: keeping more history in the active context can use more of your allowance.
Raising the ceiling alone doesn't make every request consume the entire window.
For Codex signed in through ChatGPT, there's no separate long-context multiplier, but processing more tokens still counts.
Using your own API key follows API pricing.
If you want the largest window your setup supports, paste this into Codex:
---------------------------
I thought I had 1M context in Codex.
Then I noticed my Astra chat was showing 172k used out of 258k.
Astra's API specification does list 1.05M tokens, but Codex can use a smaller context window by default.
In my setup, the default was 272,000 tokens.
With the client's 95% usable-window factor, that explains the 258k shown in the app.
The maximum in my local model catalog was 872,000 tokens, which corresponds to about 828k usable.
Your setup can have a different limit, so it's worth having Codex check before changing it.
One tradeoff: keeping more history in the active context can use more of your allowance.
Raising the ceiling alone doesn't make every request consume the entire window.
For Codex signed in through ChatGPT, there's no separate long-context multiplier, but processing more tokens still counts.
Using your own API key follows API pricing.
If you want the largest window your setup supports, paste this into Codex:
---------------------------