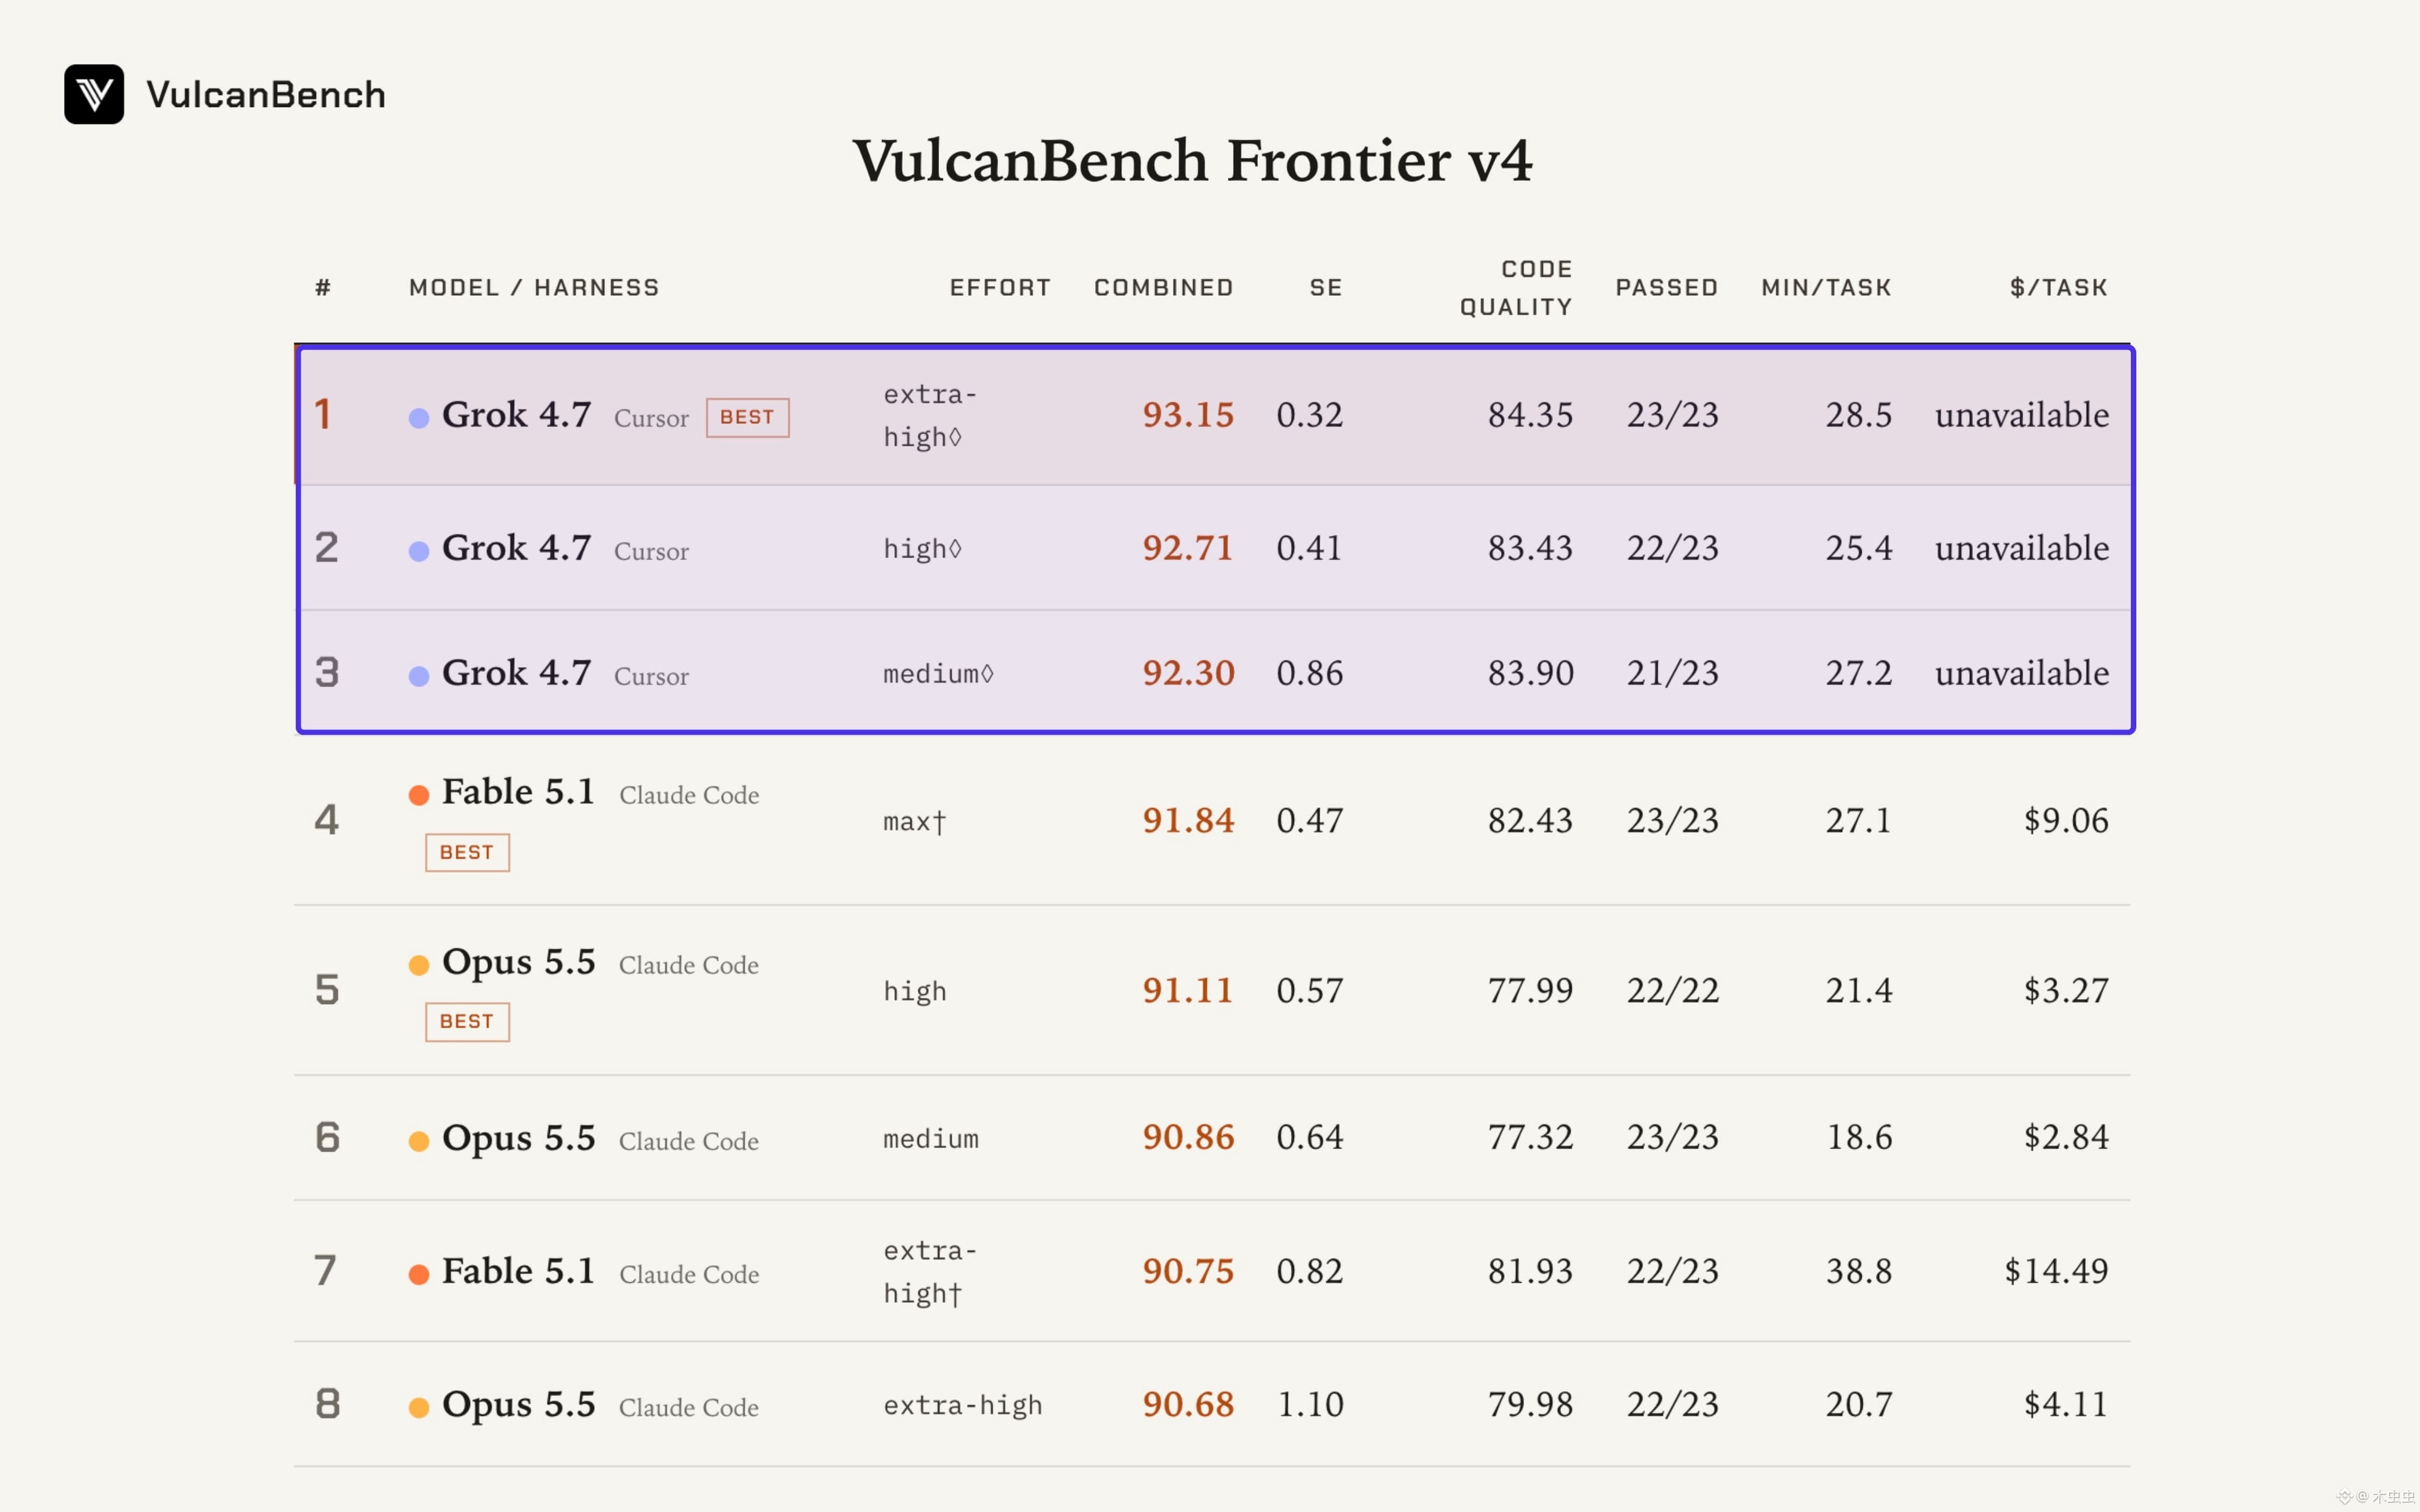
Grok 4.7 takes the TOP 3 spots on VulcanBench Frontier v4, outperforming Fable 5.1, Opus 5.5, GPT-6 Astra, GPT-6.1 Sol and other leading frontier models
• Grok 4.7 xHigh - 93.15
• Grok 4.7 High - 92.71
• Grok 4.7 Medium - 92.30
VulcanBench Frontier v4 tests whether AI models can handle difficult repository-level software engineering work rather than simply generate isolated code snippets
The benchmark contains 23 behavioural-reconstruction tasks where models have to rebuild legacy software to match its actual behaviour, with functional correctness tested through hidden tests alongside security, lint/complexity and code quality
And the task results are just as impressive:
• Grok 4.7 xHigh - 23/23 passed
• Grok 4.7 High - 22/23 passed
• Grok 4.7 Medium - 21/23 passed
Grok 4.7 took all #1, #2 and #3 spots