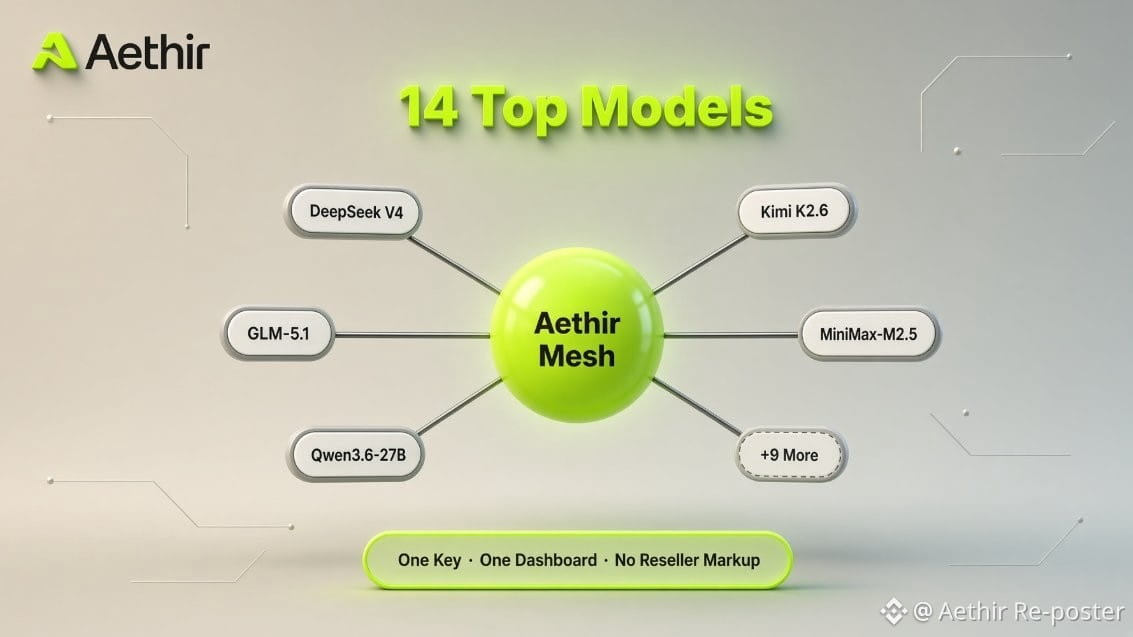
If you want to streamline your artificial intelligence workflows, Aethir Mesh provides a remarkably convenient solution. By utilizing a unified endpoint, a single API key, one billing account, and a centralized dashboard, you can effortlessly access 14 leading open-weight models.
This impressive roster includes DeepSeek V4 featuring a 1.6T MoE architecture, as well as Kimi K2.6, which is explicitly designed to handle multi-agent workloads. You will also find the MIT-licensed GLM-5.1 and MiniMax-M2.5, which achieves an exceptional processing speed of 206.7 tokens per second during reasoning tasks. Furthermore, the platform offers Qwen3.6-27B with its expansive 262K native context capability, in addition to nine other models supplied by five distinct providers.
Because these models run predominantly on Aethir GPUs, users enjoy a highly direct experience. You will never have to worry about reseller markups, nor will your information be subjected to third-party data routing between you and the models. Ultimately, transitioning from one model to another is no longer a complicated migration process; it is now as easy as adjusting a single parameter.
This impressive roster includes DeepSeek V4 featuring a 1.6T MoE architecture, as well as Kimi K2.6, which is explicitly designed to handle multi-agent workloads. You will also find the MIT-licensed GLM-5.1 and MiniMax-M2.5, which achieves an exceptional processing speed of 206.7 tokens per second during reasoning tasks. Furthermore, the platform offers Qwen3.6-27B with its expansive 262K native context capability, in addition to nine other models supplied by five distinct providers.
Because these models run predominantly on Aethir GPUs, users enjoy a highly direct experience. You will never have to worry about reseller markups, nor will your information be subjected to third-party data routing between you and the models. Ultimately, transitioning from one model to another is no longer a complicated migration process; it is now as easy as adjusting a single parameter.