There’s now a cost-saving tool for running Agents that burn through Tokens: headroom compresses logs, JSON, and files locally before they’re fed back into the model.
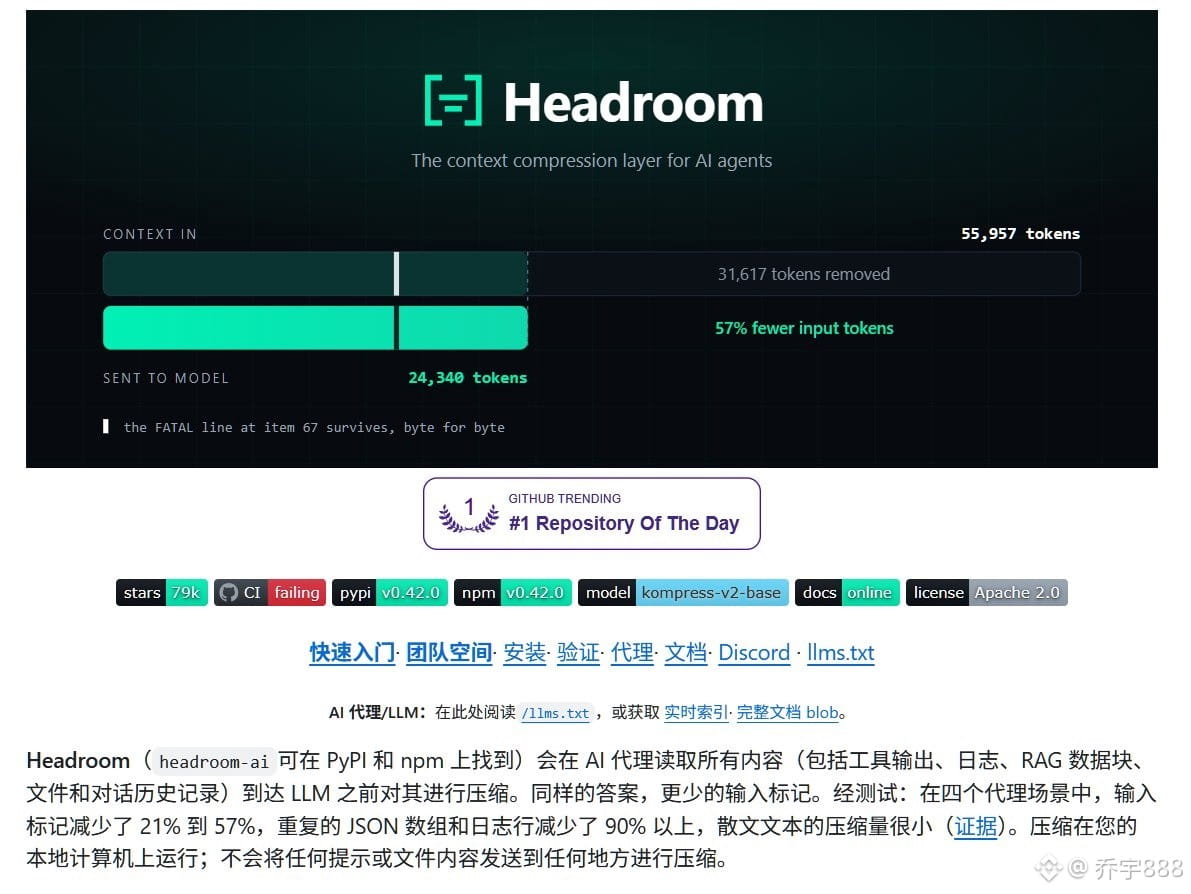
In the official tests, an SRE incident investigation went from 55,957 Tokens to 24,340—a 57% reduction. A 10,144-Token log was reduced to 1,260, with the critical FATAL lines preserved. Repeated JSON arrays and log lines can be cut by more than 90%, while plain text is barely compressed. Each pass takes less than 1 millisecond, nothing is sent outside your system, and GSM8K math scores were 0.870 both before and after compression.
My take: the biggest cost of running Agents isn’t how much the model thinks—it’s repeatedly reading the logs returned by tools. Compress them locally before they reach the model, and you can cut the bill in half before tackling anything else. I suspect the savings depend on what your own Agent produces; those with lots of logs will benefit first.
#AIFrontier
$BTC
In the official tests, an SRE incident investigation went from 55,957 Tokens to 24,340—a 57% reduction. A 10,144-Token log was reduced to 1,260, with the critical FATAL lines preserved. Repeated JSON arrays and log lines can be cut by more than 90%, while plain text is barely compressed. Each pass takes less than 1 millisecond, nothing is sent outside your system, and GSM8K math scores were 0.870 both before and after compression.
My take: the biggest cost of running Agents isn’t how much the model thinks—it’s repeatedly reading the logs returned by tools. Compress them locally before they reach the model, and you can cut the bill in half before tackling anything else. I suspect the savings depend on what your own Agent produces; those with lots of logs will benefit first.
#AIFrontier
$BTC