

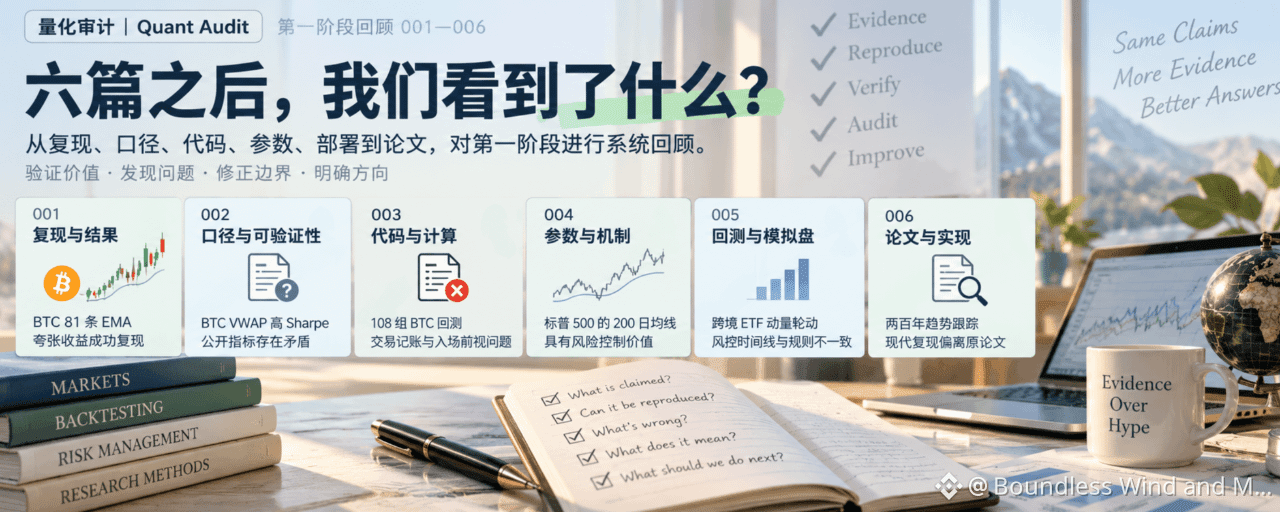

From the first article to the sixth, “Quantitative Audit” has covered a much broader range of research than we initially expected.
It all started with a Bitcoin moving-average strategy making the rounds on social media. The claim that all 81 EMAs outperformed Bitcoin was eye-catching—and hard to believe. After that, we came across high-Sharpe VWAP strategies, open-source backtesting projects, classic moving averages for the S&P 500, cross-border ETF momentum rotation, and a trend-following study claiming to span two centuries.
As the subjects of our research have changed, so too have the questions we’re asking—and they’ve grown more probing.
At first, we wanted to know whether an impressive equity curve could be reproduced. Later, we began checking metric definitions, trade accounting, execution timing, and strategy versions, until the sixth article directly compared an academic paper with a modern code implementation.
With six articles complete, the series now has a fairly clear focus: examining whether the evidence behind quantitative claims is sufficient, and determining exactly how far the public conclusions can be supported.
This review mainly brings together the conclusions, lessons, and questions left by the first phase.
I. Six articles, six different audit questions
001: Extraordinary returns are not necessarily fake
The first article audited a Bitcoin strategy using an 81-day EMA.
The original authors claimed that, over a specified historical period, all 81 moving-average strategies with different lookback periods outperformed buying and holding Bitcoin.
Results like these can easily lead people to first suspect the data or backtesting method. But after rebuilding the test under the original authors' conditions, we confirmed that these historical results are reproducible.
As we changed the observation window further, the conclusion began to shift. The finding that all 81 moving averages outperformed depended heavily on the original test period; in some more recent historical windows, buy-and-hold performed better.
This established the series' first important principle: extraordinary numbers may be real, but that does not mean every interpretation derived from them is valid.
001 successfully reproduced the historical results and clearly established the limits of their applicability.
002: Impressive metrics need to be traceable
The second article turned to a BTC VWAP mean-reversion strategy.
The materials reported a high Sharpe ratio, high annualized returns, and a low maximum drawdown, presenting an attractive backtest on the surface.
But when we compared materials published at different times, we found significant changes in the metrics for the same strategy, while the public information did not provide sufficiently clear parameters, test periods, or version records. Some statistical fields also contained logical inconsistencies that were difficult to explain.
These issues are not enough to prove that the original backtest was necessarily wrong, but they are enough to prevent outside readers from independently verifying it.
002 therefore did not judge the strategy as true or false. It stopped where the evidence allowed: the public materials are currently insufficient to verify this backtest performance.
This kind of problem is quite common in quantitative content. Readers can see the results, but cannot confirm how they were produced.
003: Public code does not necessarily support publicly reported performance
The third article began examining strategy implementation in depth.
An open-source BTC trend-backtesting project published numerous parameter combinations, trade records, and performance statistics. The reported returns and risk metrics looked very impressive.
Code inspection first revealed problems with accounting for partial exits and calculating performance. A subsequent review confirmed that the program used the closing information from the first four-hour candle of the next day to decide whether to enter, but executed at the opening price of that same candle, creating clear look-ahead bias.
The return of margin after partial exits and the aggregation of final trade profits and losses also contained implementation flaws that affected account calculations or trade statistics.
These findings directly undermine the credibility of the original performance metrics. However, we have not yet completed a full rerun with the corrected code, so we cannot determine the specific direction or magnitude of each error's impact on final returns.
003 showed us that making code public is only the starting point for verification. Trade timing, account accounting, and performance metrics must be consistent with one another.
It also became the first article in the series for which we needed to keep a record of technical revisions.
004: The value of a classic strategy may be more modest than its legend suggests
The fourth article studied the S&P 500's 200-day moving average.
This is a classic rule that has long featured in investment discussions. The debate around it is nothing new: can moving averages generate excess returns, or do they merely provide some form of risk control?
The independent test produced a relatively clear result.
Over the historical period studied, the 200-day moving-average strategy gave up some bull-market gains but reduced deep drawdowns. Comparing it with moving averages using nearby periods also revealed no clear, consistent, unique advantage to the exact 200-day parameter.
We therefore accept its value for risk control in the historical sample, while remaining skeptical about the specificity of its parameters and its future effectiveness.
004's contribution was to separate the practical role of a classic strategy from the narrative that had built up around it over time.
A strategy can be useful even if it does not deliver everything people expect of it.
005: The backtest and paper trading may no longer be the same strategy
The fifth article studied cross-border ETF momentum rotation.
The original project reported substantial cumulative returns and a strong Sharpe ratio. Code inspection found that the backtest's risk controls used the day's high, low, and closing prices to assess risk, but executed sell orders at that day's opening price, creating a problem with the sequence of events.
But then an unexpected result emerged.
In exploratory experiments using independent market data and an independent implementation, strategy performance actually improved after risk-control execution was adjusted to follow the causally correct sequence of events.
This result reminds us that discovering look-ahead bias does not automatically mean it inflated returns.
However, this experiment did not use the original authors' complete data and execution environment, nor did it align trades one by one. It can therefore only show that such an improvement is possible; it cannot be treated as an exact reproduction of the original project's performance after correction.
Further inspection also found that backtest Mode B and paper-trading Mode B differed in their stop-loss rules, trigger conditions, and rebalancing methods.
This was the fifth article's clearer finding: the strategy validated by the historical backtest differed materially from the strategy currently running in paper trading.
Even if the two share the same name, historical Sharpe ratios cannot be treated as verified performance for the version currently deployed.
006: Reproducing a paper requires fidelity to the paper
The sixth article examined a much more classic study: (Two Centuries of Trend Following).
The paper studies the trend-following effect using long-run historical data, while a modern commodity-futures implementation on QuantConnect produced a negative Sharpe ratio and used it to discuss the possibility that trend information may have decayed.
On the surface, the two seemed to be in stark conflict.
But after inspecting the public code, we found that the modern implementation made substantial changes to the original paper's core volatility definition and position-sizing formula.
The paper measures risk using an exponential moving average of the absolute monthly price change; the public implementation instead feeds signed price changes into the smoothing calculation. The position-sizing formula also differs from the original paper.
The conclusion that a negative Sharpe ratio can support therefore needs to be narrowed.
It can reflect the historical performance of this specific implementation, but it is not enough to directly prove that the trend strategy studied in the original paper has failed.
006 added an important audit dimension to the first phase: using the same research name, paper citation, and code comments does not guarantee that the same model is actually being run.
II. What conclusions have we reached after six articles?
Looking back at these cases, we can see several conclusions that have gradually become more settled.
First, audits must remain open to any outcome
001 successfully reproduced the extraordinary returns, 004 acknowledged the historical value of classic moving-average strategies for risk control, and 005's exploratory experiments showed that fixing code errors does not necessarily reduce performance.
If we assume in advance that all high returns are suspicious, or treat finding an error as the only measure of an article's success, it is easy to overlook results like these.
Research requires critical thinking, but also the ability to acknowledge evidence from the opposing side.
A strategy may work, may work to some extent, or may simply be impossible to assess based on the available materials. We must allow these outcomes to emerge naturally.
Second, reproduction comes in different levels of evidence
Across the six articles, some conclusions came from calculations using independent historical data, some from direct code inspection, and some could go no further than assessing whether the public materials were verifiable.
These forms of evidence cannot substitute for one another.
An author's report of profits does not mean that we have reproduced those profits; a flaw in a source code does not automatically tell us what the corrected returns would be; and a controlled experiment using independent data cannot directly substitute for the original project's complete trade records.
An important achievement of the first phase was gradually learning to make these boundaries clear.
State a conclusion only as far as the evidence supports it.
Finally, the audit expanded to cover the entire chain of evidence behind a strategy
At first, we focused mainly on checking returns. In the later articles, the audits covered formulas, code, account calculations, risk management, and paper-trading execution.
This shows that the credibility of a quantitative strategy cannot be determined from a single equity curve.
From the author's description to the strategy rules, from the raw data to the backtest code, and then to individual trades and performance statistics, a problem at any critical stage can weaken the final conclusion.
And even a historical strategy that passes these checks still needs further validation against out-of-sample performance and real-world execution.
This is a direction for future audits to explore further, but there is no need for every article to undertake the full validation process.
III. In the first phase, we also found shortcomings in our own work
This review examined not only the projects we audited, but also our own articles.
003 is the clearest example.
The initial audit had already found trade-accounting problems, but later we confirmed a more direct look-ahead bias in the entry. This shows that even after an article is complete, its conclusions should not be frozen forever. When new evidence is strong enough to change the original analysis, it needs to be revisited.
005 exposed problems in how the experiment was presented.
A controlled experiment using independent data is informative, but it is clearly distinct from an exact reproduction of the original project. The article can retain the surprising finding that performance improved after correction, while clearly explaining the limitations of the data and implementation so readers do not mistakenly believe that the original project has been fully validated after correction.
Visual presentation can cause similar problems. Some earlier covers featured assets unrelated to the strategy or inaccurate formulas. Although these mistakes arose during image production, they could still give readers a false impression.
So after reviewing the first phase, we began including the cover, title, summary, and charts in our pre-publication fact-checking.
These revisions do not change the series' original goal, but they have made its research requirements more explicit.
We must allow our own conclusions to be audited just as we audit others'.
IV. Which principles are worth keeping?
After completing six articles, it is natural to think about making a more detailed plan: scheduling topics in advance, setting a publication frequency, and designing a fixed article structure to make the series look more organized.
But we believe this approach carries clear risks.
The value of 001 through 006 lies precisely in the specific problems we encountered during the research. Some materials are suitable for replication, some only require checking metric definitions, some demand an in-depth code review, and in other cases comparing the paper's formulas is enough to reach a sufficiently reliable conclusion.
If every article must conduct the same tests, show the same number of metrics, and then include a fixed section for a twist and a conclusion, the research can easily become repetitive in form.
So after the first phase, we decided to keep a relatively stable set of working rules while remaining open about topic selection.
Topics are chosen based on the value of assessing a specific claim. We begin when we find a question worth verifying; if there is insufficient evidence or the marginal value of further research is too low, we pause.
The depth of analysis should likewise depend on the question. If precise reproduction is possible, reproduce precisely; when public information is insufficient, conduct an audit of verifiability; if the code already provides enough evidence to establish an implementation error, there is no need to add a large number of tests just to make the article longer.
The article structure emerged naturally from the research process, without requiring a fixed number of pieces of evidence, risks, or explanatory sections.
The principles that have emerged can be summarized as follows:
Keep research standards fixed and topic selection open; uphold quality standards without setting production quotas.
This is also a core principle that the (Quantitative Audit Working Rules v1.0) aims to preserve.
V. What comes next?
The first phase has shown that 'quantitative auditing' can span different asset markets and research subjects while producing work with independent value in its conclusions.
Crypto assets, stock ETFs, cross-border rotation, commodity futures, open-source code, and academic papers can all be subjects of an audit.
But that does not mean we must cover these areas in rotation going forward.
There is no need to decide on topics for 007, 008, or even further ahead, nor to require each new article to be more complex or more astonishing than the last.
What is truly worth pursuing is material that makes a clear claim, provides verifiable evidence, and could change readers' judgments as a result of an audit.
If it shows that a strategy is genuinely reliable, we should acknowledge that. If it reveals an evidence gap that cannot be resolved, we should honestly stop there.
Future research will continue to encounter errors and judgments that need revision. Allowing updates is what can keep the series credible over the long term.
A final note
After six articles, we understand 'quantitative auditing' much more clearly than we did at the outset.
The quantitative world has never lacked impressive backtest curves, nor formulas, parameters, and performance metrics that look rigorous. The question is how strong a conclusion these things can actually support.
Some surprising results are reproducible, yet still fall short of a stable edge; some strategies do have value, but are not as magical as advertised; some code errors are serious enough to overturn the original validation, while the impact of other errors can only be determined by recalculation.
Our aim is to make these distinctions as clear as possible.
The first phase produced six articles and a set of working rules tested against real cases. These rules still need to be refined through future research, but they are already sufficient to support the next phase.
Ultimately, the value of quantitative auditing depends on whether we can let the evidence constrain our conclusions.
We will decide where to begin the next article when the next question worth auditing arises.