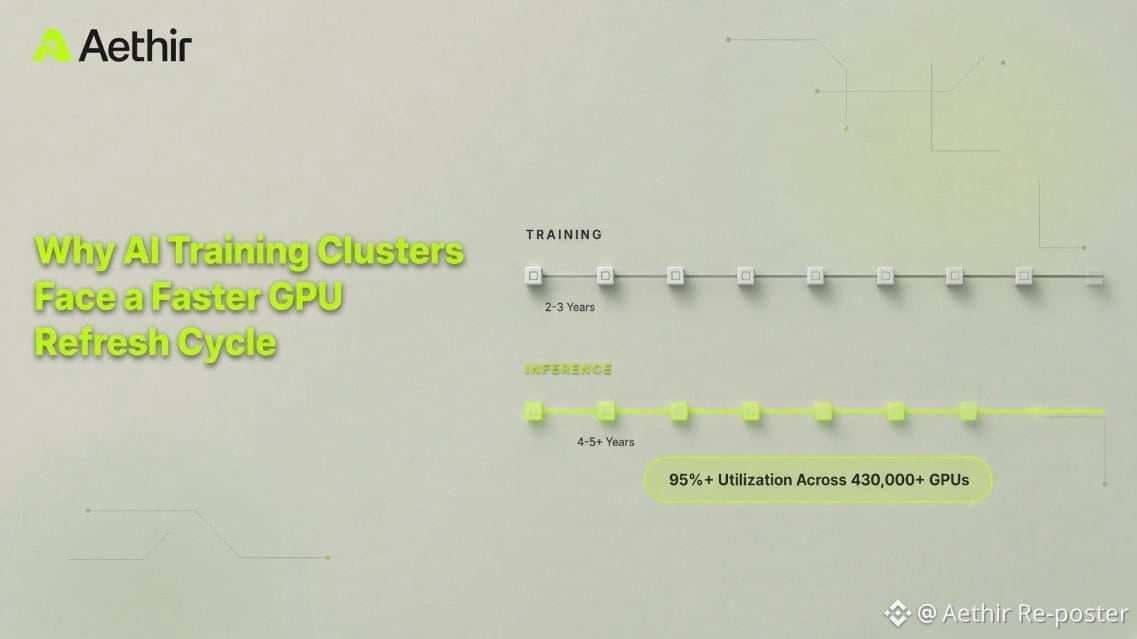
A carefully managed fleet mix acts as your best hedge. Blending the useful lifespan of every GPU into a single average ultimately obscures the specific variable that truly matters. In practice, fleets dedicated to inference operate on a 4 to 5 year replacement schedule, whereas training fleets are modeled around a 2 to 3 year turnover. We invite you to read our newest blog post below to learn more about GPU refresh cycles during this era of rapid AI evolution. 👇

Post
Disclaimer: Includes third-party opinions. No advice. Binance AI may be used without guarantee. See T&Cs.