


Its hidden-space factor can be analyzed and used to generate experimentally verifiable biological intervention schemes or to reproduce physical laws, pushing AI from mere prediction toward a scientific discovery interface that is interpretable and testable.
Article author: Qbit
Source: Mars Finance
In a technical report, two research subjects that look completely unrelated appeared—following AI really does broaden one’s horizons.
One is organoids derived from patients, while the other has crossed into the macroscopic universe……
Let’s start with the former. Researchers use internal factors learned from the model to propose an intervention strategy combining cytokines with antibody blocking, and validate it step by step through cell lines, organoids, and mouse experiments.
As for the latter, researchers feed the simulated planetary position and velocity trajectories to the model, without telling it Kepler’s laws.
After it finishes training, they analyze the prediction patterns inside it. The fitted slope of the extracted “orbital frequency–semi-major axis” relationship is -1.4991 (the theoretical value from Kepler’s third law is -1.5), with R² = 0.99999999.
Two domains that have nothing to do with each other—tumor research and planetary orbit computation—somehow can be solved using the same predictive learning method.
The world is vast and varied: weather, molecules, cells, patients, robots, and even planets all follow completely different rules.
But when AI understands “how they change,” is it possible for them to share a deeper, underlying method?
Recently, PhAI Labs, together with university teams such as Oxford, Stanford, Princeton, and the Chinese University of Hong Kong, released the latest JEPA-Anything, attempting to answer this question.
The paper shows that JEPA-Anything is a cross-domain framework for learning and predicting models of different “worlds.”
In each domain, it retains its own observation format, context-target construction, and encoder, but shares the subsequent prediction core and a unified latent world-state interface.
Among them is a key mechanism called OPF (Orthogonal Predictive Factorization, orthogonal predictive factorization).
It can be simply understood as:
Don’t pile all kinds of changes into one bucket to learn modeling together.
To model the world, one prediction pathway may not be enough—before clarifying a concept, in this JEPA-Anything study, what does “world model” actually mean?
The definition provided in the JEPA-Anything paper has both breadth and practicality.
In the paper, it says that as long as the model can build an internal state from existing information (Context) and use it to predict another state of the same system, it can be categorized as a latent world model.
Here, “another state” can be the future in time, or it can be hidden regions in space, different viewpoints, and even the outcomes after applying some kind of intervention.
Following this line of thought, the industry has developed increasingly mature technical routes over the past few years.
For example, DreamerV3 emphasizes building an environment model first, then “imagining” action consequences inside the model; V-JEPA 2 combines video representation learning with robot control, so that before planning an arm movement, the robot first predicts the physical feedback caused by different behaviors.
And JEPA—Joint-Embedding Predictive Architecture, the joint-embedding predictive architecture—is one representative line of approach.
Instead of directly reconstructing the target state in the original space, JEPA chooses to make predictions in the representation space, without needing to restore every pixel or detail.
It first encodes observation information into internal representations in latent space, and then performs prediction within that representation space.
This design leaves more representation capacity to structures that are prediction-relevant, reducing interference from raw-space details like textures and noise.
However, standard JEPA typically funnels all information into a single target embedding and follows the same prediction path.
But in the real world, changes are often not a single thread.
For instance, the overall translation of molecules is often accompanied by microscopic vibrations of internal atoms; in slowly evolving large-scale meteorological systems, severe local perturbations get mixed in; biological systems are even more complex—changes across multiple scales and multiple pathways occur in synchrony.
When signals of different scales, different entities, and different difficulties are forced together, those that are easier to predict and have more prominent changes may occupy more of the prediction capacity first.
By contrast, those relatively weaker yet still crucial pieces of information are either canceled out by gradient conflicts or completely masked by strong signals.
Researchers summarize this as a problem of “how prediction capacity is allocated,” and also propose new solution ideas.
Since crowding causes compression, let’s decouple the space.
And this is how JEPA-Anything came about.
Its core mechanism, OPF (orthogonal predictive factorization), splits an originally complete target state into multiple complementary subspaces, lets different prediction branches handle them independently, and finally recombines them into the full world state.
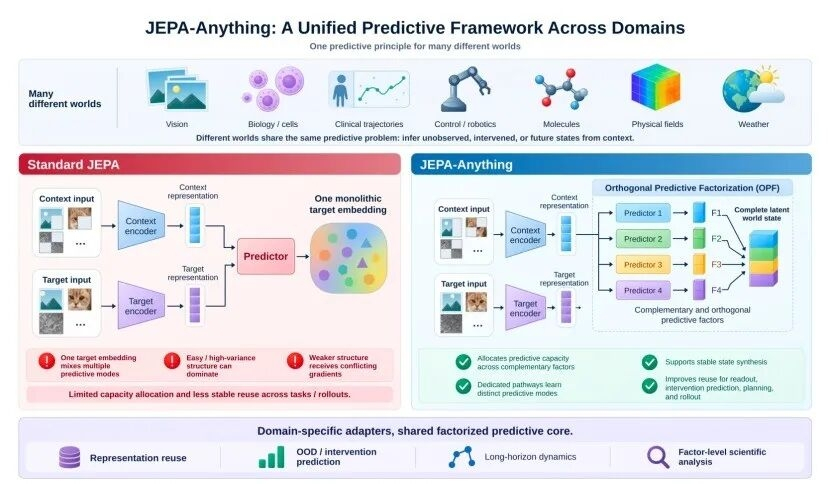
To prevent multi-branch evolution from becoming redundant states where multiple “teams” learn the same thing, OPF introduces an orthogonality constraint so that different factors occupy prediction directions that overlap as little as possible, reducing repeated learning of the same kind of information across branches; meanwhile, factor-activity constraints and encoder-variance constraints prevent some factors from deactivating and reduce the risk of representation collapse.
Worth noting is that these factors were not predetermined to say, “you handle velocity,” “you handle temperature,” or “you handle this biological pathway.”
What they learn is determined by the predictable structure in the data.
After training, these factors therefore leave behind an internal interface that can be used for later analysis.
Even if the predictive core is the same and the methodology is validated across seven kinds of systems, it still must ultimately undergo tests of cross-domain generalization.
This also has to mention the distinctive design of the JEPA-Anything experiments.
It is not limited to traditional domains such as video representation or robot control; instead, it places the same prediction core (Predictive Core) directly into seven distinctly different systems: vision, biology, clinical, control, molecules, physical fields, and weather.
By “Anything,” it does not mean forcibly scattering and reconstructing all domains’ data into a single common input format. Images, single-cell sequences, molecular structures, and even meteorological data still preserve their own most suitable encoders and data formats.
It unifies a set of underlying rules like this:
Once data is transformed into latent space representations, how should the prediction component be built—how should learning be carried out?
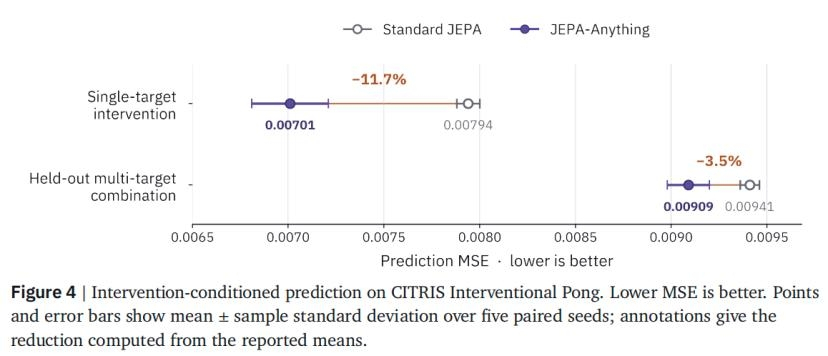
The paper first conducts experiments in a controlled dynamical environment, CITRIS Interventional Pong, constructed from a simplified Pong, to verify whether the model can “disentangle and recombine” compound changes.
During training, the model only receives change data from a single factor; during testing, it must face multi-factor combinations of interventions that have never appeared before.
If a model simply memorizes the complete patterns in the training set, it will inevitably fail when facing entirely new combinations; but if the model learns state-transition rules that can be reused across different changes, then it has a better chance to recombine them in unseen combinations.
Experimental results show that, under single-factor interventions within the distribution, JEPA-Anything reduces prediction error by about 11.7% compared to standard JEPA; under multi-factor combinations not seen during training, the mean squared error (MSE) also drops by about 3.5%, with improvements across all five paired training seeds.
Then, the validation moves toward more complex real systems.
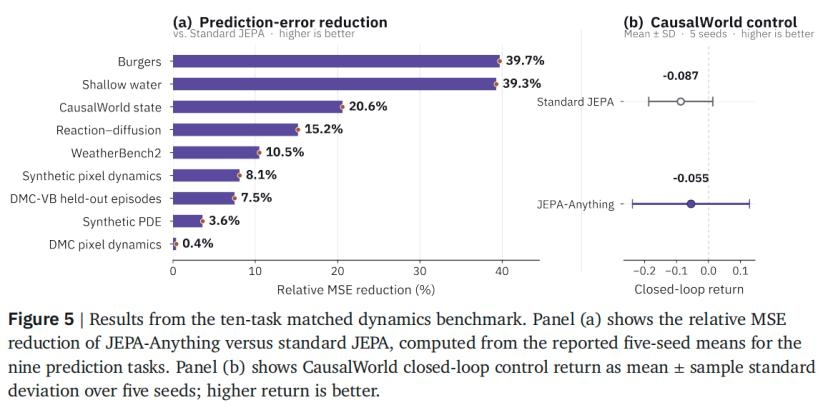
The paper constructs a strictly aligned dynamics benchmark (Matched Dynamics Benchmark), ensuring that across ten tasks standard JEPA and JEPA-Anything use exactly the same training data, encoders, state-transition backbone networks, computation budget, and evaluation splits.
In nine of the predictive tasks, JEPA-Anything improves its performance metrics.
For example, in PDEBench’s Burgers equation, MSE drops by 39.7%; in the shallow water equations, it drops by 39.3%; and in WeatherBench 2, it drops by 10.5%.
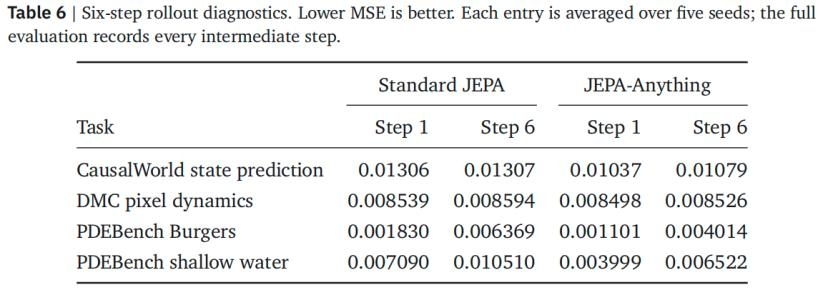
The paper also specifically performs multi-step rollouts: making each prediction serve as the input for the next prediction, to observe what happens after errors continue to propagate.
Molecular systems stretch the timeline even further.
In four systems—liquid water, α-quartz, paracetamol, and benzene—the model needs to continuously predict future atomic positions and velocities, and feed its own outputs back in over and over again.
Ultimately, whether it’s the one-step prediction MAE or the final position RMSD after a 100-step free rollout, JEPA-Anything achieves the lowest error across four molecular system settings.
But it’s worth noting that the experimental data does not show an idealized curve dominated by a single mechanism across the board.
In continuous control tests, JEPA-Anything isn’t better on every task: on Walker2d and HalfCheetah, its average score is higher than that of standard JEPA; but on Hopper, standard JEPA performs better.
The farther the distance for continuous prediction, the more errors will accumulate.
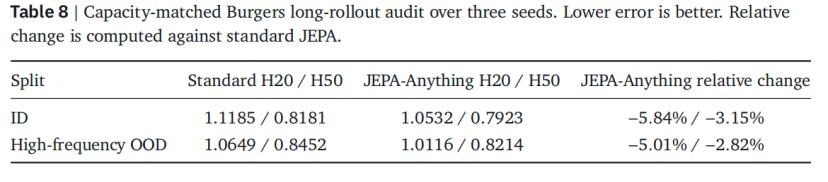
In additional Burgers tests, when the prediction horizon increases from 20 steps to 50 steps, JEPA-Anything is still ahead, but its advantage has clearly shrunk.
Therefore, this report verifies that “the joint prediction principle has cross-domain applicability,” rather than “a unified world model across all domains has already been achieved.”
At least these results indicate that the prediction principle has potential for reuse across domains.
What JEPA-Anything learns in its structure—can it stand up to external validation? The earlier experiments mainly answered whether prediction and state representations are effective. In the third set of experiments, the paper continues to ask an even deeper question:
Do the factors formed in the model’s latent space actually have value for scientific exploration?
Thus, we arrive at the two research cases at the beginning of this paper—distinct in style, yet echoing each other across distance.
Case 1: From internal factors to testable candidate interventions. In liver cancer research, the team did not treat JEPA-Anything simply as a “black-box predictor.” Instead, they conducted domain analysis on the orthogonal factor coordinates formed inside it, and extracted a candidate combination: blocking IL-18 together with NT5E/CD73.
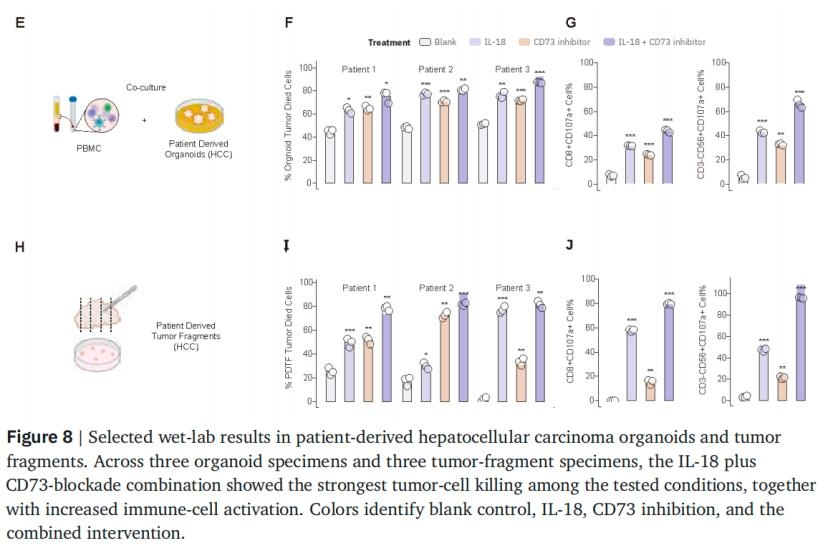
The research team then extends it to a Huh7-PBMC co-culture system, then to patient-derived hepatocellular carcinoma organoids and tumor tissue fragments, and afterwards adds immune-competent mouse validation.
Experimental data shows that in three patient organoids and three tumor tissue fragments, the combination of IL-18 and the CD73 blocking agents exhibits the strongest tumor cell killing effect, along with a significant enhancement of immune cell activation.
This means the model’s internal latent factors no longer exist merely to make prediction numbers look “better.”
It becomes an interface for researchers to analyze system states and propose candidate hypotheses that can be experimentally tested, thereby forming a chain: “model internal structure → domain analysis → candidate interventions → experimental validation.”
Case 2: The planetary orbit “reconciliation” story, moving from latent modes to known physical laws. Instead of looking for new laws, it uses the already-known Kepler’s third law as a benchmark to test whether what the model has learned internally has physical meaning.
The researchers only input the planetary position and velocity trajectory generated by simulation to the model, without attaching any prior formulas.
After training, researchers perform spectral analysis on the model’s latent modes, pairing the extracted frequencies with orbital semi-major axes.
The results show that even without manually preset formulas, researchers still extract scale laws highly consistent with the relationships among variables from the model’s learned latent modes—fitted slope -1.4991, very close to the theoretical value -1.5, with extremely small error.
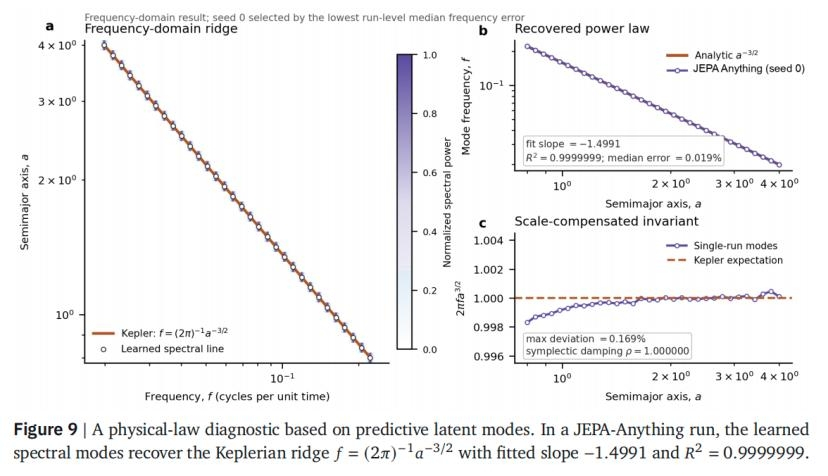
One case starts from internal factors and goes toward wet-lab experiments; another takes out internal modes, and reconciles them with existing physical laws.
Together, the two provide evidence from different angles that the internal structures learned by the model can become an interface for scientific analysis.
Researchers aren’t restricted to looking at a single prediction number at the endpoint; they can further ask what changes it actually captures. Do those changes correspond to real rules? Can it generate something worth validating in the next step?
This also matches JEPA-Anything’s positioning within PhAI Labs’ broader strategic context.
Earlier, PhAI Labs proposed “Discovery Foundation Models” (DFM), aiming to push AI toward open-ended scientific exploration.
In the DFM vision, AI needs to further participate in identifying the unknown, forming hypotheses, designing interventions, and continuously correcting the scientific discovery process based on external evidence.
JEPA-Anything sits at the world-model layer of this overall structure.
It aims to compress the parts that are predictable from scientific trajectories and real-world changes into a prediction capability that can be called more quickly, providing an approximate judgment before the more time-consuming and costly real experiments.
At this point, re-examining the span from “cancer cells to planetary orbits,” its significance no longer stops at showing visual contrast or conceptual novelty.
What the researchers explore is whether, for complex systems with very different mechanisms, AI can share the same kind of learning “evolution logic”; and whether, once these changes are encoded into internal states, researchers can take out those internal structures for analysis and validation through experimental results and known laws.
Of course, this is still far from “AI understanding everything.” What JEPA-Anything offers now is more like a possibility:
The structure learned inside the world model can be used not only for prediction, but also further analyzed by researchers and tested through experiments and known laws.
In other words, the model isn’t only predicting a world—it also starts exposing the “world” it has learned, so scientists can continue studying it.