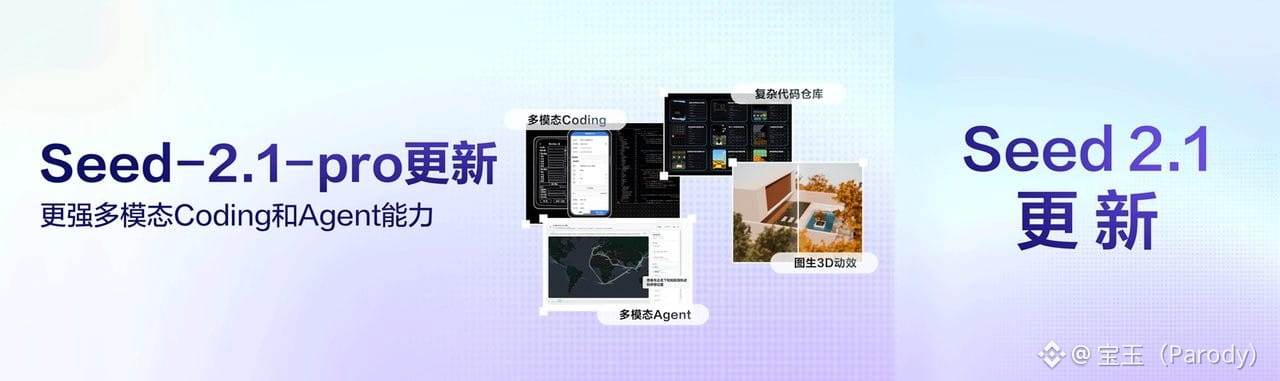
Doubao Large Model 2.1 Pro releases the 0915 update. The API has been fully rolled out on Volcano Ark. This upgrade focuses on four areas: Agent task delivery, multimodal coding, multimodal understanding, and inference cost.
Improvements on the Agent side
In scenarios that require multi-turn tool calls,联网查资料 (browsing the web to find information) and then producing reports, the model has strengthened its evidence tracing and data verification capabilities, with hallucinations reduced significantly. The official example is in finance research and investment: the model can autonomously break down research requirements, retrieve data sources, and rebuild an analytical model; the resulting working drafts are close to an analyst’s level. To verify a claim in a vehicle manufacturer’s quarterly report, the model orchestrated more than 500 sub-Agents, retrieved over 1,000 webpages, and cross-compared multi-source information such as maritime navigation tracks and satellite imagery. These capabilities—“not relying on a single-sided press release, but validating through multi-source cross-checking”—have direct value for enterprise due diligence and producing research reports.
Multimodal Coding
The most practical change this time may be writing code from images. The model can now directly understand design drafts, blueprints, and even operation screen recordings, converting visual information into front-end code. The official demo showed a scenario: give the model a screen recording plus a few sketch drafts, and have it develop a mobile page for an old ERP system without documentation. The model understood 280,000 lines of Java code and directly reconstructed a runnable mobile page.
For codebase understanding, the model independently tested and repaired Luanti (open-source game, about 387,000 lines of code). 83% of the tasks met the standard for being mergeable. For developers who often need to locate issues in large projects and debug across files, this number is worth paying attention to.
Other upgrades
In multimodal understanding, video reasoning has been enhanced: the model can locate evidence within videos and integrate information across frames. Image understanding has also improved markedly in 3D object recognition (CAD components, game engine elements) and dense image-text parsing (engineering drawings, financial report tables).
On costs, token consumption for image and video inference is reduced by more than 30% compared with the previous generation.
For API usage, there are two entry points: calling Doubao-Seed-2.1-pro-0915 lets you lock to a specific version; calling Doubao-Seed-Evolving automatically follows the latest version, so you don’t need to change the Model ID. Doubao Work and TRAE have also been integrated.
Official article: https://mp.weixin.qq.com/s/Fp_mgF6wxMk0bkUVBqOKqA
Improvements on the Agent side
In scenarios that require multi-turn tool calls,联网查资料 (browsing the web to find information) and then producing reports, the model has strengthened its evidence tracing and data verification capabilities, with hallucinations reduced significantly. The official example is in finance research and investment: the model can autonomously break down research requirements, retrieve data sources, and rebuild an analytical model; the resulting working drafts are close to an analyst’s level. To verify a claim in a vehicle manufacturer’s quarterly report, the model orchestrated more than 500 sub-Agents, retrieved over 1,000 webpages, and cross-compared multi-source information such as maritime navigation tracks and satellite imagery. These capabilities—“not relying on a single-sided press release, but validating through multi-source cross-checking”—have direct value for enterprise due diligence and producing research reports.
Multimodal Coding
The most practical change this time may be writing code from images. The model can now directly understand design drafts, blueprints, and even operation screen recordings, converting visual information into front-end code. The official demo showed a scenario: give the model a screen recording plus a few sketch drafts, and have it develop a mobile page for an old ERP system without documentation. The model understood 280,000 lines of Java code and directly reconstructed a runnable mobile page.
For codebase understanding, the model independently tested and repaired Luanti (open-source game, about 387,000 lines of code). 83% of the tasks met the standard for being mergeable. For developers who often need to locate issues in large projects and debug across files, this number is worth paying attention to.
Other upgrades
In multimodal understanding, video reasoning has been enhanced: the model can locate evidence within videos and integrate information across frames. Image understanding has also improved markedly in 3D object recognition (CAD components, game engine elements) and dense image-text parsing (engineering drawings, financial report tables).
On costs, token consumption for image and video inference is reduced by more than 30% compared with the previous generation.
For API usage, there are two entry points: calling Doubao-Seed-2.1-pro-0915 lets you lock to a specific version; calling Doubao-Seed-Evolving automatically follows the latest version, so you don’t need to change the Model ID. Doubao Work and TRAE have also been integrated.
Official article: https://mp.weixin.qq.com/s/Fp_mgF6wxMk0bkUVBqOKqA