

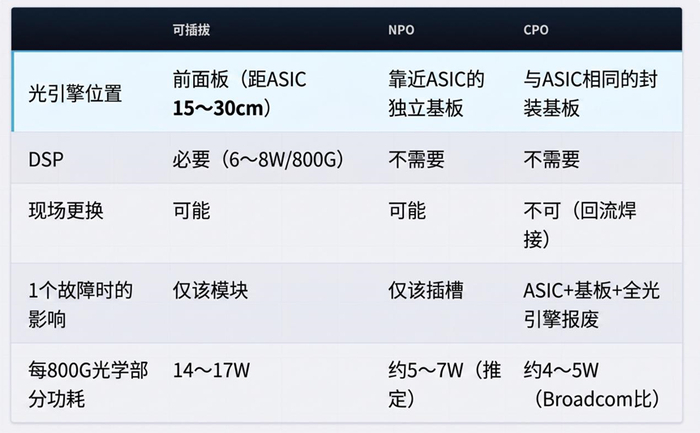
Open the data center rack and you can see rows of optical transceivers lined up across the front panel of the switch. In an AI cluster, it is common for a single switch to be equipped with 144 800G-compatible QSFP-DD modules. However, this configuration has a structural inefficiency. The distance from the transceivers on the front panel to the switch ASIC chip is 15 to 30 centimeters. When 200G-per-lane signals are transmitted along this copper trace, they experience significant attenuation, requiring DSP (digital signal processing) chips at the receiving end to recover the signal. The power consumption of a single 800G module is 14 to 17 watts, with 6 to 8 watts of that consumed by the DSP chips. In other words, in traditional pluggable optical modules, a substantial portion of the power is not used directly for optical-electrical conversion, but instead is spent on conditioning, equalization, and transmission of high-speed electrical signals.
Shortening this distance eliminates the need for DSP. This idea emerged as early as the mid-2010s. Co-packaged optics (CPO) places the optical engine (a set of components that converts electrical signals into optical signals) and the switch ASIC on the same substrate, greatly shortening the high-speed electrical connection distance between the ASIC and the optical engine and significantly reducing losses caused by copper interconnects. Broadcom announced that CPO can reduce the power consumption of the optical system by 65–70%. NVIDIA’s 1.6T link power consumption drops from about 30 watts per link to 9 watts.
In theory, CPO seems to be the optimal solution. The problem is the gap between theory and large-scale production.
A 9% yield reveals the truth
During CPO manufacturing, the optical engine is mounted onto the ASIC package substrate via reflow soldering (thermal soldering). Fiber alignment accuracy reaches the sub-micron level. If an installed optical engine needs to be replaced, it must be reheated to 220–260°C, and the heating location is several millimeters away from the ASIC—yet the fiber alignment accuracy cannot withstand the second thermal damage. In other words, if one out of 32 optical engines has a defect, the ASIC, the substrate, and all remaining optical engines must be scrapped.
In its June 2026 research report (Powered Down, Lights Off), SemiAnalysis assumes a 95% implementation yield for each optical engine and calculates a combined yield of 0.9532 ≈ 0.1932. In other words, under an extreme simplified model where 32 optical engines are independent and each has a 95% yield, the probability that all 32 engines pass together is about 19.3%. That means only one-fifth of the engines can work properly. This figure has a major impact on the market. On June 9 in the U.S. market, shares of Applied Optoelectronics (AAOI) fell by about 17% in a day, Lumentum dropped by about 8%, Coherent fell by about 11%, and Marvell fell by about 7.6%.
GlobalSemiResearch immediately issued a rebuttal statement, pointing out that this calculation ignores yield improvements brought by screening, grading, and the redundant engines NVIDIA designed for Spectrum-X. In a June 10 report, Morgan Stanley also did not deny the technology roadmap for CPO; it simply lowered its forecast for 2027 optical engine shipments from the previous 20 million–30 million units to 6 million–7 million units.
The focus of this debate is not “Is CPO not good?”, but rather “When and at what scale can CPO be used?” SemiAnalysis has pushed the crosswise shipment volume of CPO to 2027 and delayed full mass production to 2028-2029. Adjusting this timeline opens a window for exploring other architectures.
NPO is all-encompassing
Near-package optical devices (NPO) sit between package optical devices (CPO) and plug-in designs. The optical engine is installed on a separate engine board rather than on the ASIC’s package substrate, and it is located adjacent to the ASIC. When the electrical links are short enough and losses are low enough, DSP used to compensate for long-distance electrical link losses in traditional plug-in optical modules can be reduced or even eliminated in some architectures. However, the key difference from CPO is this: because the engine connects via a socket, it can be plugged in and out on-site.
On August 10, SemiAnalysis summarized three advantages of NPO at the X-thread forum: it can be repaired on-site, fault propagation (impact range) is limited to a single slot, and assembly is simplified because the optical engine and ASIC use independent packaging. This structure avoids production and reliability challenges while retaining most of CPO’s performance advantages.
At the OFC exhibition in March 2026, Broadcom released its NPO product line based on 3.2T VCSEL. According to the company’s blog, the optical engine’s energy efficiency is about 1 pJ/bit. Compared with typical 5 to 10 pJ/bit silicon photonics methods, energy efficiency improves by 5 to 10 times. After deploying 18 engines, the escapable bandwidth density exceeds 0.6 Tbps/mm, with total escapable bandwidth reaching 73.7 Tbps (128 Gbps/channel). VCSEL has decades of mass-production experience, and its现场验证的故障率 (FIT) is below 0.1.
The gears of standardization and mass production start turning
Even with an outstanding architecture, broad adoption is impossible without ecosystem support. On March 12, 2026, coinciding with the OFC conference, six companies—Ciena, Coherent, Marvell, Molex, Samtec, and TeraHop—jointly signed the Open CPX MSA (multi-vendor co-packaged optics agreement). The purpose of this agreement is to establish a common specification for the slot-based optical engine interface covering both NPO and CPO. It will standardize the connector’s mechanical structure, thermal design, electrical pin layout, and management interfaces, ensuring interoperability among products from different vendors.
At the announcement of the company’s founding, LightCounting CEO Vladimir Kozlov said, “We expect annual shipments to exceed 100 million units within five years,” while expecting that by 2025, shipments of CPO/NPO would be fewer than 1 million units. Without standardization, such massive growth (even over 100x) would not be achievable.
Demand is also evolving. At an IPEC webinar held in May 2026, Alibaba revealed plans to complete beta testing for its 3.2T NPO and begin pilot operations in the third quarter of the same year. Its goal is to complete system-level debugging of 6.4T NPO alpha samples before September 2027. Tencent has also completed validation of its 3.2T VCSEL NPO and silicon photonics NPO and plans to conduct a pilot deployment in the fourth quarter of 2026. Ranovus has delivered NPO modules to U.S. cloud companies, but it is expected to wait until the 2027 OFC event to officially announce them.
In the supply chain, Foxconn interconnect technology began in May 2025 to produce at scale for Broadcom’s Bailly unsoldered LGA-to-LGA sockets and plug-in laser light source cages. The lasers are mainly designed to be placed outside the package, whether for CPO or NPO, while the ELSFP standard (hot-pluggable external laser module) defined by OIF in August 2023 serves as a common foundation.
Why does Nvidia’s CPO exhibit characteristics of NPO?
NVIDIA’s Quantum-X Photonics InfiniBand switch has already announced the start of mass-deployment production. It offers 144 800G ports, equipped with 18 silicon photonic engines and 18 removable external laser modules to provide the optical light source. NVIDIA calls it “CPO.”
However, the engine can be easily detached from the package, and the laser can slide out from the front panel—this is precisely what SemiAnalysis considers NPO’s maintainability advantage. A LightCounting research report in July 2026 confirmed the industry view that CPO and NPO will coexist, and noted that if NVIDIA treats NPO as an option, the development cycle would shorten—possibly allowing early initial deployments as soon as next year.
Broadcom plans to deploy both architectures in parallel. The 51.2T Bailly CPO switch has been in mass production at Micas Networks since 2024. The 102.4T Tomahawk 6 Davisson switch began shipping to customers in October 2025. In addition, Broadcom will also supply a 3.2T VCSEL NPO switch separately to meet customers that need high-density switches but do not want soldering.
Meta’s reliability validation is also progressing steadily. In Meta’s high-temperature lab environment, Broadcom’s CPO system recorded zero link jitter (instantaneous interruptions) during cumulative operation of one million hours (equivalent to 400G port time). Broadcom announced this result in October 2025 and published the details at ECOC of the same year and OFC in 2026. At OFC 2026, Meta proposed the standard that “for optical technology to be compelling, it must be comparable to electrical solutions in cost and energy efficiency, while delivering reliability and performance.”
TSMC COUPLE plays a key role
The end of NPO’s “transition phase” depends largely on the progress of TSMC’s COUPE (compact universal photonic engine) platform.
As described above, it is well known that today’s AI chips already deliver extremely powerful compute performance, but when data is transmitted between chips, it still relies on copper wiring to conduct electricity. The transmission speed and energy consumption of copper lines are gradually unable to keep up with the pace of compute growth. COUPE’s core idea is to switch to optical signals for data transmission and move the optical-to-electrical conversion from the far-end optical module into the chip package itself, dramatically shortening the path the signal must travel.
COUPE integrates two types of chips: one handles electrical signals (EIC, electronic chip) and the other handles optical signals (PIC, photonic chip). Through TSMC’s 3D stacking technology, the two are stacked directly one above the other and connected face-to-face, eliminating the signal detours—and losses—caused by circuit-board routing in traditional approaches.
TSMC says that compared with plug-and-play solutions on circuit boards, integrating the COUPE optical engine directly into the package substrate can achieve 4x power efficiency and reduce latency by 90%. If the COUPE is further placed in the interposer layer, performance can be boosted to 10x power efficiency with a 95% reduction in latency.
COUPE technology uses SOIC stacking to directly stack the electronic chip and the photonic chip, minimizing the impedance between chips as much as possible. The first-generation plug-in COUPE is scheduled for mass production in 2026. The second-generation COUPE uses a 6.4T CPO package and is expected to enter mass production around 2027. The third-generation product will fully integrate optical components inside the processor package.
TSMC’s COUPE bandwidth density roadmap projection shows that the bandwidth density will increase eightfold within four years, from 0.5 Tbps/mm in 2026 to 4 Tbps/mm in 2030. If this plan is realized, NPO’s role will be limited to a two- to three-year transition period.
However, if the 2029 full mass production scenario predicted by SemiAnalysis is close to reality, NPO would continue to meet market demand until the end of the 2020s. In that case, it would add additional pressure to the photonics supply chain, which is already stretched thin in laser and packaging capabilities. At the OCP Asia-Pacific Summit, Nicole Tien of ASE pointed out that there are currently no wafer-level testing standards and simulation infrastructure to expand CPO across multi-vendor markets. NVIDIA’s CPO mass production is the result of deep, bilateral co-development with TSMC, and it currently lacks the conditions to scale those results across the entire industry.
Industry consensus holds that the ultimate form of optical interconnect is CPO. The question is: who will choose this path, when will it be achieved, and at what scale? At least based on current product roadmaps and customer validation, NPO is rapidly moving from technology verification to large-scale deployment, becoming a more certain answer.