

By / IT Times He Zhenyuan
Edited / Hao Junhui Sun Yan
When companies use AI, they usually have to pay twice.
The first time is visible costs, including subscriptions, computing power, and system building. The second time is harder to show up in financial statements, yet it may be more expensive. For AI to truly understand a business, employees must continuously explain to it business rules, customer preferences, judgment criteria, past failures, and correction methods—seemingly indispensable, yet full of risk.
Microsoft CEO Satya Nadella calls this phenomenon the “Reverse Information Paradox” to distinguish it from the “Information Paradox” described by economist Kenneth Arrow. Arrow points out that “the buyer can only assess whether it is worth purchasing after seeing the information; but once they see it, they have already obtained the information.”
In the era of AI, the direction of risk changes: even if an enterprise has already purchased intelligent services, it still needs to hand over its own knowledge for the service to become truly useful.
When the model answers incorrectly, an employee tells it where it went wrong. If the intelligent agent doesn’t understand the client, the salespeople supplement it with contextual information built through years of dealing with customers. If the system-generated contract is not up to standard, the legal team revises it line by line. Every prompt, correction, and evaluation may leave behind valuable new traces. Nadella calls them the “intelligent exhaust” of artificial intelligence.
This metaphor is quite apt. Car exhaust often means waste, but intelligent exhaust may contain valuable knowledge for the enterprise. Car exhaust needs to be managed; intelligent exhaust is similar.
What a bank truly cannot replicate is not publicly available loan terms and procedures, but the “sixth sense” alert a seasoned relationship manager feels when seeing a set of numbers. A retail company’s advantages are not only in its sales database—they may live in the store manager’s intuition about whether a product should be discounted, moved to a different store, or waited on for another week. When dealing with the same customer complaint, an experienced customer service supervisor knows when an immediate refund is needed and how the customers who care most about receiving a sincere explanation are different.
These experiences are rarely written into rules in a complete form. They are scattered across specific work, hidden within employees’ judgments about complex situations—yet they will reveal themselves little by little when people correct the artificial intelligence.
Problems follow. Employees think they are only completing a task, but objectively they are also training the system. Enterprises think they only need to purchase intelligent services, but in fact they are continuously “feeding” new organizational knowledge. If these prompts, corrections, evaluations, and work traces lack clear boundaries, enterprises will find it difficult to know how long they will be retained, for what purpose they will be used, and whether they might be used to improve services offered to other customers.
This doesn’t mean enterprises should keep away from AI. It also clearly means that enterprises must be told to choose intelligent services worth trusting with caution. More importantly, it means that service providers have a responsibility to help clients guard their knowledge boundaries. Enterprises need the courage to use AI; but first, service providers must make that use trustworthy.
If there is a TA company, from the very beginning it treats intelligent exhaust as the company’s “second capital.” From the initial stages of Agent design, it sets strict constraints and boundaries. Which data an Agent can access, which tools it can invoke, what actions it is allowed to take, which matters must be confirmed by humans—all of it must be strictly limited to the scope of authorization. The client’s business information, interaction traces, and proprietary experiences are kept strictly in isolated environments. Without explicit authorization, they do not enter the training and learning process for other customers. So, a TA company is more trustworthy and more dependable than one without these underlying mechanisms. Because the design of a TA company reflects an important principle: an intelligent service provider can provide models, platforms, and foundational capabilities, but the enterprise still controls the proprietary memory, evaluation standards, work traces, and learning outcomes formed during its use.
Truly reliable intelligent services will not require enterprises to choose between “gaining intelligence” and “keeping knowledge.” This also gives “intelligent exhaust” another possibility: instead of collecting a customer’s exhaust and dumping it into the public environment, the service provider helps the enterprise build its own “intelligent exhaust recovery system.” After high-quality整理, the intelligent exhaust enters the enterprise’s own knowledge base, evaluation system, and learning closed loop (Closed Loop). It accumulates over time and becomes an asset and capability the enterprise can use long-term.
The role TA companies play here goes beyond the scope of a traditional software vendor. It provides not only intelligent tools, but also a trusted execution environment—helping enterprises manage an Agent’s identity, permissions, memory, and behavioral boundaries. The deeper customers use it, the clearer enterprises should be about controlling their own knowledge and learning outcomes.
The legal system also needs to keep up with this kind of change. Existing laws already provide protection from different angles—personal information, data security, trade secrets, intellectual property, and contractual obligations—but for rights boundaries around memory, evaluation data, work traces, and adaptation outcomes continuously generated by human-machine interactions, they are still not clear enough. The problems brought by AI go one step further. Because if you look at any single prompt alone, you may not see much commercial value. But when you put tens of thousands of prompts, correction records, and evaluation results together, it may clearly reconstruct how a company serves customers, assesses risks, defines value, and makes decisions.
Therefore, in the process of enterprise intelligentization, the company’s rights need to extend from data rights to learning rights. Enterprises should have the right to know which interactions the system learns from; the right to refuse their business traces being used for external training; and the right to export, store, transfer, or delete memories, evaluation data, and adaptation outcomes generated by their own business.
Service contracts need to explain these issues fully and clearly. What the enterprise provides, how far the service provider can use it, which learning behaviors require separate authorization, which data should be deleted after the cooperation ends, and which outcomes the customer can take away—none of this should be hidden behind vague clauses.
The example of TA companies represents a kind of trustworthy service model. When the model proves effective, the interests of enterprises and intelligent services can be compatible. The clearer customers’ rights are, the easier it is for service providers to earn long-term trust. The stricter the boundaries are, the more enterprises dare to bring AI into genuinely important business processes. Protecting customer knowledge does not diminish the value of intelligent services—it turns one-time tool procurement into a stable partnership.
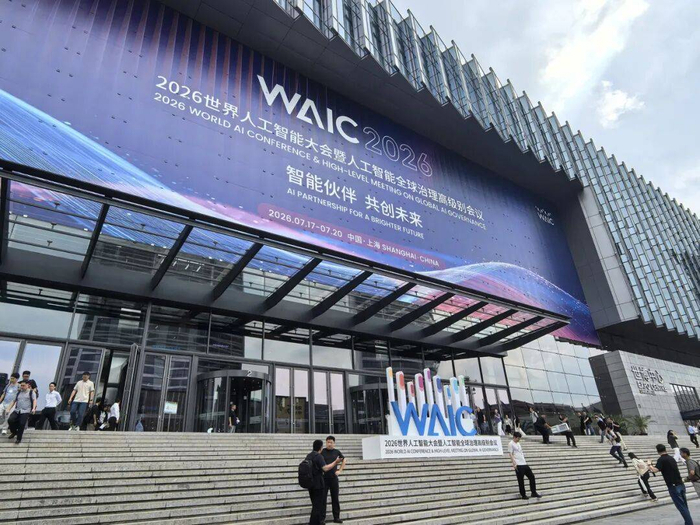
The World Artificial Intelligence Conference (WAIC2026) being held in Shanghai, themed “Intelligent Partners, Co-creating the Future,” features “partners” and “co-creating” as particularly inspired choices. The word “partners” clearly hints at a personalized, person-like meaning, while “co-creating” implicitly carries the idea of “sharing.” If those intelligent agents, emerging like bamboo shoots after a spring rain, were to have minds of their own, they might be moved to tears and make even greater efforts!
“Partners” implies collaboration, and also implies equal rights, obligations, and responsibilities. It means that an intelligent agent’s digital identity is recognized—even if that recognition is still partial, limited, and not yet codified in law. Intelligent partners and digital employees belonging to a service provider must work under the enterprise’s authorization, and they must leave the proprietary experience they form within the enterprise’s scenarios to the enterprise.
The more intelligent agents there are, the closer management issues become to organizational issues. If an employee enters a company, they need an account, a role, permissions, training, and evaluations—then an intelligent agent that can read client data, send emails, modify code, or process orders also needs clear identity verification and permission boundaries. Who it acts on behalf of, who commands and regulates it, how far it can go, who stops it when an error occurs, and whether the whole process can be rolled back and how to trace it—these should all be part of the company’s intelligent governance.
In the future, what enterprises will compete on is not only who can plug into the strongest models. They also need to examine who can effectively protect their intelligent exhaust, who can preserve the experience scattered across real scenarios and processes, and who can make every human-machine collaboration enhance the organization’s long-term capabilities.
Enterprise AI governance is absolutely not limited to “banning the spread of sensitive files.” It also needs to manage the scope of actions of intelligent agents, their learning methods, responsibility relationships, and knowledge ownership. From the very beginning of Agent design, TA companies clearly define restrictions and boundaries, precisely to ensure that once the intelligent agent enters business operations, it remains in a state that is knowable, controllable, and traceable.
When intelligent partners roll onto the scene one after another, they are all given their own names—some are a bit vague, like “financial robot” or “intelligent sales assistant.” Others already have polished, widely appealing real names like “Chen Jianan” and “Ma Rong.” Individuals have names, but the group does not. Looking back at the article I wrote, sometimes I refer to intelligent partners as “it,” sometimes as “they.” To be frank, I just can’t bring myself to use “the animal ‘it’” on a smart object!
One hundred forty or fifty years ago, Guo Zansheng paired the character “Yi” with “She,” using it as a feminine third-person pronoun—“He is in the garden, but Yi is in the library,” which is amusing and charming. Forty years after that, Liu Banong repurposed an old character for a new use: using “she” to refer to the motherland. The subtle, bittersweet (teach me how not to think of her) legacy has continued to this day. People who don’t know the background might think it is only natural—it was meant to be so.
In this argumentative essay about the issue of “she,” Liu Banong puts forward two key points: “First, in Chinese writing, do we need a third feminine pronoun? Second, if we do, can we use the character ‘she’?” Let me also borrow that approach and make two key points: First, if an intelligent partner has a name, does it need a unified third-person symbol that is easy to write? Second, if it’s needed, borrow “TA,” which has already been widely used for non-gender-specific reference, to call intelligent partners!
Layout / Jiaying Ji
Photo / IT Times WAIC
Source / IT Times WeChat Official Account vittimes