#opg $OPG A few days ago, I ran a test in chat.opengradient.ai by user @OpenGradient . I asked several models, using the same fairly tricky prompt, to each write an analysis of how token unlocks affect liquidity/circulating supply. The differences in the feedback from a few mainstream models surprised me.
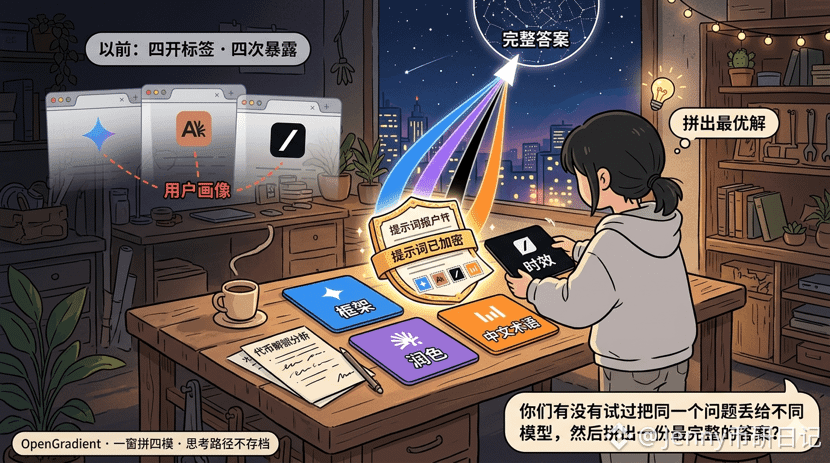
First, Gemini’s answer was the most like a research report: its structure was very tidy, and it listed key data points clearly, but it read like it was reciting a textbook. By contrast, Claude was more fluid—its communication logic felt very well-informed. The rhythm between short and long sentences was spot-on, making it ideal to paste directly into a PPT. Grok was the briefest, but it would insert relevant trending topics from X at the time, which gave it a strong sense of immediacy. However, its depth was slightly lacking. ByteDance Seed handled Chinese terminology the best; some localized expressions were captured with the exact nuance that other models simply couldn’t quite get.
What I found most interesting is that I can switch between them within the same conversation. I first let Gemini lay out the framework, then have Claude polish the wording, and finally ask Grok to add a line of real-time context. I don’t have to jump between pages, and my prompts don’t leave fragments across different platforms.
In the past, this kind of workflow required opening three or four browser tabs—each platform kept copies of my questions. After consolidating everything into one window, it saves a lot of trouble, and encryption is enabled by default. The platforms can’t see which models I’m comparing, and they also won’t know which token’s unlock schedule I’m researching.
After all, there’s no such thing as a perfect AI. It’s hard for a single model to excel at being rigorous, easy to read, and timely all at once. Now, you can assign each model according to what you need, and my thinking process won’t be archived by any platform.
Have you tried giving the same question to different models and then stitching together the most complete answer?