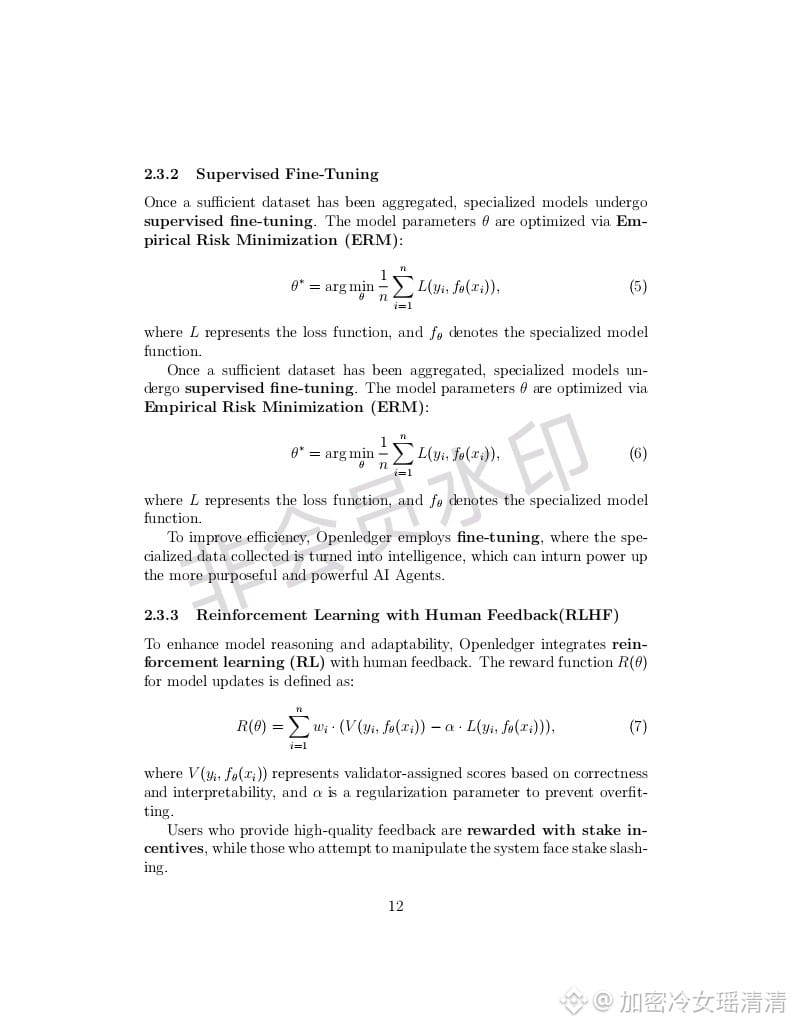
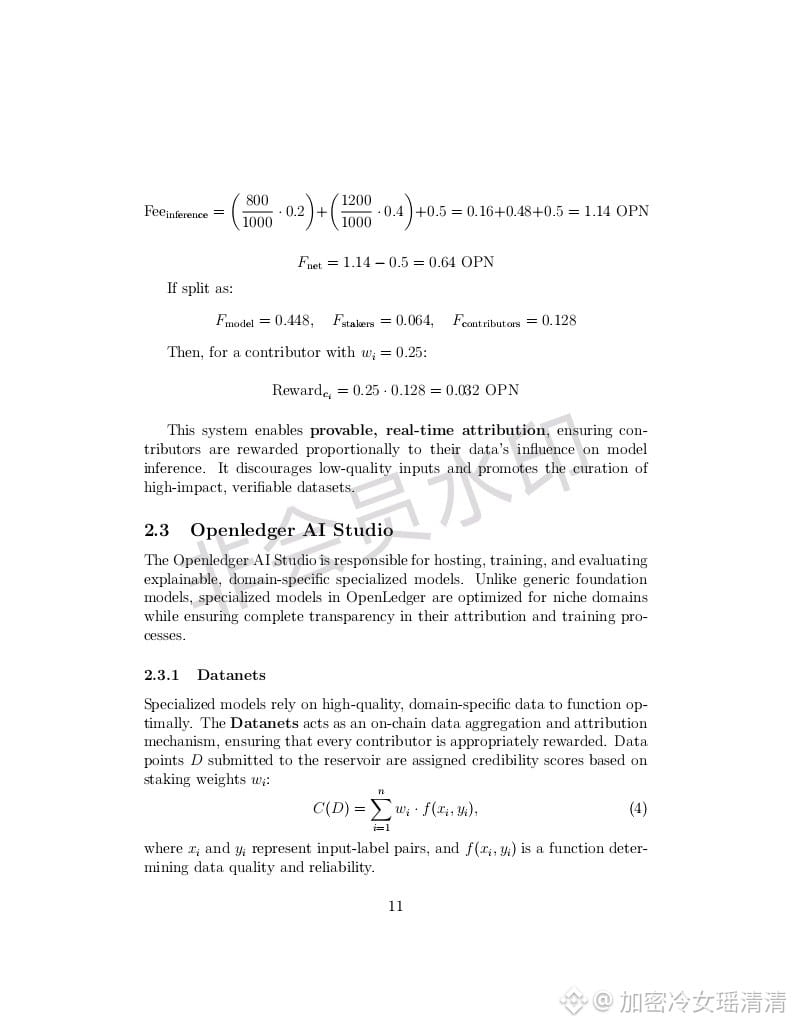
Let me share a real experience. I had about 1,200 labeled data points sitting around, just taking up hard drive space, until I tried the proof of attribution for #OpenLedger . The data gets called by the model and automatically logs contributions. I uploaded 300 data points to run an inference task, and the chain actually calculated my contribution value. The money isn't much, but the feeling is different. Your stuff gets used, and you can see the records. I've held onto Bitcoin and Ethereum for years, but those mainly deal with wallet transfers, which is a whole different ballgame from AI data profit-sharing.
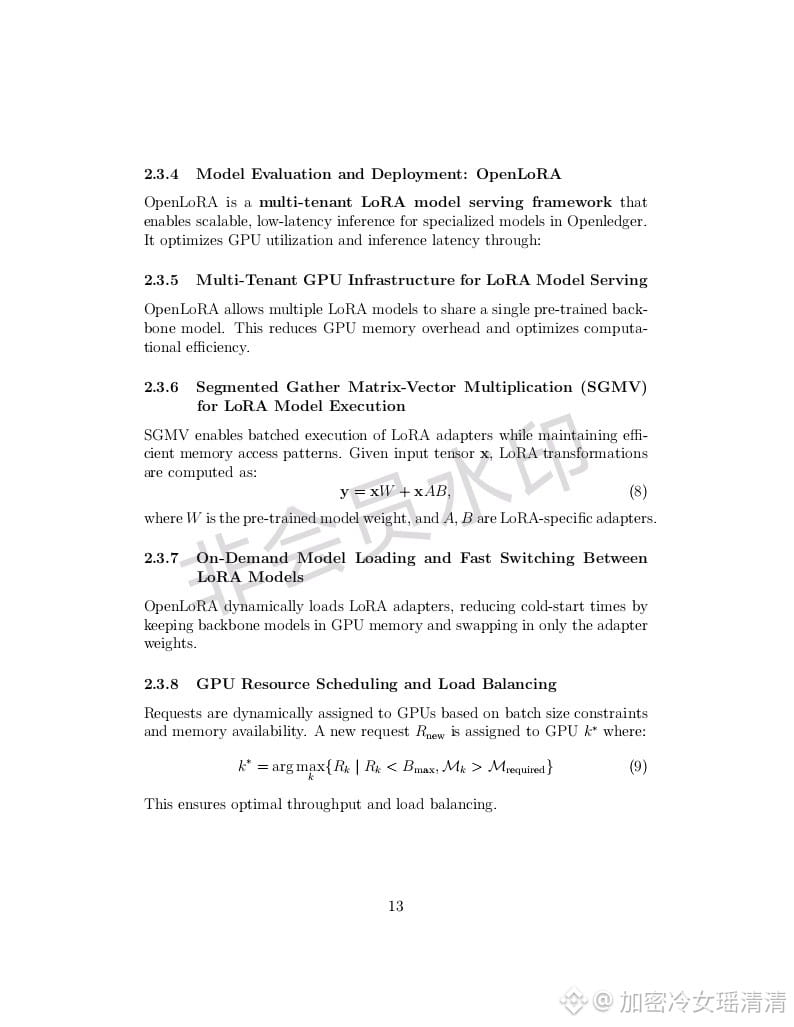
Today, Octoclaw, I spent another two hours tinkering. The cloud setup was way smoother this time than last. There were several preset parameters. I chose a lightweight template and pushed the data directly. I executed a cross-chain bridge transfer of $OPEN from the testnet to the mainnet, and it was done in under three minutes. Previously, using other bridges, I’d get stuck for half an hour. This time it was definitely stable. I even went back to check the attribution records. Out of the data I uploaded, about a dozen were called. Each call came with my on-chain tag and timestamp. The cost of faking this stuff is way too high.
Now, on to the gripes. The section on attribution algorithms in the documentation was way too academic. I had to read it twice just to grasp how the weights were calculated. Newbies are gonna be lost for sure. But overall, I’m on board with @OpenLedger in this direction. I’m willing to have every attribution displayed on-chain, which is way more genuine than those who just shout slogans. Next, I plan to throw in another 500 data points and run it for a month to see how the long-term yields pan out. If there are any pitfalls, I’ll hit you up right away; and if there’s good news, I’ll share that too.
Today, Octoclaw, I spent another two hours tinkering. The cloud setup was way smoother this time than last. There were several preset parameters. I chose a lightweight template and pushed the data directly. I executed a cross-chain bridge transfer of $OPEN from the testnet to the mainnet, and it was done in under three minutes. Previously, using other bridges, I’d get stuck for half an hour. This time it was definitely stable. I even went back to check the attribution records. Out of the data I uploaded, about a dozen were called. Each call came with my on-chain tag and timestamp. The cost of faking this stuff is way too high.
Now, on to the gripes. The section on attribution algorithms in the documentation was way too academic. I had to read it twice just to grasp how the weights were calculated. Newbies are gonna be lost for sure. But overall, I’m on board with @OpenLedger in this direction. I’m willing to have every attribution displayed on-chain, which is way more genuine than those who just shout slogans. Next, I plan to throw in another 500 data points and run it for a month to see how the long-term yields pan out. If there are any pitfalls, I’ll hit you up right away; and if there’s good news, I’ll share that too.