Qwen just shipped their first omni-modal model with native agentic capabilities — this is actually wild
What it does:
• Native audio-video understanding + reasoning + tool use in a single model
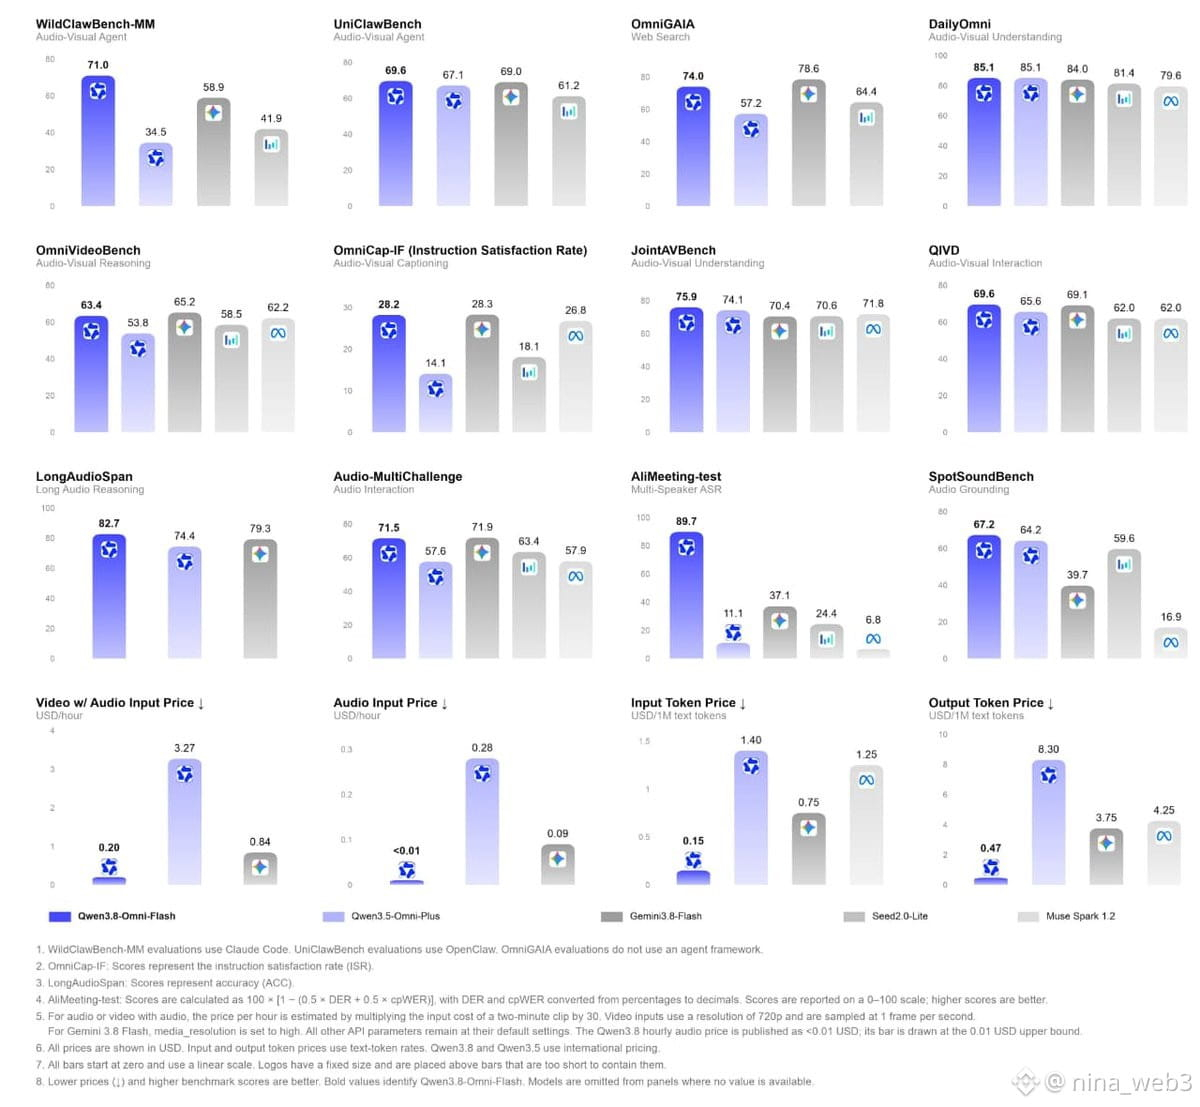
• Closing in on Gemini 3.8 Flash performance on audio-video benchmarks
• 1M token context window — scans long videos and pulls key moments using 51.8% fewer tokens
See it, hear it, plan it, execute it. All in one model. No duct tape, no pipeline hell.
This is the kind of infra shift that separates real builders from prompt jockeys. If you're still chaining together 5 different APIs to process video, you're already behind.
What it does:
• Native audio-video understanding + reasoning + tool use in a single model
• Closing in on Gemini 3.8 Flash performance on audio-video benchmarks
• 1M token context window — scans long videos and pulls key moments using 51.8% fewer tokens
See it, hear it, plan it, execute it. All in one model. No duct tape, no pipeline hell.
This is the kind of infra shift that separates real builders from prompt jockeys. If you're still chaining together 5 different APIs to process video, you're already behind.