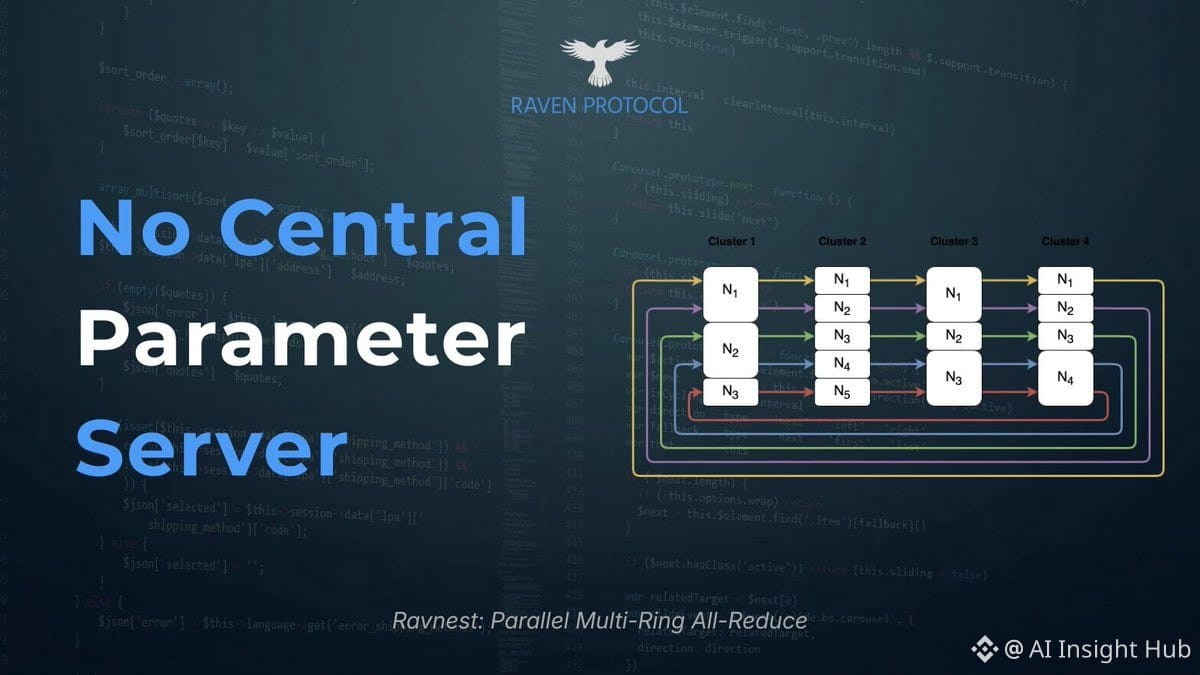
Ring all-reduce lets distributed training nodes sync gradients without a central parameter server. Instead of bottlenecking through one machine, each node passes data to its neighbor in a ring topology.
How it works: Node A sends to B, B to C, C back to A. Each node reduces (averages) incoming gradients with its own, then forwards. After N steps in an N-node ring, everyone has the global average.
Ravnest's twist: parallel multi-ring all-reduce. Run multiple rings simultaneously across the same cluster. Splits the parameter space into chunks, each chunk gets its own ring. Reduces communication rounds and scales better when you have 100+ workers.
Why it matters: Training large models across commodity hardware without AWS-scale infrastructure. No single point of failure, better bandwidth utilization than star topology.
How it works: Node A sends to B, B to C, C back to A. Each node reduces (averages) incoming gradients with its own, then forwards. After N steps in an N-node ring, everyone has the global average.
Ravnest's twist: parallel multi-ring all-reduce. Run multiple rings simultaneously across the same cluster. Splits the parameter space into chunks, each chunk gets its own ring. Reduces communication rounds and scales better when you have 100+ workers.
Why it matters: Training large models across commodity hardware without AWS-scale infrastructure. No single point of failure, better bandwidth utilization than star topology.